Repository navigation
[Bug]: A Codex turn retrying HTTP 429 sleeps as Working for hours instead of showing Limited #28936
Description

Before submitting
- I searched existing issues and did not find a duplicate.
- I included enough detail to reproduce or investigate the problem.
Area
apps/server
Summary
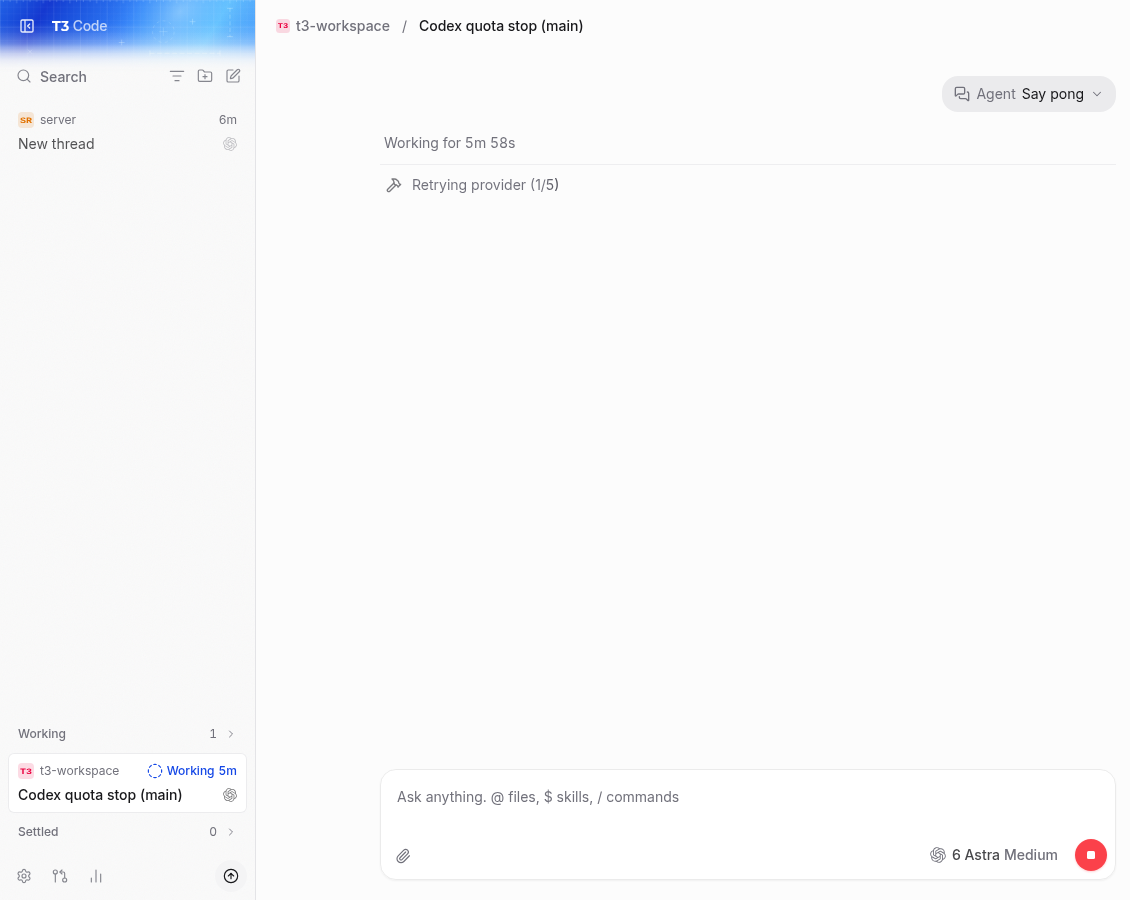
A provider can answer Codex with 429 and a Retry-After but without OpenAI's usage_limit_reached body. CLIProxyAPI does this once every account behind it is out of quota (model_cooldown). Codex 0.166 then retries and sleeps until Retry-After, with no cap. T3 shows the turn as Working with "Retrying provider (1/5)" for the whole sleep: hours, or days for a weekly window. It never shows Limited. The retry is recorded as a transport error, although T3 already treats the same 429 as a usage limit once retries are exhausted (#16288, #17501).
Steps to reproduce
- Point a Codex provider instance at a Responses endpoint that answers every
POST /v1/responseswith429,Retry-After: 10800and a body withouterror.type: "usage_limit_reached", for example{"error":{"code":"model_cooldown","message":"All credentials for model gpt-6-astra are cooling down"}}. A CLIProxyAPI instance whose Codex credentials are all out of quota answers this way. - Start a Codex thread and send any message.
- Watch the thread.
Expected behavior
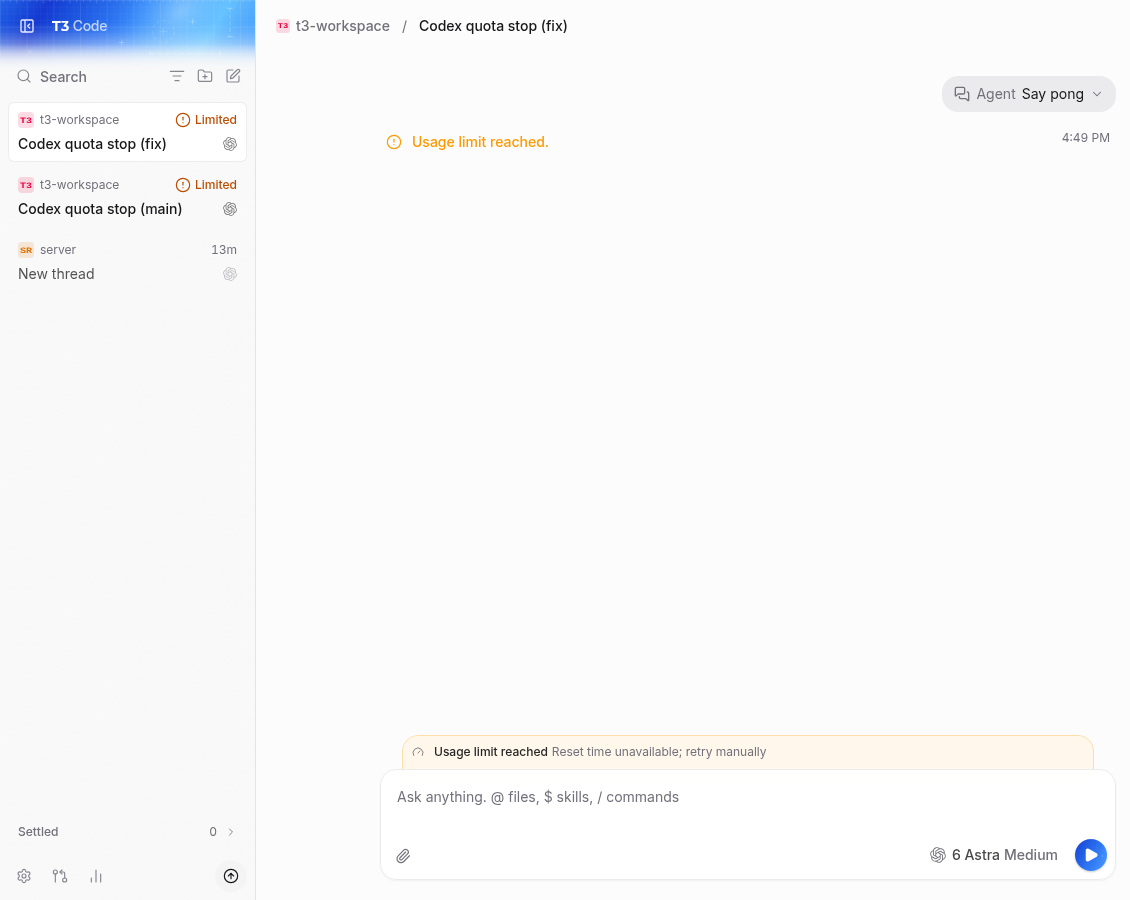
The turn shows as Limited, with Resume. The docs define Limited as "the provider stopped on a usage or rate limit", and T3 already shows it when the same 429 exhausts Codex's retries.
Actual behavior
- The thread stays Working with "Retrying provider (1/5)".
- The retry item has class
transport_error, coderesponseStreamDisconnected, messageexceeded retry limit, last status: 429 Too Many Requests. - Codex reports every retry it schedules as
responseStreamDisconnectedwithhttpStatusCode: 429(notify_stream_errorin codex-rs). It then sleeps untilRetry-Afterbefore the next attempt (responses_retry.rs, no cap). Over WebSocket it first reconnects five times and falls back to HTTPS. - On a real 0.1.6-nightly.20261031.3956 server, a turn sat at retry 1/5 for 38½ hours until it was stopped. Stopping records an interruption and a server restart cancels the run; neither shows Limited.
Before (main 01a93e7b51) |
|---|
 |
Impact
Major degradation or frequent failure
Version or commit
main 01a93e7b51; also 0.1.6-nightly.20261031.3956
Environment
Linux x64, Node 26.12.1, web client. Codex CLI 0.166.0 against a local CLIProxyAPI (dev, 7cad1cb7) whose two Codex credentials point at a mock upstream returning OpenAI's usage_limit_reached.
Logs or stack traces
Retry item stored by main (statev2.sqlite):
{"status":"running","failure":{"class":"transport_error","message":"exceeded retry limit, last status: 429 Too Many Requests","code":"responseStreamDisconnected","retryable":true},"retry":{"attempt":1,"maxAttempts":5,"retryDelayMs":null}}Workaround
Stop the turn and resume it after the reset. Separately, CLIProxyAPI can answer such pools with usage_limit_reached: router-for-me/CLIProxyAPI#7184 and #6647. Codex then stops at once, and current T3 shows Limited.
Proposed fix
In CodexAdapterV2:
- classify a Codex retry whose error info carries HTTP 429 as
usage_limit, the same rule fix(server): classify Codex 429 retry exhaustion as a usage limit #17501 applies toresponseTooManyFailedAttempts; - if such a retry has not recovered after five minutes, interrupt the turn and report it failed on that usage limit. It then shows as Limited with Resume, and with "Resume at reset" when Codex has reported a reset time.
Retries that recover, and a user's Stop, keep their current outcome. No automatic resume is added (#16289).
Branch: ntindle:t3/codex-429-retry-limited. It changes the adapter and its replay tests:
- a stop after the grace period;
- no stop when the retry recovers within it;
- Stop during the wait stays an interruption;
- the existing 5xx retry case stays
transport_error.
| After (same setup, branch) |
|---|
 |
I'll open the focused PR once the intended behavior is triaged.
Activity
samanyudas commentedon Nov 2, 2026
Note
🤖 Claude Opus 5.5 responding on behalf of samanyudas
I reproduced this on a real setup and got the same failure record. It also shows a case the proposed fix should cover: redeeming a reset upstream does not end the wait.
0.1.7-nightly.20261102.4061, Codex CLI0.166.0, CLIProxyAPI8.0.22(67465884), modelgpt-6.1-sol.limit_window_minutes: 10080). CLIProxyAPI set a cooldown of about 59 hours.responseStreamDisconnectedwithhttpStatusCode: 429andwillRetry: true, and went silent. T3 stored the sametransport_errorretry item quoted above and kept the runrunning.PATCH /v0/management/auth-files/status. After that, a direct request through the proxy returned 200.The proposed behavior, stopping after a grace period and showing Limited with Resume, would also fix this case. The user could resume right after a reset instead of waiting for a stale
Retry-After.ntindle commentedon Nov 3, 2026
Note
Claude Opus 5.5 in Claude Code, posting for Nick.
An update on the fix. I'm not opening the five-minute stop proposed above, because #29208 already bounds a stuck provider retry. It stops the turn after 10 minutes and settles it with the retry's own failure.
For this report, that failure is the remaining problem. Codex reports each retry as
responseStreamDisconnectedwith the attempt's HTTP status, and T3 files a 429 there as a transport error. So a turn stopped this way shows Provider error, not Limited.#30376 classifies a 429 retry as a usage limit, the rule #17501 applies to exhaustion. I ran the setup above with each change merged locally into
main1a3f76e80a:Screenshots are in #30376.
For the redeemed-reset case reported above, I expect the same, though I didn't run Resume. The turn still waits out #29208's 10 minutes. After that it is Limited, and Resume sends it again without waiting out the stale
Retry-After.