


GEA: Decomposing GNN embeddings with Graph Explainable Attribution
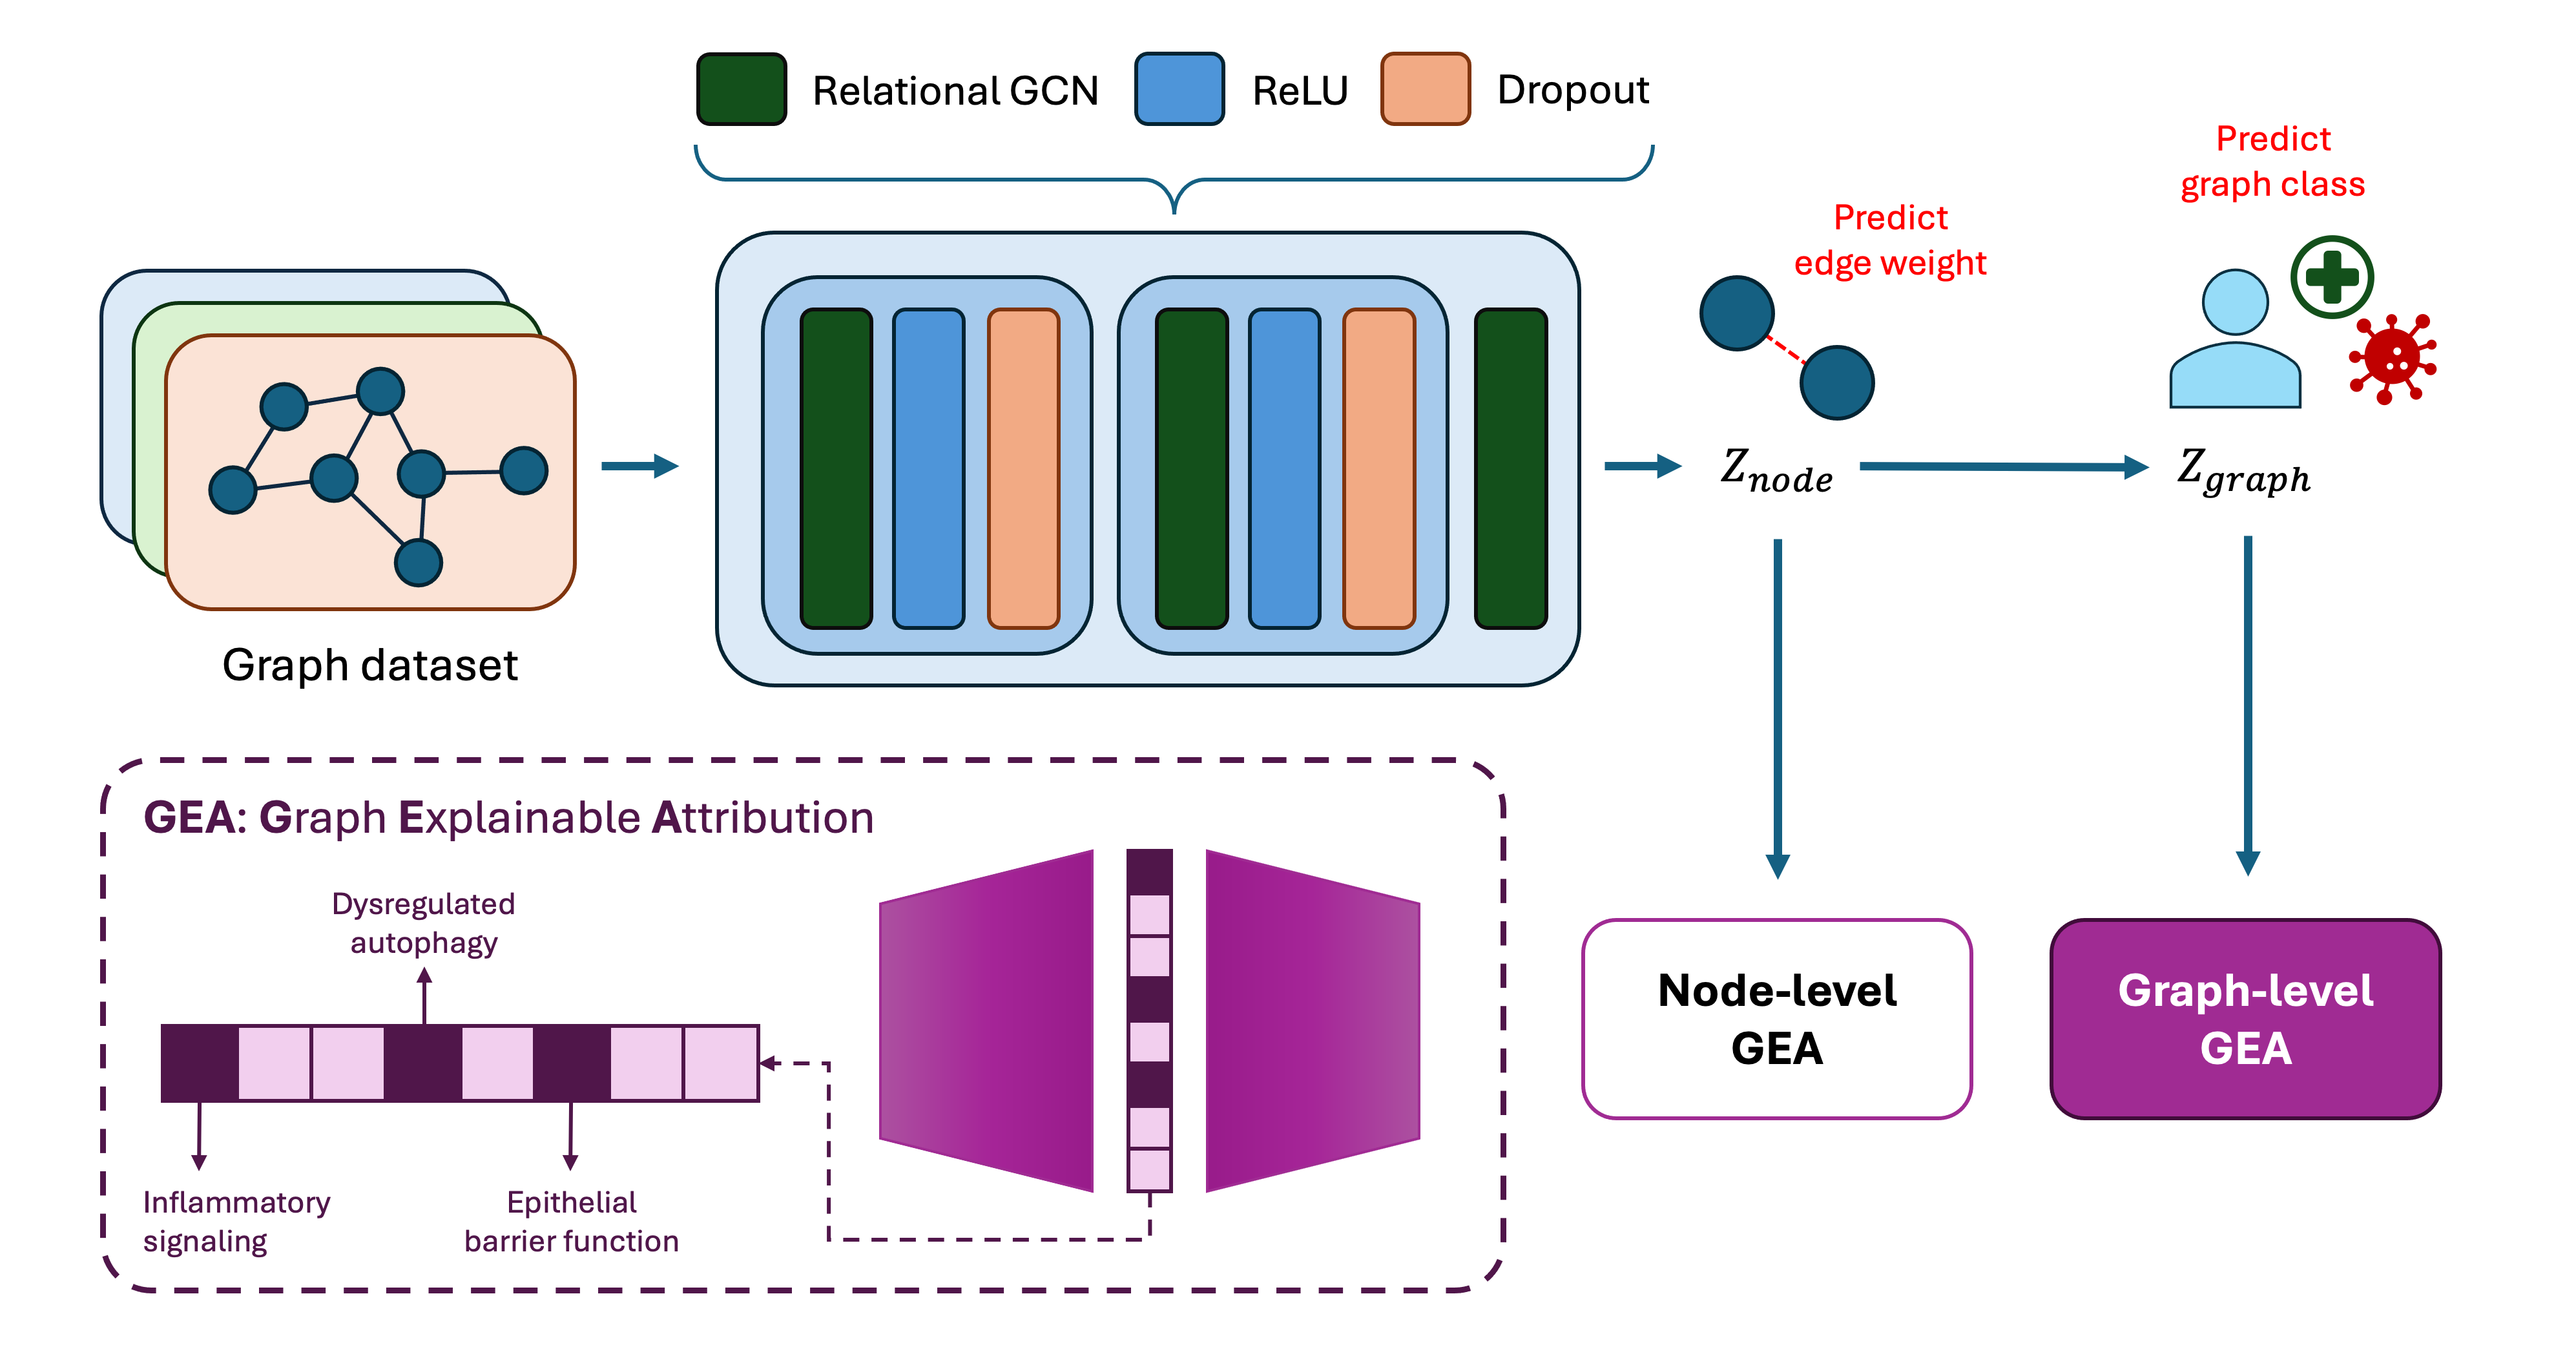
GEA is a framework for decomposing embeddings generated by a trained Graph Neural Network (GNN) model to give relevant biological insights at the node, edge and graph level. Sparse Autoencoders are employed in the framework, in which its sparse features activation can serve as actionable insights on how the internal mechanisms of the model represents information.
An overview of the workflow can be found below:
The project environment can be recreated using the provided Conda environment file.
Make sure Conda is installed, then run:
conda env create -f environment.ymlThis will create the environment with the required dependencies.
Activate the environment using:
conda activate geaYou can check that the environment is correctly installed with:
conda env listThe gea environment should be listed as the active environment.
If the environment.yml file is updated, update the existing environment with:
conda env update -f environment.yml --pruneThe --prune option removes packages that are no longer specified in the environment file.
Tip
It is recommended to install GEA inside a virtual environment to manage depenendencies and avoid conflicts with existing packages. You can use the virtual environment manager of your choice, such as poetry, conda, or pipenv.
You can install the package for development by cloning this repository and running the following command:
Warning
We assume you are in the root directory of the cloned repository when running this command. Otherwise, you need to specify the path to the gea directory.
pip install -e .GEA's workflow consists of three stages:
- Train a Sparse Autoencoder (SAE) on a training set of embedding vectors (e.g., node-, edge-, or graph-level embeddings).
- Annotate the learned SAE features using a validation set and the corresponding concept annotations.
- Evaluate the learned features on an independent test set.
Annotations provide a way to associate SAE features with domain-specific concepts. The type of concepts used for annotation depends on the application domain (see GEA applied to molecules for an example based on molecular motifs).
The SAE training script expects an .npz file containing the following entries:
embeddings: a NumPy array of shape(N, D), whereNis the number of embedding vectors andDis the embedding dimension.annotations: a NumPy object array of lengthN. Each element is a dictionary mapping concept names to labels associated with the corresponding embedding.entities: an identifier associated with each embedding (e.g., a molecule identifier or SMILES string).prediction: the model prediction associated with each embedding.target: the ground-truth label associated with each embedding.
All entries must have the same number of samples, and the i-th element element of each entry must correspond to the same sample. For example:
embeddings[i], annotations[i], entities[i], prediction[i] and target[i] all describe the same sample.
The SAE training script supports both graph-level and node-level embeddings through the --level argument.
For graph-level embeddings, samples are randomly divided into training, validation, and test sets according to the proportions specified by --splits.
For node-level embeddings, the split is performed at the entity level. All embeddings associated with the same entity are assigned to the same split, preventing embeddings from the same graph from occurring in different splits.
By default, the data are divided into 80% training, 10% validation, and 10% test sets. The random seed can be controlled using --seed.
To train an SAE, run:
python scripts/gea/train_sae.py \
    --embeddings_path node_embeddings.npz \
    --d_z 1200 \
    --epochs 50 \
    --level node
To see all available command-line arguments, run:
python scripts/gea/train_sae.py --helpThe second and third stages of the GEA workflow, feature annotation and evaluation, can be performed using:
python scripts/gea/gea_pipeline.py \
    --embeddings_path node_embeddings.npz
This script requires the dataset splits generated during SAE training. The splits are saved by train_sae.py and are loaded from the same path by default. If a different location was used during training, it can be specified using --splits_path.
For the molecular use case with graph embeddings, use the --is_molecular_graph argument.
By default, the results are saved to:
gea_annotation_results.pt
A different output location can be specified using the --results_path argument.
To see all available command-line arguments, run:
python scripts/gea/gea_pipeline.py --helpGEA has been applied to embeddings obtained using a fine-tuned version of GROVER trained to predict solubility from molecular structures.
The embedding file is a Python dictionary in which each key corresponds to a molecule represented as a SMILES string. Each value is a dictionary containing the following embeddings and metadata:
atom_from_atomatom_from_bondbond_from_atombond_from_bondgraph_from_atom_from_atomgraph_from_atom_from_bondpredictiontarget
The embeddings represent different molecular entities and can subsequently be converted into the standardized .npz format required by the general GEA workflow.
Once the embeddings have been obtained, a molecular motif dictionary can be created by running:
python scripts/gea_molecules/create_motif_dict.pyBy default, the motif dictionary is saved as:
dict/motif_dictionary.pkl
This dictionary can be expanded or modified to include additional molecular concepts.
Given the embedding file and the motif dictionary, molecular embeddings can be annotated and prepared for SAE training using:
python scripts/gea_molecules/motifs_annotation.py \
    --embeddings_path grover_embeddings_solubility.pt
This script generates the .npz files containing embeddings, annotations, and additional metadata required for the GEA workflow.
By default, motifs_annotation uses atom_from_atom embeddings for nodes and graph_from_atom_from_atom embeddings for graphs. These can be changed using the --embedding_key_node and --embedding_key_graph arguments.
To see all available command-line arguments, run:
python scripts/gea_molecules/motifs_annotation.py --helpOnce the data have been prepared, the SAE can be trained using the molecular-specific training script. Molecules are split using a scaffold-based splitting approach to ensure that molecules with similar structural scaffolds are not distributed across the training, validation, and test sets.
python scripts/gea_molecules/train_sae.py \
    --embeddings_path node_embeddings.npz \
    --d_z 1200 \
    --epochs 50
The annotation and evaluation stages can then be performed using gea_pipeline as described above.
The code in this repository is licensed under the MIT License, allowing you to use, modify, and distribute it freely as long as you include the original copyright and license notice.