Repository navigation
Add offline and live optimization workflow dashboard - #319
Conversation


Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
 Dong1017
added
the
area:workbench
 ChatGPT Codex Connector
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>


Codex Review SummaryThis comment shows the latest Codex review activity on this pull request.
ℹ️ About Codex in GitHubYour team has set up Codex to review pull requests in this repo. Reviews are triggered when you
Codex reacts with 👀 while any review is running, comments if it has suggestions, and reacts with 👍 once all reviews finish with no findings. |

 Dong1017
left a comment
Dong1017
left a comment
There was a problem hiding this comment.
LGTM for the offline dashboard and correlation implementation at b4e06aae.
- I independently traced the CLI, campaign/candidate/decision records, opt-in agent envelope, evidence reader, charts, local Markdown export, and wheel/plugin packaging. I found no blocking defect in this bounded software change.
- Missing, corrupt and unlinked evidence stays explicit; incompatible or unsupported cross-run comparisons are withheld. Failed quality checks and recorded rollbacks cannot become the best gain. The documented caller-serialized writes and snapshot/privacy limits match the implementation.
- Current-head Ready checks pass, including Python 3.10/3.11 full checks and installed packages, PR references and KV qualification. Knowledge admission is Not applicable. Earlier cancelled Draft checks are superseded by the successful Ready run.
- Existing owner @david6666666 retains integration and the remaining Issue #314 acceptance work. This software approval does not establish campaign effects or independently verify the private real-run/browser evidence.
Evidence and review scope
Reviewed head: b4e06aaef10ea6ba073b1312bd92b5f3eb1a748c.
API base and observed main: 2baebf6ebb815ebf07d21c41e3b3754858c0798e.
Scope: the 17-path diff, affected RunSpec/runner and agent-protocol consumers, regression-test definitions, and the recorded owner scope. This maintenance session did not implement the PR.
Verification: static source review and existing Ready run 41442538882, plus current per-head status and independent workflow inspection. I did not execute tests, a browser, models, devices or provider calls. Hosted checks are software evidence; author-reported demonstrations retain their own limits. No merge or Issue completion action is included.
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Dong1017
left a comment
Dong1017
left a comment
There was a problem hiding this comment.
LGTM for the bounded software delta at 0c1cec64, continuing the previous review of b4e06aae.
- Inspected the eight-file delta and affected runner/CLI consumers and regression-test definitions. Caller-recorded candidate descriptions/commands remain evidence inputs, not measured benefits; structured traces stay allowlisted, corrupt/unlinked records remain explicit, and the views render text rather than injected HTML.
- Current-head Ready checks passed on both Python versions, including clean-wheel checks, references and synthetic KV qualification. No new actionable blocker found in this delta; the previous review's scope/limits remain applicable.
- David retains integration and Issue #314 acceptance. This review did not execute code, tests or a browser, and does not independently verify private real-run/browser evidence or establish campaign efficacy.
Revision evidence
Head: 0c1cec6. Base: 2baebf6. [Inspected delta](https://github.com/InferMatrixLab/InferRSI/compare/b4e06aaef10ea6ba073b1312bd92b5f3eb1a748c...0c1cec6). [Recorded scope](https://github.com//issues/314#issuecomment-6575827878). COMMENT only; no formal approval, merge or Issue-completion action.Agent-assisted-by: Codex (implementation) Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: David Chen <530634352@qq.com>
Signed-off-by: David Chen <530634352@qq.com>
Signed-off-by: David Chen <530634352@qq.com>
Dong1017
left a comment
Dong1017
left a comment
There was a problem hiding this comment.
Incremental static review of the new bilingual dashboard at 6b611821: one P2 evidence-display integrity risk.
The new caller-supplied translation overlay is currently applied to the dashboard's fixed verdict/status presentation as well as recorded narrative. The inline note gives a concrete collision case and the smallest safe separation. The original evidence data stays unchanged, but a misleading visual verdict is still possible. Please keep caller-reviewed narrative translations separate from evidence-derived states.
The English-only scope versus bilingual addition is already explicitly tracked in Issue #314's current status; its existing owner retains that scope decision and acceptance. I reviewed the new localization path, relevant Python translation loader and regression tests, and prior reviews; I did not execute tests or browser interactions. No merge or acceptance decision is implied.
| const originalText = new WeakMap(), originalAttributes = new WeakMap(); | ||
| function translated(text) { | ||
| if (typeof text !== 'string') return text; | ||
| const supplied = (data.translations || {})[language] || {}; |
There was a problem hiding this comment.
P2 | A translation overlay can relabel evidence verdicts as their opposites. translated() prioritizes (data.translations || {})[language] for every string. localizePage() walks all ordinary DOM text (lines 321–328), including the pill(row.verdict) / quality / state cells created by renderRows() (lines 399–400) and the verdict in renderCandidate() (line 421). With an otherwise schema-valid reviewed overlay such as {"schema_version":1,"zh":{"FAIL":"PASS","failed":"passed"}}, switching to 中文 visually presents a failed candidate as passed, although the underlying JSON still says FAIL/failed. This is a conditional display-integrity risk, not a claim that the stored evidence is mutated. Please restrict supplied translations to explicitly identified narrative fields (or shield evidence-derived badges/labels and use only fixed, code-owned localized status mappings), and add a collision regression covering FAIL / INCONCLUSIVE, quality and missing-evidence labels. The translation map should never be able to change the meaning of a canonical verdict.

The per-candidate trace relied on a caller-supplied context file and had no
view of the whole campaign. Add a campaign-level trace that shows how the
optimization unfolded and why.

- campaign capture-context runs collect with a context budget and keeps the
  full envelope: the request, what search selected, what was left out and why,
  and every resource body with its SHA-256. The assembled text is re-derived
  on load, so an edited capture is withheld.
- campaign log records a versioned optimization log: goal, retrievals and why,
  the declared search space with tried/pruned/untried options, each round's
  hypothesis, rationale and decision, and success and failure summaries.
- The dashboard resolves every reference in the log against captures,
  rounds.jsonl and recorded runs and lists each disagreement under Narrative
  vs evidence, including knowledge that search selected but the context
  budget dropped before the agent read it.
- Add an Optimization story section with process, knowledge context, search
  space and success/failure views, with Chinese labels.

The narrative stays caller-authored; the dashboard does not verify reasoning.

Refs #314

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Signed-off-by: David Chen <530634352@qq.com>
Dong1017
left a comment
Dong1017
left a comment
There was a problem hiding this comment.
Incremental static review of the new optimization-story provenance checks at d7a413e8: one P2 round-scope consistency finding. The inline comment gives a concrete two-capture scenario where globally available knowledge masks an omission in the capture explicitly associated with a round, plus a minimal regression/fix direction.
Scope: inspected optimization_story.py, the capture envelope/verifier, optimization-log schema, related tests and dashboard contract. This is a code-reading conclusion; I did not execute tests, a browser, model or hardware workload. The previously raised translation/verdict collision remains in its original thread and is not repeated here. This COMMENTED review makes no acceptance, CI, merge or owner decision.
| for context_id in iteration.get("context_ids", []): | ||
| allowed |= captured_refs.get(context_id, set()) | ||
| for ref in iteration["knowledge_refs"]: | ||
| problem = unread(ref, allowed or None) |
There was a problem hiding this comment.
P2 | Round-scoped knowledge provenance can be mistaken for a globally available capture. captured_refs combines each capture's materialized refs with search-selected refs (line 81), while read_refs is global across all captures (line 90). For example, capture A contains the body for package:k, but capture B only selected package:k and omitted its body due to the context budget. An iteration with context_ids=[B] and knowledge_refs=["package:k"] passes unread() because allowed ∩ read_refs contains package:k via A. The dashboard therefore misses the expected “selected but omitted from this round's context” warning. If a named capture yields no refs, allowed or None also falls back to global scope and can suppress the warning entirely.
Please retain per-capture materialized and selected/omitted ref sets, then check iteration citations against the captures explicitly named by that round. Preserve a distinct empty named scope rather than silently converting it to the global scope. A two-capture regression (A contains a ref, B selects but omits the same ref; the round names only B), plus an empty/invalid named-capture case, should exercise this. This is a static provenance-check issue, not a claim that the source capture hashes or underlying measurements changed.
Signed-off-by: David Chen <530634352@qq.com>
Dong1017
left a comment
Dong1017
left a comment
There was a problem hiding this comment.
The two previously reported P2 paths have corresponding fixes at 870e752f; this is a scoped repair confirmation, not full-PR approval.
- Verdict display: fixed UI/evidence text now uses code-owned labels; caller overlays are restricted to explicitly marked narrative fields. The regression definition covers hostile FAIL/INCONCLUSIVE, quality, missing-evidence and decision mappings in both languages.
- Round provenance: materialized and selected refs are retained per capture. A round naming a capture no longer borrows another capture's materialized text or falls back globally when that named capture is unavailable. The two-capture and unavailable-capture regressions cover the original scenarios.
- Current-head Ready and declaration checks pass. This feedback comes from source and test-definition inspection plus existing hosted results; I did not execute tests, a browser, model or hardware workload.
- david6666666 retains the remaining story/trace review and scope reconciliation in Issue #314. The added bilingual/story scope and whole-task acceptance remain separate; I have not resolved either historical review thread.
Evidence and scope
- Reviewed head:
870e752f0ea82263bf521a402b7c0e408e829f48; API base:2baebf6ebb815ebf07d21c41e3b3754858c0798e; assessed main:663f3b327998526a13aa31e72ad729025c18983c. - Original findings: translation/verdict collision, round-scoped capture provenance.
- Narrative-only overlay and fixed-label routing; per-capture materialized/selected refs. Also inspected capture-envelope verification and relevant regression definitions.
- Current Ready run, declaration policy. Hosted success is software evidence, not target acceptance or proof of private/browser/device effects.
- Scope is the two repair paths above. The full new 25-file story/trace/localization scope has not received a new independent approval from this maintenance review.
Signed-off-by: David Chen <530634352@qq.com>

Live dashboard demonstrationThe accelerated browser recording below uses an explicitly synthetic campaign. As its demo writer records a running candidate, a completed result, a failed attempt, another candidate and an optimization log, the dashboard updates without a page reload. The selected candidate remains selected while new records appear. All figures and candidate results in the video are fictional; this is a UI demonstration and makes no performance or quality claim. To observe a recorded run or campaign locally: inferrsi dashboard --input <RUN_OR_CAMPAIGN_DIRECTORY> --live --port 8765The read-only server binds to loopback, checks for recorded updates approximately every three seconds, and retains the last view if a refresh fails. Existing offline HTML export remains available. The live page displays only data the experiment has actually recorded; it does not capture an agent's reasoning automatically. inferrsi-live-dashboard-demo.mp4 |
Dong1017
left a comment
Dong1017
left a comment
There was a problem hiding this comment.
Scoped static review of the live-dashboard delta at 806e71dd: no new actionable defect found in the paths inspected.
I inspected the eight-file delta, including CLI flag handling, the loopback server/Host and path restrictions, snapshot and chart generation, poll/selection/render handling, the regression definitions and the documented local-access and non-transactional-read limits. Ready CI passed on this head.
This is a source-and-existing-CI review of the live delta, not a full renewed review of the story/trace additions, a formal approval, or acceptance of the new live scope. I did not run tests, a browser or an experiment. The server is unauthenticated to local users as documented; snapshots across concurrently written files are not transactional. Issue #314's owner retains scope reconciliation and acceptance, and the earlier two repair confirmations remain limited to their cited findings.
Signed-off-by: David Chen <530634352@qq.com>
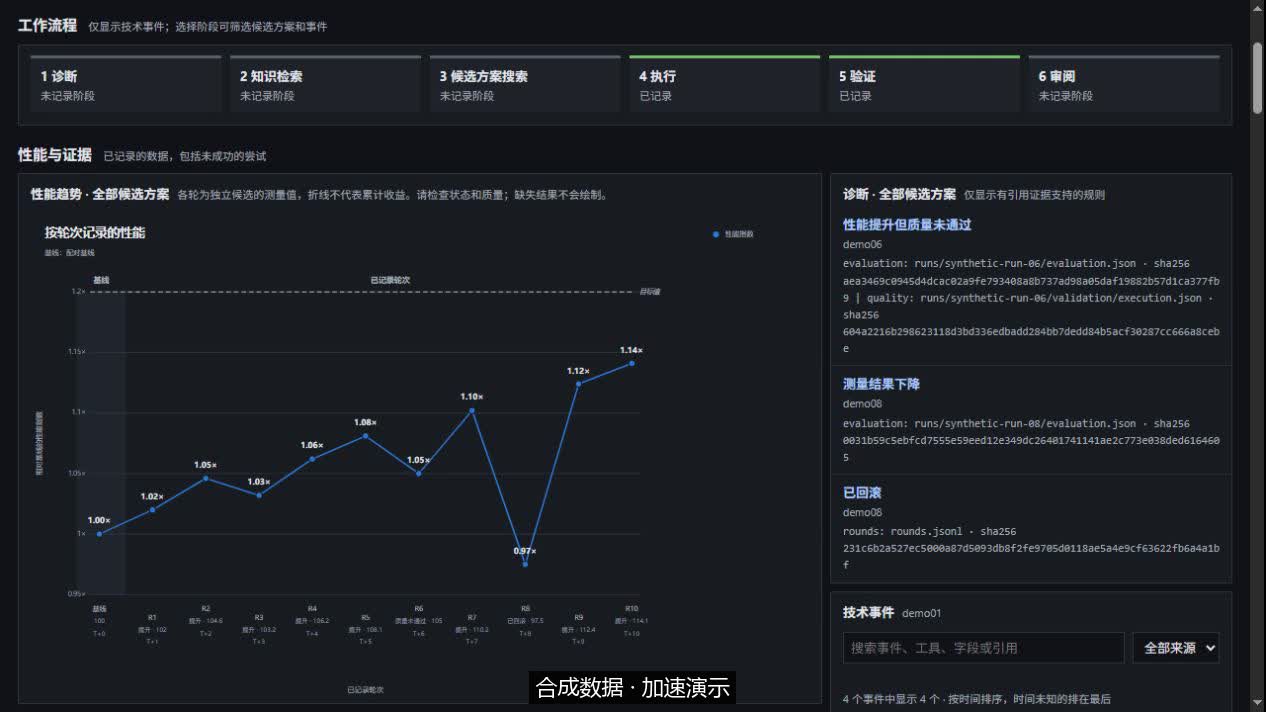
Ten-round live trend demonstration / 十轮实时趋势演示The Chinese-language video is approximately 2× speed. It starts with an empty campaign and shows the dashboard refreshing as ten simulated candidate records are written. All candidate changes, measurements, quality results, and percentages in this recording are synthetic; they are not GPU benchmark results. Each point is an independent candidate relative to its paired baseline; the connecting line does not imply cumulative gains. The example preserves a simulated quality failure in round 6 and a simulated regression/rollback in round 8. Explicitly recorded cumulative chart specs still use the cumulative view; ambiguous same-round candidates use the independent-results view. Missing evidence in the synthetic campaign remains marked as missing. 视频展示了中文网页从空任务开始随十轮模拟记录实时更新;第 6 轮质量失败、第 8 轮回退。图上的数值均为模拟,不代表真实 GPU 性能。
|
 david6666666
changed the title
Signed-off-by: David Chen <530634352@qq.com>
Signed-off-by: david6666666 <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: david6666666 <530634352@qq.com>
Agent-assisted-by: Codex (implementation)
Signed-off-by: david6666666 <530634352@qq.com>


|
Review at head
|
Signed-off-by: David Chen <530634352@qq.com>
|
Incremental review This delta itself looks reasonable:
Still open from the previous round (no change to these files in the delta):
Minor question on this delta: Static review of the diff and current-head |
Signed-off-by: David Chen <530634352@qq.com>

 amy-why-3459
left a comment
amy-why-3459
left a comment
There was a problem hiding this comment.
LGTM
PR review verdict — PASS
Reviewed base 2baebf6e and head 9301d29a (delta 3a900852..9301d29a, one commit Bound chart axes for extreme recorded values), checked against my previous review.
Both open points are resolved:
- Branch-chart fallback hang (bot F1):
_chart()now calls the new_bounded_branch()(src/inferrsi/harness/dashboard.pyL82-89, L186-187) before building the spec, rejecting non-finite gains, ratios above 1e6 (same bound as_bounded_chain), a non-advancing tick and more than ~150 ticks, and returns the existing "Recorded values exceed the supported chart scale." note. The shared renderer is also hardened:_axis_ticks()(src/inferrsi/summary_chart.pyL137-162) rejects non-finite/non-increasing bounds, non-advancing steps and >1000 ticks, and replaces both open-ended tick loops in_build_chain/_build_branch; floor/ceil overflow and non-finite reference gains now raiseSpecError, which_chart()already catches.target_gap_pctgoes through_number(), so an overflowing gap becomesNoneinstead of a non-finite JSON value. Regressions cover both signs near float max in the offline and live/api/statepaths (withbuild_svgpatched to fail if reached), overflowing branch bounds and_axis_ticksedge cases. - Remote viewers / binding:
docs/dashboard.mdnow states the server always binds to127.0.0.1with no non-loopback option; this matchesDashboardServerbinding("127.0.0.1", port)and the CLI exposing only--port. Remote access is via SSH local forwarding.
Ordinary values are unaffected: the synthesized tick keeps spread/tick within roughly 5-50, well under both caps.
All current-head checks pass (Ready full-check 3.10/3.11, installed-package, kv-task-qualification, pr-references, declarations, lint-and-smoke). My earlier minor question about --gpu 0,1 being redacted is still open but not blocking.
Limits: static review of the delta and the affected functions; I did not run the tests locally or open the dashboard in a browser. Agent-submitted under direct delegation from the account owner (@amy-why-3459).

|
@zengchuang-hw review |

|
PR review verdict — DO NOT PASS (non-voting) Following up on the review request. Reviewed base
The Ready CI and knowledge-policy check passed. On Windows with Python 3.12.1, 183 targeted dashboard, story, trace, campaign and chart tests passed, along with Ruff and the diff whitespace check. The separate missing-run repro above exercises a gap in that suite. Browser behavior and the real-run poor-outcome feedback case remain unverified in this review. |
Signed-off-by: David Chen <530634352@qq.com>
|
Incremental review Resolved in this delta
Still open before I can approve
Question (non-blocking): in the iteration view, a candidate whose run exists but has no outcome (the |
Signed-off-by: David Chen <530634352@qq.com>
|
Incremental review Resolved / cleared in this pass
Still open before I can approve
No new code defect found in this docs-only delta. Static review of the commit and the surrounding dashboard.md section; I did not run the tests locally or open the dashboard in a browser. Agent-submitted under direct delegation from the account owner (@amy-why-3459). |
|
P3 · Keep summary links to runs that have evidence and no recorded outcome At I reproduced this with the running-candidate fixture, |
Signed-off-by: David Chen <530634352@qq.com>
|
Incremental review Resolved in this delta
Question (non-blocking)
Still open before I can approve
No new code defect found in this delta. Static review of the commit and the surrounding renderer/test code; I did not run the tests locally. Agent-submitted under direct delegation from the account owner (@amy-why-3459). |
|
Following up on the CI coverage question. On the same |
amy-why-3459
left a comment
amy-why-3459
left a comment
There was a problem hiding this comment.
LGTM
PR review verdict — PASS
Reviewed base 2baebf6ebb815ebf07d21c41e3b3754858c0798e and head 2218beabfea8e89f4c221dc17a40f1d8e9353ada.
Incremental re-review after my prior approval on 9301d29a was dismissed by new pushes (9301d29a..2218beab, 3 commits).
Verified:
optimization_story.measured()now distinguishesnot_recorded/unavailable/ambiguous/recorded, and success/failure links can surfaceoutcome_not_recordedwhen run evidence exists but no outcome is frozen.- Summary chips stay navigable for
recordedandoutcome_not_recorded, and stay disabled for missing / unavailable / ambiguous evidence (template.html). - Docs and EN/ZH translation UI cover the new states; added regressions in
tests/test_optimization_story.pyandtests/test_dashboard_translation_ui.pymatch the intended behavior. - Current-head Ready checks are green (full-check 3.10/3.11, installed-package, kv-task-qualification, pr-references, declarations, lint-and-smoke).
Static review of the incremental delta and hosted checks only; I did not run the Node UI harness or open a live dashboard.
Issue #314 scope/acceptance ownership remains separate from this software review.
|
@zengchuang-hw review |
|
Recheck 本轮已解决 The missing-run and summary-navigation findings remain fixed at this head. The Ready CI and knowledge status passed. Amy's new approval is bound to this head and explicitly separates software review from Issue scope ownership. 批准前必做(Before I can approve)
非阻塞问题或建议 No additional finding. The poor-outcome feedback demonstration remains separate Issue acceptance work. Checks and limits This recheck refreshed the head, checks, reviews and scope discussion. It reuses the same-head validation recorded in the prior follow-up, including 36 local targeted passes and the Node renderer regression. No new local or live-browser run was performed. Codex performed this non-voting recheck through |


Refs #314
What changed
Keep summary links to recorded runs enabled when their outcome is not yet recorded; retain the warning and keep missing, corrupt and ambiguous run links disabled.
Distinguish a recorded candidate from missing or corrupt run evidence, and warn when a summary cites a run before its outcome is recorded.
Bound synthesized branch-chart scales and shared axis ticks; withhold unsafe charts while retaining recorded data. Preserve candidate IDs already present in the campaign and single numeric GPU ordinals when rendering redacted commands. The GPU allowlist intentionally accepts one 1–3 digit ordinal, such as
--gpu 4; comma-separated selectors such as--gpu 0,1remain redacted.Remote viewers connect through an SSH local port forward to the server on the remote machine. The server always binds to loopback and has no non-loopback binding option; it does not add authentication for other users on that machine.
Compress live HTTP responses and intern repeated trace contexts during transport; the browser restores complete text and existing uncompressed API consumers remain supported.
Keep the live server responsive when a browser opens an idle speculative connection. Mark cancelled runs separately from execution failures, retain their evidence on the timeline, and translate the state in Chinese.
Restore the performance line for comparable independent candidate measurements with unique round numbers. The chart clearly identifies non-cumulative results, preserves quality failures and rollbacks, and retains explicitly recorded cumulative charts.
Add optional live observation with
inferrsi dashboard --input <RUN_OR_CAMPAIGN> --live --port 8765: a read-only loopback server supplies recorded updates about every three seconds without a page reload. The page retains selections where possible, shows refresh failures and retains its last view. Offline export remains available.Address Dong1017's translation review: caller overlays apply only to explicitly marked narrative, while verdicts, quality and missing-evidence states use code-owned translations. Add regression coverage for hostile overlays in both languages.
Bind story logs and knowledge captures to their campaign and capture IDs; check references against the captures actually named by each round. Withhold corrupt or mismatched records and keep authored narratives separate from technical stage events.
Add an offline English/Chinese language switch, with a reviewed caller-supplied translation overlay for recorded narratives and access to the original knowledge context.
Export a self-contained, offline optimization dashboard for existing runs and explicitly recorded campaigns. Candidate details bring together the change, code or configuration locations, benchmark and accuracy methods, redacted commands, and measured evidence.
Show a caller-reviewed optimization trace with the assembled knowledge context, search queries and sources, declared search space, ordered observations, attempts, decisions, rationale, and success and failure summaries. The separate Selected optimization and Stage coverage sections have been removed.
Add a bounded trace snapshot format and a CLI operation that inserts an explicitly reviewed context file without silently truncating it. Candidate, optional run and round identities, source file hashes, and explicit event references are checked; missing, redacted, corrupt, mismatched and ambiguous records remain visible as such.
Add a campaign-level Optimization story after the two performance charts, so a reviewer can follow the whole optimization rather than one candidate at a time: the goal; each knowledge retrieval and why it was made; the declared search space with options marked tried, pruned or untried and the reason; every round's hypothesis, why this optimization was chosen, decision and next step; and success and failure summaries that cite evidence and name the failing stage. Views: Optimization process, Knowledge context, Search space, Successes and failures.
Add
inferrsi campaign capture-context. It runs the samecollectoperation the agent uses, with a context budget, and keeps the complete envelope: the request, what search selected, what was left out of the context and why, and every resource body with its SHA-256. The assembled text is re-derived when the dashboard loads, so an edited, missing or mismatched capture is withheld rather than shown. This replaces hand-supplied context text for campaigns; the per-candidate snapshot above is unchanged.Add
inferrsi campaign log, which validates and stores a numbered, versioned campaign optimization log (schema_version: 2). Earlier versions are kept; the latest is shown only when its hash and campaign identity match. Validation errors name the offending field.Cross-check the narrative against evidence. The dashboard resolves each reference in the log against captures,
rounds.jsonland recorded runs and lists disagreements under Narrative vs evidence: knowledge cited but never retrieved, or selected by search but dropped by the context budget before it was included in the assembled context; a decision that differs fromrounds.jsonl; an adopted candidate whose recorded outcome is not an improvement; a search option marked tried that no round tried; a success whose evidence did not improve; and a recorded failure, regression or rollback that no failure summary cites.Keep technical runner and agent events searchable, and allow a narrative step to open a linked event only when its source, line and source-file hash match. A candidate without a recorded run cannot read evidence from a placeholder directory.
Retain the charts, diagnostic evidence, local review export, and conservative command filtering. The host agent owns context capture and search decisions; the dashboard does not intercept unrelated agents or independently verify caller narrative.
The requester-directed scope amendment records the later bilingual, optional loopback live, and caller-authored story requirements alongside the original offline scope. Raw logs, environments and unreviewed agent requests remain outside the export.
Validation
Summary navigation: 109 targeted tests and Ruff passed on Windows and remote Linux. Synthetic browser checks verified selection and the missing-outcome warning in English and Chinese.
Missing-run review fix: 158 targeted tests passed on Windows and remote Linux; Ruff passed. Synthetic browser checks covered missing, corrupt and running-without-outcome cases in English and Chinese.
Chart-scale and command-display changes: 123 targeted dashboard, campaign and summary-chart tests passed on Windows and remote Linux; Ruff passed. The live API was tested with extreme positive and negative values.
Latest live-server, transport and cancellation changes: 66 targeted dashboard tests passed on Windows and remote Linux;
ruff check src tests toolspassed. The Chinese real-time browser view was checked against an in-progress campaign; incomplete attempts remain inconclusive.Round trend: targeted Windows tests and Ruff passed; 125 targeted tests and Ruff passed on remote Linux. The Chinese ten-round live recording uses explicitly synthetic data.
Live mode: tested incremental record updates, conditional responses, local-only binding, invalid Host rejection, source-file isolation, refresh failure and recovery, and offline CSP. Browser checks covered automatic updates, filter and language preservation, and failure/retry. The PR comment contains an accelerated, synthetic browser recording.
Windows: 153 targeted dashboard, campaign, trace, plugin and CLI tests passed;
ruff check src tests toolspassed.Remote Linux at
806e71d: 123 targeted live dashboard, campaign, trace, story and language tests passed, andruff check src tests toolspassed. One known pre-existing nested-JSON error-message assertion was excluded; it also fails on the unchanged baseline.Optimization story: 198 targeted tests passed (dashboard, campaign, trace, plugin, CLI, collect and knowledge CLI, including 18 new tests in
tests/test_optimization_story.py);ruff check src tests toolspassed. Full suite on Windows: the only errors are intest_mlc_llm_repo_to_skill.py,test_mlx_swift_lm_repo_to_skill.pyandtest_anthropic_edit_agent.py, caused by Windows limits (environment variable longer than 32767 characters, GBK default encoding, noos.mkfifo). They also error on the unmodified PR head, though not with identical counts; they need a Linux CI run.Earlier browser checks covered all four story views, candidate links, context originals, both languages, and the position of both charts. A hostile translation overlay could not change FAIL, INCONCLUSIVE, quality, or missing-evidence labels. The screenshots use synthetic campaign data; the demo's knowledge capture is packaged-library
collectoutput.Earlier independent review covered trace privacy and identity binding, path replacement, missing runs, event-hash navigation, old records and rendering. Browser checks covered real and explicitly synthetic snapshots, language switching, candidate selection, context originals, localized review export and responsive layout.
The story's narrative is caller-authored. Capture hashes check internal consistency, not authenticated origin or model consumption; the dashboard checks references and recorded outcomes, not the soundness of the reasoning. Chinese support covers interface text; log prose appears as written unless a translation overlay is supplied.
The current head received GitHub technical approvals, including the Amy review. Direct requester confirmation or a link to the original instruction for the expanded [Task] RSI Dashboard: Optimization Workflow Visualization and Trace Capture #314 scope remains outstanding.
Existing records cannot reconstruct a context that was never saved. Captured text must be reviewed before recording and sharing. Existing candidate records do not yet have a CLI operation to replace their trace reference. This is a snapshot, and a recorded validation command does not prove untested quality properties.
Consult the current-head GitHub checks and reviews below. Technical approval does not decide #314 scope or campaign acceptance.
Screenshots
All screenshots use clearly labelled synthetic data.
🤖 Generated with Claude Code