Repository navigation
mnist
The Modified National Institute of Standards and Technology (MNIST) database is a large database of handwritten digits that is commonly used for training various image processing systems. The database is also widely used for training and testing in the field of machine learning.
The MNIST dataset contains 60,000 training images and 10,000 testing images. Each image is a 28x28 grayscale image, associated with a label from 10 classes, indicating digits from 0 to 9.
The dataset provides a ground truth for each image, in other words, it tells us what digit each image is meant to represent. This makes it a perfect dataset for supervised learning tasks in machine learning, especially for beginners who are just getting started.
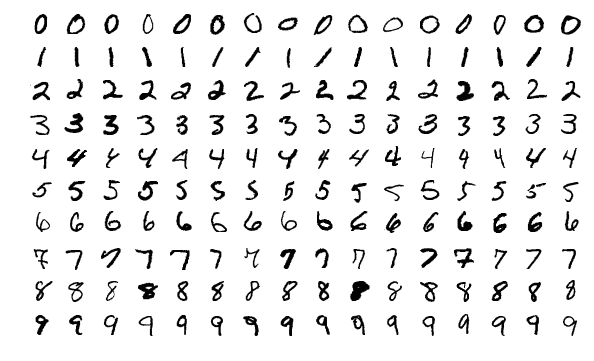
Each image in the MNIST dataset is a 28x28 grayscale image. The pixels are represented as a flattened array of 784 (28*28) elements, each representing a pixel intensity from 0 (black) to 255 (white).

The labels are encoded as integers corresponding to the digit the image represents. For example, this case means that the associated image represents the digit 7.
The specific formats and structures of the dataset is shown below:
 Extracted from the oficial MNIST dataset page
Reading MNIST data files has become a challenge among artificial intelligence enthusiasts to see who can achieve the highest level of efficiency in digit detection and the lowest error percentage.
There be different IA methods used to detect the digits, but the most common one is the Backpropagation algorithm. This algorithm is used to train a neural network to recognize the digits in the images. You can read more about this on our Neural Network Implementation page.
MNIST data is typically stored in a byte format that needs to be read and converted into images and labels that we can use in our machine learning models. In our project, we use the MNIST Reader to load this data and convert it into a usable format. You can find more information about how we do this on the MNIST Reader page.
In the MNIST++ project, we use this dataset as the basis for our digit recognition system. We use the training images to train our neural network, and then use the test images to evaluate the performance of our network.
The dataset is first preprocessed using our Digit Image Processing module to normalize the pixel values and possibly perform other transformations. You can find more about how we process our images on the Digit Image Processing page.
The processed data is then fed into our Neural Network where we use the Backpropagation algorithm to adjust the weights of the network based on the error of the output. You can read more about this on our Neural Network Implementation page.
Finally, we use the trained network to make predictions on the test set and evaluate the performance of our network.