diff --git a/README.md b/README.md
index eaf50a7..3628e18 100644
--- a/README.md
+++ b/README.md
@@ -714,12 +714,45 @@ from ds_utils.unsupervised import plot_loss_vs_cluster_number
data = pd.read_csv(path / to / dataset)
plot_loss_vs_cluster_number(data, 3, 20, euclidean)
-
plt.show()
```
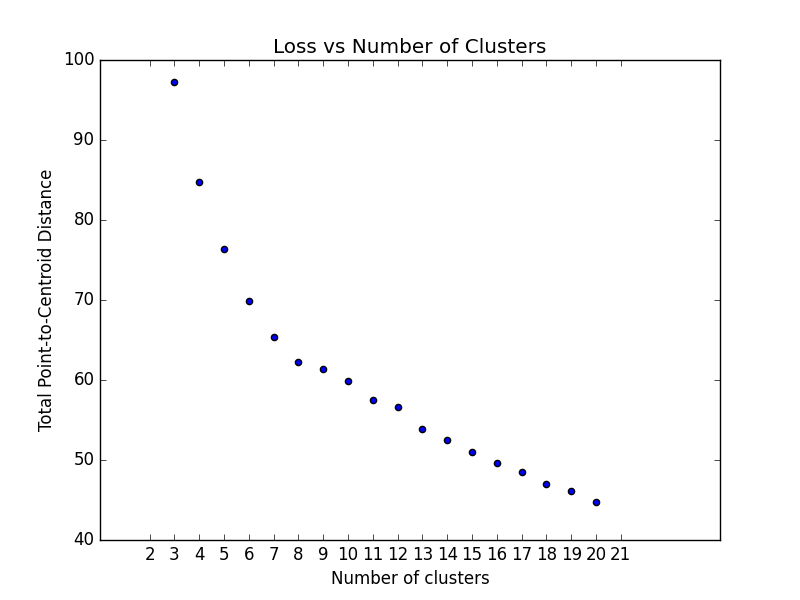
+### Plot Clusters
+
+This method creates a 2D scatter plot of clustering results. Each cluster is shown
+in a distinct color. For high-dimensional data (more than 2 features),
+dimensionality reduction is applied automatically. Supports PCA (default), t-SNE,
+and UMAP. Cluster centroids can optionally be displayed.
+
+Available in both matplotlib and Plotly backends.
+
+> **Note:** UMAP requires the optional ``umap`` extras: ``pip install data-science-utils[umap]``
+
+**Matplotlib:**
+```python
+from ds_utils.unsupervised import plot_clusters
+from sklearn.cluster import KMeans
+from matplotlib import pyplot as plt
+
+estimator = KMeans(n_clusters=8, random_state=42)
+estimator.fit(data)
+
+plot_clusters(data.values, estimator.labels_, estimator.cluster_centers_)
+plt.show()
+```
+
+**Plotly (interactive):**
+```python
+from ds_utils.unsupervised import plot_clusters_plotly
+
+fig = plot_clusters_plotly(data.values, estimator.labels_, estimator.cluster_centers_)
+fig.show()
+```
+
+
+
## XAI (Explainable AI)
## Plot Feature Importance
@@ -921,6 +954,12 @@ For NLP features (``SentenceEmbeddingTransformer``), install with the optional `
pip install data-science-utils[nlp]
```
+For UMAP-based cluster visualization (``plot_clusters(..., reduction_method="umap")``), install with the optional ``umap`` extras:
+
+```bash
+pip install data-science-utils[umap]
+```
+
## Staying Updated
diff --git a/docs/source/installation.rst b/docs/source/installation.rst
index 3a95abc..19787c1 100644
--- a/docs/source/installation.rst
+++ b/docs/source/installation.rst
@@ -34,6 +34,7 @@ installer |pypi_version|::
To install with optional dependencies (like NLP features that require ``sentence-transformers``), use the extras syntax::
pip install "data-science-utils[nlp]"
+ pip install "data-science-utils[umap]"
To upgrade Data Science Utils to the latest version, use::
@@ -51,6 +52,7 @@ If you prefer to install from source, you can clone the repository and install |
To include optional dependencies when installing from source, use::
pip install ".[nlp]"
+ pip install ".[umap]"
Alternatively, you can install directly from GitHub using pip::
@@ -73,7 +75,7 @@ Note on Dependencies
Data Science Utils has several core dependencies, including numpy, pandas, matplotlib, plotly and scikit-learn. These will be
automatically installed when you install the package using the methods above.
-Optional features (such as ``SentenceEmbeddingTransformer``) require additional dependencies (``sentence-transformers``) which must be installed explicitly using the ``[nlp]`` extra or separately via conda.
+Optional features require extra dependencies: ``SentenceEmbeddingTransformer`` needs ``sentence-transformers`` (``[nlp]`` extra), and UMAP cluster visualization needs ``umap-learn`` (``[umap]`` extra).
Staying Updated
===============
diff --git a/docs/source/metrics/regression.rst b/docs/source/metrics/regression.rst
index 521e367..b3d164c 100644
--- a/docs/source/metrics/regression.rst
+++ b/docs/source/metrics/regression.rst
@@ -4,7 +4,7 @@ Regression Metrics
Regression Error Characteristic (REC) curves provide a powerful framework for evaluating and comparing regression models, generalizing the Receiver Operating Characteristic (ROC) curve used in classification.
Background and Theory
--------------------
+---------------------
The REC curve was introduced by **Bi & Bennett (2003)** in *"Regression error characteristic curves"* (Proceedings of the Twentieth International Conference on Machine Learning, pp. 43-50) as a method to visualize the cumulative distribution of errors in regression modeling.
diff --git a/docs/source/unsupervised.rst b/docs/source/unsupervised.rst
index 504b897..49df985 100644
--- a/docs/source/unsupervised.rst
+++ b/docs/source/unsupervised.rst
@@ -123,4 +123,51 @@ And the following image will be shown:
.. image:: ../../tests/baseline_images/test_unsupervised/test_plot_loss_vs_cluster_number.png
:align: center
- :alt: Optimum Number of Clusters
+ :alt: Loss vs Number of Clusters
+
+*****************************
+Plot Clusters (Matplotlib)
+*****************************
+
+The plot_clusters function creates a 2D scatter plot of clustering results.
+For data with more than 2 features, dimensionality reduction is applied
+automatically. Supports PCA (default), t-SNE, and UMAP (requires the optional
+``umap`` extra: ``pip install data-science-utils[umap]``).
+
+.. autofunction:: ds_utils.unsupervised.plot_clusters
+
+Example::
+
+ from matplotlib import pyplot as plt
+ from sklearn.cluster import KMeans
+ from ds_utils.unsupervised import plot_clusters
+
+ estimator = KMeans(n_clusters=8, random_state=42)
+ estimator.fit(X)
+
+ plot_clusters(X, estimator.labels_, estimator.cluster_centers_)
+ plt.show()
+
+.. image:: ../../tests/baseline_images/test_unsupervised/test_plot_clusters_pca_with_centroids.png
+ :align: center
+ :alt: Plot Clusters with PCA
+
+*****************************
+Plot Clusters (Plotly)
+*****************************
+
+The plot_clusters_plotly function provides an interactive Plotly scatter plot
+with hover information showing coordinates and cluster labels.
+
+.. autofunction:: ds_utils.unsupervised.plot_clusters_plotly
+
+Example::
+
+ from ds_utils.unsupervised import plot_clusters_plotly
+
+ fig = plot_clusters_plotly(X, estimator.labels_, estimator.cluster_centers_)
+ fig.show()
+
+.. image:: ../../tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_pca_with_centroids.png
+ :align: center
+ :alt: Plot Clusters Plotly
diff --git a/ds_utils/__init__.py b/ds_utils/__init__.py
index e935881..89c259b 100644
--- a/ds_utils/__init__.py
+++ b/ds_utils/__init__.py
@@ -1,3 +1,3 @@
"""Data Science Utilities package."""
-__version__ = "1.10.0rc13"
+__version__ = "1.10.0rc14"
diff --git a/ds_utils/unsupervised.py b/ds_utils/unsupervised.py
index eb72841..abf2a00 100644
--- a/ds_utils/unsupervised.py
+++ b/ds_utils/unsupervised.py
@@ -1,11 +1,20 @@
"""Unsupervised learning utilities for clustering visualization and analysis."""
-from typing import Optional, Callable, Dict, Any
+from typing import Optional, Callable, Dict, Any, Tuple
+import warnings
import numpy as np
import pandas as pd
from matplotlib import pyplot as plt, axes, lines
from sklearn.cluster import KMeans
+from sklearn.decomposition import PCA
+from sklearn.manifold import TSNE
+from plotly import graph_objects as go
+
+try:
+ from umap import UMAP
+except ImportError:
+ UMAP = None
def _extract_cardinality(labels):
@@ -211,3 +220,251 @@ def plot_loss_vs_cluster_number(
ax.set_title("Loss vs Number of Clusters")
return ax
+
+
+def _validate_cluster_plot_inputs(
+ X: np.ndarray,
+ cluster_labels: np.ndarray,
+ cluster_centers: Optional[np.ndarray],
+) -> Tuple[np.ndarray, np.ndarray, Optional[np.ndarray], np.ndarray]:
+ """Validate clustering plot inputs and return array-converted copies."""
+ X = np.asarray(X)
+ cluster_labels = np.asarray(cluster_labels)
+ if cluster_centers is not None:
+ cluster_centers = np.asarray(cluster_centers)
+
+ if X.ndim != 2 or X.shape[1] < 1:
+ raise ValueError("X must be a 2D array with at least 1 feature.")
+
+ if X.shape[1] == 1:
+ raise ValueError("X must have at least 2 features for 2D scatter visualization.")
+
+ if len(X) != len(cluster_labels):
+ raise ValueError("X and cluster_labels must have the same length.")
+
+ unique_labels = np.unique(cluster_labels)
+
+ if cluster_centers is not None and len(cluster_centers) != len(unique_labels):
+ raise ValueError("Number of cluster centers must match the number of unique labels.")
+
+ return X, cluster_labels, cluster_centers, unique_labels
+
+
+def _plot_cluster_scatter(
+ ax: axes.Axes,
+ X_plot: np.ndarray,
+ cluster_labels: np.ndarray,
+ cluster_centers_plot: Optional[np.ndarray],
+ colors,
+ unique_labels: np.ndarray,
+ **kwargs,
+) -> None:
+ """Create scatter plot of clusters on the given Axes (helper function)."""
+ # Plot data points
+ for i, cluster_label in enumerate(unique_labels):
+ cluster_data = X_plot[cluster_labels == cluster_label]
+ color = colors(i) if callable(colors) else colors[i]
+ scatter_kwargs = {"alpha": 0.6, "s": 50, **kwargs}
+ ax.scatter(
+ cluster_data[:, 0],
+ cluster_data[:, 1],
+ c=[color],
+ label=f"Cluster {cluster_label}",
+ **scatter_kwargs,
+ )
+
+ # Plot cluster centers if available
+ if cluster_centers_plot is not None:
+ ax.scatter(
+ cluster_centers_plot[:, 0],
+ cluster_centers_plot[:, 1],
+ c="red",
+ marker="x",
+ s=200,
+ linewidths=3,
+ label="Centroids",
+ )
+
+
+def _reduce_dimensions(
+ X: np.ndarray,
+ cluster_centers: Optional[np.ndarray],
+ reduction_method: str,
+ random_state: Optional[int],
+) -> Tuple[np.ndarray, Optional[np.ndarray], str, str, Optional[str]]:
+ """Reduce X (and optionally cluster_centers) to 2D."""
+ if X.shape[1] <= 2:
+ return X, cluster_centers, "Feature 1", "Feature 2", None
+
+ if reduction_method == "pca":
+ pca = PCA(n_components=2, random_state=random_state)
+ X_2d = pca.fit_transform(X)
+ centers_2d = pca.transform(cluster_centers) if cluster_centers is not None else None
+ return X_2d, centers_2d, "PC1", "PC2", f"PCA Explained Variance: {pca.explained_variance_ratio_.sum():.1%}"
+
+ if reduction_method == "tsne":
+ tsne = TSNE(n_components=2, random_state=random_state)
+ X_2d = tsne.fit_transform(X)
+ centers_2d = None
+ if cluster_centers is not None:
+ warnings.warn("t-SNE cannot transform new data; centroids will not be plotted.")
+ return X_2d, centers_2d, "t-SNE 1", "t-SNE 2", "t-SNE projection"
+
+ if reduction_method == "umap":
+ if UMAP is None:
+ raise ImportError(
+ "UMAP is not installed. To use reduction_method='umap', install it via: "
+ "`pip install data-science-utils[umap]` or `pip install umap-learn`."
+ )
+ umap_model = UMAP(n_components=2, random_state=random_state)
+ X_2d = umap_model.fit_transform(X)
+ centers_2d = umap_model.transform(cluster_centers) if cluster_centers is not None else None
+ return X_2d, centers_2d, "UMAP 1", "UMAP 2", "UMAP projection"
+
+ raise ValueError(f"Unknown reduction_method: '{reduction_method}'. Choose from 'pca', 'tsne', 'umap'.")
+
+
+def plot_clusters(
+ X: np.ndarray,
+ cluster_labels: np.ndarray,
+ cluster_centers: Optional[np.ndarray] = None,
+ *,
+ reduction_method: str = "pca",
+ random_state: Optional[int] = None,
+ ax: Optional[axes.Axes] = None,
+ **kwargs,
+) -> axes.Axes:
+ """Create a 2D scatter plot of clustering results.
+
+ Each cluster is shown in a distinct color. For high-dimensional data (more than 2 features),
+ dimensionality reduction is applied automatically.
+
+ :param X: array-like of shape (n_samples, n_features). The input data.
+ :param cluster_labels: array-like of shape (n_samples,). Cluster labels assigned by the clustering algorithm.
+ :param cluster_centers: array-like of shape (n_clusters, n_features), optional. Cluster centers to overlay.
+ :param reduction_method: str, default='pca'. The method to use for dimensionality reduction if n_features > 2.
+ Options: 'pca', 'tsne', 'umap'.
+ :param random_state: int, optional. Random state for the dimensionality reduction algorithm.
+ :param ax: Axes object to draw the plot onto; if None, uses the current Axes.
+ :param kwargs: Additional keyword arguments passed to `matplotlib.axes.Axes.scatter()` for cluster points.
+ :return: The Axes object with the plot drawn onto it.
+ :raises ValueError: If input arrays have inconsistent shapes or invalid reduction_method.
+ :raises ImportError: If 'umap' is requested but umap-learn is not installed.
+ """
+ if ax is None:
+ _, ax = plt.subplots()
+
+ X, cluster_labels, cluster_centers, unique_labels = _validate_cluster_plot_inputs(
+ X, cluster_labels, cluster_centers
+ )
+
+ X_2d, centers_2d, xlabel, ylabel, info_text = _reduce_dimensions(X, cluster_centers, reduction_method, random_state)
+
+ if len(unique_labels) <= 10:
+ colors = plt.get_cmap("tab10")
+ else:
+ colors = plt.get_cmap("tab20")
+
+ _plot_cluster_scatter(ax, X_2d, cluster_labels, centers_2d, colors, unique_labels, **kwargs)
+
+ if info_text:
+ ax.text(
+ 0.02,
+ 0.98,
+ info_text,
+ transform=ax.transAxes,
+ verticalalignment="top",
+ fontsize=9,
+ bbox=dict(boxstyle="round,pad=0.3", facecolor="white", alpha=0.8),
+ )
+
+ ax.set_xlabel(xlabel, fontsize=12)
+ ax.set_ylabel(ylabel, fontsize=12)
+ ax.set_title("Cluster Visualization", fontsize=14)
+ ax.legend(bbox_to_anchor=(1.04, 1), loc="upper left")
+ ax.grid(True, alpha=0.3)
+ if ax.figure is not None:
+ ax.figure.tight_layout()
+
+ return ax
+
+
+def plot_clusters_plotly(
+ X: np.ndarray,
+ cluster_labels: np.ndarray,
+ cluster_centers: Optional[np.ndarray] = None,
+ *,
+ reduction_method: str = "pca",
+ random_state: Optional[int] = None,
+ fig: Optional[go.Figure] = None,
+ show_legend: bool = True,
+ **kwargs,
+) -> go.Figure:
+ """Create an interactive 2D scatter plot of clustering results using Plotly.
+
+ Each cluster is shown in a distinct color. For high-dimensional data (more than 2 features),
+ dimensionality reduction is applied automatically.
+
+ :param X: array-like of shape (n_samples, n_features). The input data.
+ :param cluster_labels: array-like of shape (n_samples,). Cluster labels assigned by the clustering algorithm.
+ :param cluster_centers: array-like of shape (n_clusters, n_features), optional. Cluster centers to overlay.
+ :param reduction_method: str, default='pca'. The method to use for dimensionality reduction if n_features > 2.
+ Options: 'pca', 'tsne', 'umap'.
+ :param random_state: int, optional. Random state for the dimensionality reduction algorithm.
+ :param fig: plotly's Figure object, optional. The figure to plot on.
+ :param show_legend: bool, default=True. Whether to display legend in the plot.
+ :param kwargs: Additional keyword arguments passed to the go.Scatter trace.
+ :return: The Figure object with the plot drawn onto it.
+ :raises ValueError: If input arrays have inconsistent shapes or invalid reduction_method.
+ :raises ImportError: If 'umap' is requested but umap-learn is not installed.
+ """
+ if fig is None:
+ fig = go.Figure()
+
+ X, cluster_labels, cluster_centers, unique_labels = _validate_cluster_plot_inputs(
+ X, cluster_labels, cluster_centers
+ )
+
+ X_2d, centers_2d, xlabel, ylabel, info_text = _reduce_dimensions(X, cluster_centers, reduction_method, random_state)
+
+ # Note: For Plotly we just rely on its default color sequence (which is similar to tab10)
+ # when iterating through the distinct labels.
+ for cluster_label in unique_labels:
+ cluster_data = X_2d[cluster_labels == cluster_label]
+ fig.add_trace(
+ go.Scatter(
+ x=cluster_data[:, 0],
+ y=cluster_data[:, 1],
+ mode="markers",
+ name=f"Cluster {cluster_label}",
+ marker=dict(size=8, opacity=0.7),
+ text=[f"Cluster {cluster_label}"] * len(cluster_data),
+ hoverinfo="text+x+y",
+ **kwargs,
+ )
+ )
+
+ if centers_2d is not None:
+ fig.add_trace(
+ go.Scatter(
+ x=centers_2d[:, 0],
+ y=centers_2d[:, 1],
+ mode="markers",
+ name="Centroids",
+ marker=dict(symbol="x", size=12, color="red", line=dict(width=2, color="red")),
+ hoverinfo="name+x+y",
+ )
+ )
+
+ title_text = "Cluster Visualization"
+ if info_text:
+ title_text += f"
{info_text}"
+
+ fig.update_layout(
+ title=title_text,
+ xaxis_title=xlabel,
+ yaxis_title=ylabel,
+ showlegend=show_legend,
+ )
+
+ return fig
diff --git a/pyproject.toml b/pyproject.toml
index ba01857..d1507f4 100644
--- a/pyproject.toml
+++ b/pyproject.toml
@@ -63,7 +63,7 @@ test = [
"pytest-xdist==3.8.0",
"pytest-mpl==0.19.0",
"kaleido==1.3.0",
- "ruff==0.15.13"
+ "ruff==0.15.16"
]
dev = [
"build==1.5.0",
@@ -72,6 +72,9 @@ dev = [
nlp = [
"sentence-transformers>=3.0.0",
]
+umap = [
+ "umap-learn>=0.5.5",
+]
[dependency-groups]
@@ -83,7 +86,7 @@ dev = [
"pytest-xdist==3.8.0",
"pytest-mpl==0.19.0",
"kaleido==1.3.0",
- "ruff==0.15.13",
+ "ruff==0.15.16",
"build==1.5.0",
"twine==6.2.0",
]
diff --git a/requirements-conda.txt b/requirements-conda.txt
index 75da210..7757404 100644
--- a/requirements-conda.txt
+++ b/requirements-conda.txt
@@ -1,3 +1,3 @@
-conda-build==26.3.0
+conda-build==26.5.0
anaconda-client==1.14.0
ripgrep==15.1.0
diff --git a/skills/unsupervised/SKILL.md b/skills/unsupervised/SKILL.md
index 88630ee..f6b5951 100644
--- a/skills/unsupervised/SKILL.md
+++ b/skills/unsupervised/SKILL.md
@@ -1,7 +1,7 @@
---
name: ds-utils-unsupervised
description: >
- Provides evaluation and visualization for unsupervised learning and clustering. Use when the user asks to plot cluster cardinality, wants to visualize cluster magnitude, compare magnitude versus cardinality to find anomalies, or needs to determine the optimal number of clusters in a Python data science project using sklearn-compatible models.
+ Provides evaluation and visualization for unsupervised learning and clustering. Use when the user asks to plot cluster cardinality, wants to visualize cluster magnitude, compare magnitude versus cardinality to find anomalies, needs to determine the optimal number of clusters, or wants a 2D scatter plot of clustering results (PCA/t-SNE/UMAP, matplotlib or Plotly) in a Python data science project using sklearn-compatible models.
license: MIT
metadata:
author: Idan Morad
@@ -28,6 +28,8 @@ from ds_utils.unsupervised import plot_cluster_cardinality
from ds_utils.unsupervised import plot_cluster_magnitude
from ds_utils.unsupervised import plot_magnitude_vs_cardinality
from ds_utils.unsupervised import plot_loss_vs_cluster_number
+from ds_utils.unsupervised import plot_clusters
+from ds_utils.unsupervised import plot_clusters_plotly
```
---
@@ -155,6 +157,62 @@ plt.show()
---
+## plot_clusters
+
+Creates a 2D scatter plot of clustering results. For data with more than 2 features, PCA (default), t-SNE, or UMAP is applied automatically. Cluster centroids can optionally be overlaid.
+
+```python
+from ds_utils.unsupervised import plot_clusters
+from sklearn.cluster import KMeans
+from matplotlib import pyplot as plt
+
+estimator = KMeans(n_clusters=8, random_state=42)
+estimator.fit(X)
+
+plot_clusters(X, estimator.labels_, estimator.cluster_centers_, reduction_method="pca", random_state=42)
+plt.show()
+```
+
+**Parameters:**
+- `X` — array-like of shape (n_samples, n_features). Numeric 2D array with at least 2 features.
+- `cluster_labels` — array-like of shape (n_samples,). Cluster labels.
+- `cluster_centers` — array-like of shape (n_clusters, n_features), optional. Centroids to overlay.
+- `reduction_method` — `'pca'` (default), `'tsne'`, or `'umap'`. Used only when `n_features > 2`.
+- `random_state` — int, optional. Passed to the dimensionality reduction algorithm.
+- `ax` — matplotlib Axes, optional.
+
+**Returns:** matplotlib Axes.
+
+**Common mistakes:**
+- `X` must be numeric. Use `df.select_dtypes(include="number").values` if needed.
+- `reduction_method="umap"` requires `umap-learn` (`pip install data-science-utils[umap]`).
+- t-SNE cannot transform new points, so centroids are skipped (with a warning) when `reduction_method="tsne"`.
+
+---
+
+## plot_clusters_plotly
+
+Creates an interactive Plotly scatter plot of clustering results. Same reduction options as `plot_clusters`.
+
+```python
+from ds_utils.unsupervised import plot_clusters_plotly
+
+fig = plot_clusters_plotly(X, estimator.labels_, estimator.cluster_centers_)
+fig.show()
+```
+
+**Parameters:**
+- Same as `plot_clusters`, except `fig` (plotly Figure, optional) replaces `ax`.
+- `show_legend` — bool, default=True.
+
+**Returns:** `plotly.graph_objects.Figure` (not a matplotlib Axes).
+
+**Common mistakes:**
+- Call `.show()` on the returned figure.
+- Do not treat the return value as a matplotlib Axes.
+
+---
+
## Typical Workflow
```python
@@ -162,7 +220,7 @@ import pandas as pd
from matplotlib import pyplot as plt
from sklearn.cluster import KMeans
from scipy.spatial.distance import euclidean
-from ds_utils.unsupervised import plot_loss_vs_cluster_number, plot_magnitude_vs_cardinality
+from ds_utils.unsupervised import plot_loss_vs_cluster_number, plot_magnitude_vs_cardinality, plot_clusters
# Find optimal k
plot_loss_vs_cluster_number(
@@ -181,4 +239,8 @@ kmeans.fit(X)
# Analyze clusters
plot_magnitude_vs_cardinality(X, kmeans.labels_, kmeans.cluster_centers_, euclidean)
plt.show()
+
+# Visualize clusters
+plot_clusters(X, kmeans.labels_, kmeans.cluster_centers_, random_state=42)
+plt.show()
```
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_2d.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_2d.png
new file mode 100644
index 0000000..c909857
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_2d.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_2d_with_centroids.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_2d_with_centroids.png
new file mode 100644
index 0000000..5423a3a
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_2d_with_centroids.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_exist_ax.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_exist_ax.png
new file mode 100644
index 0000000..6798fad
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_exist_ax.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_pca.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_pca.png
new file mode 100644
index 0000000..c9b30ed
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_pca.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_pca_with_centroids.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_pca_with_centroids.png
new file mode 100644
index 0000000..0af3039
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_pca_with_centroids.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_2d.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_2d.png
new file mode 100644
index 0000000..92e1ee1
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_2d.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_existing_fig.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_existing_fig.png
new file mode 100644
index 0000000..a75e883
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_existing_fig.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_pca_with_centroids.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_pca_with_centroids.png
new file mode 100644
index 0000000..4a1b09b
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_plotly_pca_with_centroids.png differ
diff --git a/tests/baseline_images/test_unsupervised/test_plot_clusters_tsne.png b/tests/baseline_images/test_unsupervised/test_plot_clusters_tsne.png
new file mode 100644
index 0000000..51ec8c7
Binary files /dev/null and b/tests/baseline_images/test_unsupervised/test_plot_clusters_tsne.png differ
diff --git a/tests/test_unsupervised.py b/tests/test_unsupervised.py
index c017350..51c56c2 100644
--- a/tests/test_unsupervised.py
+++ b/tests/test_unsupervised.py
@@ -13,9 +13,16 @@
plot_cluster_magnitude,
plot_magnitude_vs_cardinality,
plot_loss_vs_cluster_number,
+ plot_clusters,
+ plot_clusters_plotly,
)
+from tests.utils import save_plotly_figure_and_return_matplot
+from plotly import graph_objects as go
BASELINE_DIR = Path(__file__).parent / "baseline_images" / "test_unsupervised"
+RESULT_DIR = Path(__file__).parent / "result_images" / "test_unsupervised"
+
+RESULT_DIR.mkdir(exist_ok=True, parents=True)
@pytest.fixture
@@ -382,3 +389,248 @@ def test_loss_vs_cluster_number_invalid_algorithm_parameters(mocker, iris_data):
plot_loss_vs_cluster_number(
iris_x.values, 3, 20, mocker.Mock(), algorithm_parameters={"invalid_param": "value"}
)
+
+
+# ---------------------------------------------------------------------------
+# plot_clusters tests (matplotlib)
+# ---------------------------------------------------------------------------
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_2d():
+ """Test plot_clusters with 2D data (no PCA needed)."""
+ # Create simple 2D dataset
+ X = np.array(
+ [
+ [1.0, 2.0],
+ [1.5, 1.8],
+ [1.2, 2.2],
+ [8.0, 8.0],
+ [8.5, 8.2],
+ [8.2, 8.5],
+ [1.0, 8.0],
+ [1.5, 8.2],
+ [1.2, 7.8],
+ ]
+ )
+ labels = np.array([0, 0, 0, 1, 1, 1, 2, 2, 2])
+ plot_clusters(X, labels, reduction_method="pca")
+ return plt.gcf()
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_2d_with_centroids():
+ """Test plot_clusters with 2D data and centroids overlay."""
+ X = np.array(
+ [
+ [1.0, 2.0],
+ [1.5, 1.8],
+ [1.2, 2.2],
+ [8.0, 8.0],
+ [8.5, 8.2],
+ [8.2, 8.5],
+ ]
+ )
+ labels = np.array([0, 0, 0, 1, 1, 1])
+ centers = np.array([[1.23, 2.0], [8.23, 8.23]])
+ plot_clusters(X, labels, centers)
+ return plt.gcf()
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_pca(iris_data):
+ """Test plot_clusters with high-dimensional data using PCA."""
+ iris_x, labels, _ = iris_data
+ plot_clusters(iris_x.values, labels, reduction_method="pca", random_state=42)
+ return plt.gcf()
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_pca_with_centroids(iris_data):
+ """Test plot_clusters with high-dimensional data, PCA, and centroids."""
+ iris_x, labels, cluster_centers = iris_data
+ plot_clusters(iris_x.values, labels, cluster_centers, reduction_method="pca", random_state=42)
+ return plt.gcf()
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_tsne(iris_data):
+ """Test plot_clusters with high-dimensional data using t-SNE."""
+ iris_x, labels, _ = iris_data
+ plot_clusters(iris_x.values, labels, reduction_method="tsne", random_state=42)
+ return plt.gcf()
+
+
+def test_plot_clusters_tsne_with_centroids(iris_data):
+ """Test plot_clusters with t-SNE and centroids, should warn."""
+ iris_x, labels, cluster_centers = iris_data
+ with pytest.warns(UserWarning, match="t-SNE cannot transform new data; centroids will not be plotted."):
+ ax = plot_clusters(iris_x.values, labels, cluster_centers, reduction_method="tsne", random_state=42)
+ assert ax is not None
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_exist_ax(iris_data):
+ """Test plot_clusters works with a pre-existing Axes."""
+ fig, ax = plt.subplots()
+ ax.set_facecolor("lightgray")
+
+ iris_x, labels, _ = iris_data
+ plot_clusters(iris_x.values, labels, reduction_method="pca", random_state=42, ax=ax)
+ return fig
+
+
+def test_plot_clusters_empty_x():
+ """Test plot_clusters raises ValueError for empty X."""
+ with pytest.raises(ValueError, match="X must be a 2D array with at least 1 feature."):
+ plot_clusters(np.array([]), np.array([]))
+
+
+def test_plot_clusters_1d_x():
+ """Test plot_clusters raises ValueError for 1D X."""
+ with pytest.raises(ValueError, match="X must be a 2D array with at least 1 feature."):
+ plot_clusters(np.array([1, 2, 3]), np.array([0, 0, 0]))
+
+
+def test_plot_clusters_single_feature():
+ """Test plot_clusters raises ValueError for a single-feature 2D array."""
+ X = np.array([[1.0], [2.0], [3.0]])
+ labels = np.array([0, 0, 1])
+ with pytest.raises(ValueError, match="X must have at least 2 features for 2D scatter visualization."):
+ plot_clusters(X, labels)
+
+
+def test_plot_clusters_inconsistent_lengths():
+ """Test plot_clusters raises ValueError for X and labels length mismatch."""
+ X = np.array([[1, 2], [3, 4]])
+ labels = np.array([0, 0, 1])
+ with pytest.raises(ValueError, match="X and cluster_labels must have the same length."):
+ plot_clusters(X, labels)
+
+
+def test_plot_clusters_inconsistent_centers():
+ """Test plot_clusters raises ValueError for cluster_centers length mismatch."""
+ X = np.array([[1, 2], [3, 4]])
+ labels = np.array([0, 1])
+ centers = np.array([[1.5, 2.5]]) # Only 1 center, but 2 unique labels
+ with pytest.raises(ValueError, match="Number of cluster centers must match the number of unique labels."):
+ plot_clusters(X, labels, centers)
+
+
+def test_plot_clusters_invalid_reduction_method():
+ """Test plot_clusters raises ValueError for invalid reduction_method."""
+ X = np.array([[1, 2, 3], [4, 5, 6], [7, 8, 9]])
+ labels = np.array([0, 1, 0])
+ with pytest.raises(ValueError, match="Unknown reduction_method: 'invalid'"):
+ plot_clusters(X, labels, reduction_method="invalid")
+
+
+def test_plot_clusters_umap_not_installed(mocker):
+ """Test plot_clusters raises ImportError if UMAP is requested but not installed."""
+ mocker.patch("ds_utils.unsupervised.UMAP", None)
+ X = np.array([[1, 2, 3], [4, 5, 6], [7, 8, 9]])
+ labels = np.array([0, 1, 0])
+ with pytest.raises(ImportError, match="UMAP is not installed"):
+ plot_clusters(X, labels, reduction_method="umap")
+
+
+def test_plot_clusters_umap_installed(mocker):
+ """Test plot_clusters executes UMAP branch when UMAP is available."""
+ mock_umap = mocker.Mock()
+ mock_umap_instance = mocker.Mock()
+ mock_umap.return_value = mock_umap_instance
+ mock_umap_instance.fit_transform.return_value = np.array([[1, 2], [3, 4]])
+ mock_umap_instance.transform.return_value = np.array([[1.5, 2.5], [3.5, 4.5]])
+ mocker.patch("ds_utils.unsupervised.UMAP", mock_umap)
+
+ X = np.array([[1, 2, 3], [4, 5, 6]])
+ labels = np.array([0, 1])
+ centers = np.array([[1, 2, 3], [4, 5, 6]])
+ ax = plot_clusters(X, labels, centers, reduction_method="umap")
+ assert ax is not None
+ mock_umap_instance.fit_transform.assert_called_once()
+ mock_umap_instance.transform.assert_called_once()
+
+
+def test_plot_clusters_many_clusters():
+ """Test plot_clusters with > 10 clusters to trigger tab20 colormap branch."""
+ X = np.random.rand(20, 2)
+ labels = np.arange(20) # 20 unique clusters
+ ax = plot_clusters(X, labels)
+ assert ax is not None
+
+
+# ---------------------------------------------------------------------------
+# plot_clusters_plotly tests
+# ---------------------------------------------------------------------------
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_plotly_2d(request):
+ """Test plot_clusters_plotly with 2D data."""
+ X = np.array(
+ [
+ [1.0, 2.0],
+ [1.5, 1.8],
+ [1.2, 2.2],
+ [8.0, 8.0],
+ [8.5, 8.2],
+ [8.2, 8.5],
+ [1.0, 8.0],
+ [1.5, 8.2],
+ [1.2, 7.8],
+ ]
+ )
+ labels = np.array([0, 0, 0, 1, 1, 1, 2, 2, 2])
+ fig = plot_clusters_plotly(X, labels)
+ return save_plotly_figure_and_return_matplot(fig, RESULT_DIR / f"{request.node.name}.png")
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_plotly_pca_with_centroids(request, iris_data):
+ """Test plot_clusters_plotly with high-dimensional data, PCA, and centroids."""
+ iris_x, labels, cluster_centers = iris_data
+ fig = plot_clusters_plotly(iris_x.values, labels, cluster_centers, reduction_method="pca", random_state=42)
+ return save_plotly_figure_and_return_matplot(fig, RESULT_DIR / f"{request.node.name}.png")
+
+
+@pytest.mark.mpl_image_compare(baseline_dir=BASELINE_DIR, tolerance=18)
+def test_plot_clusters_plotly_existing_fig(request, iris_data):
+ """Test plot_clusters_plotly works with a pre-existing Figure."""
+ fig = go.Figure()
+ fig.update_layout(title="My Custom Plotly Title")
+
+ iris_x, labels, _ = iris_data
+ fig = plot_clusters_plotly(iris_x.values, labels, reduction_method="pca", random_state=42, fig=fig)
+ return save_plotly_figure_and_return_matplot(fig, RESULT_DIR / f"{request.node.name}.png")
+
+
+def test_plot_clusters_plotly_empty_x():
+ """Test plot_clusters_plotly raises ValueError for empty X."""
+ with pytest.raises(ValueError, match="X must be a 2D array with at least 1 feature."):
+ plot_clusters_plotly(np.array([]), np.array([]))
+
+
+def test_plot_clusters_plotly_inconsistent_lengths():
+ """Test plot_clusters_plotly raises ValueError for X and labels length mismatch."""
+ X = np.array([[1, 2], [3, 4]])
+ labels = np.array([0, 0, 1])
+ with pytest.raises(ValueError, match="X and cluster_labels must have the same length."):
+ plot_clusters_plotly(X, labels)
+
+
+def test_plot_clusters_plotly_single_feature():
+ """Test plot_clusters_plotly raises ValueError for a single-feature 2D array."""
+ X = np.array([[1.0], [2.0], [3.0]])
+ labels = np.array([0, 0, 1])
+ with pytest.raises(ValueError, match="X must have at least 2 features for 2D scatter visualization."):
+ plot_clusters_plotly(X, labels)
+
+
+def test_plot_clusters_plotly_inconsistent_centers():
+ """Test plot_clusters_plotly raises ValueError for cluster_centers length mismatch."""
+ X = np.array([[1, 2], [3, 4]])
+ labels = np.array([0, 1])
+ centers = np.array([[1.5, 2.5]]) # Only 1 center, but 2 unique labels
+ with pytest.raises(ValueError, match="Number of cluster centers must match the number of unique labels."):
+ plot_clusters_plotly(X, labels, centers)
diff --git a/tests/test_version.py b/tests/test_version.py
index 5724051..c3acbdd 100644
--- a/tests/test_version.py
+++ b/tests/test_version.py
@@ -5,4 +5,4 @@
def test_version():
"""Test that the package version is correct."""
- assert ds_utils.__version__ == "1.10.0rc13"
+ assert ds_utils.__version__ == "1.10.0rc14"