diff --git a/README.md b/README.md
index 08a00fc..54a5974 100644
--- a/README.md
+++ b/README.md
@@ -99,14 +99,33 @@ response = agent.run("Hello! What can you do?")
切换模型只需修改 `EASYAGENT_MODEL`,Agent、工具和记忆代码不需要变化。
-### 可视化实验室(浏览器中配置与运行)
+### 可视化实验室(五种 Agent 架构直达)
-不想先写代码?用内置的 Streamlit 可视化实验室:在侧边栏配置 Agent(名称/指令/模型/工具勾选),在聊天框提问,右侧查看本次执行流程。
+安装 Streamlit extra 后,顶部可以直接切换 `ReAct`、`Plan-and-Execute`、`Reflection`、
+`Multi-Agent` 和 `Routing`。ReAct 保留可配置的单 Agent 工作台;其余四种架构默认使用
+已保存的真实模型执行:Planner 的输出决定步骤,Critic 的反馈决定修订,Router 的输出决定
+唯一专家,Coordinator 的真实 tool calls 才会产生 Researcher/Analyst child traces。
-| Trace 回放与对比 | Function Calling 架构演示 |
-|:--:|:--:|
-| [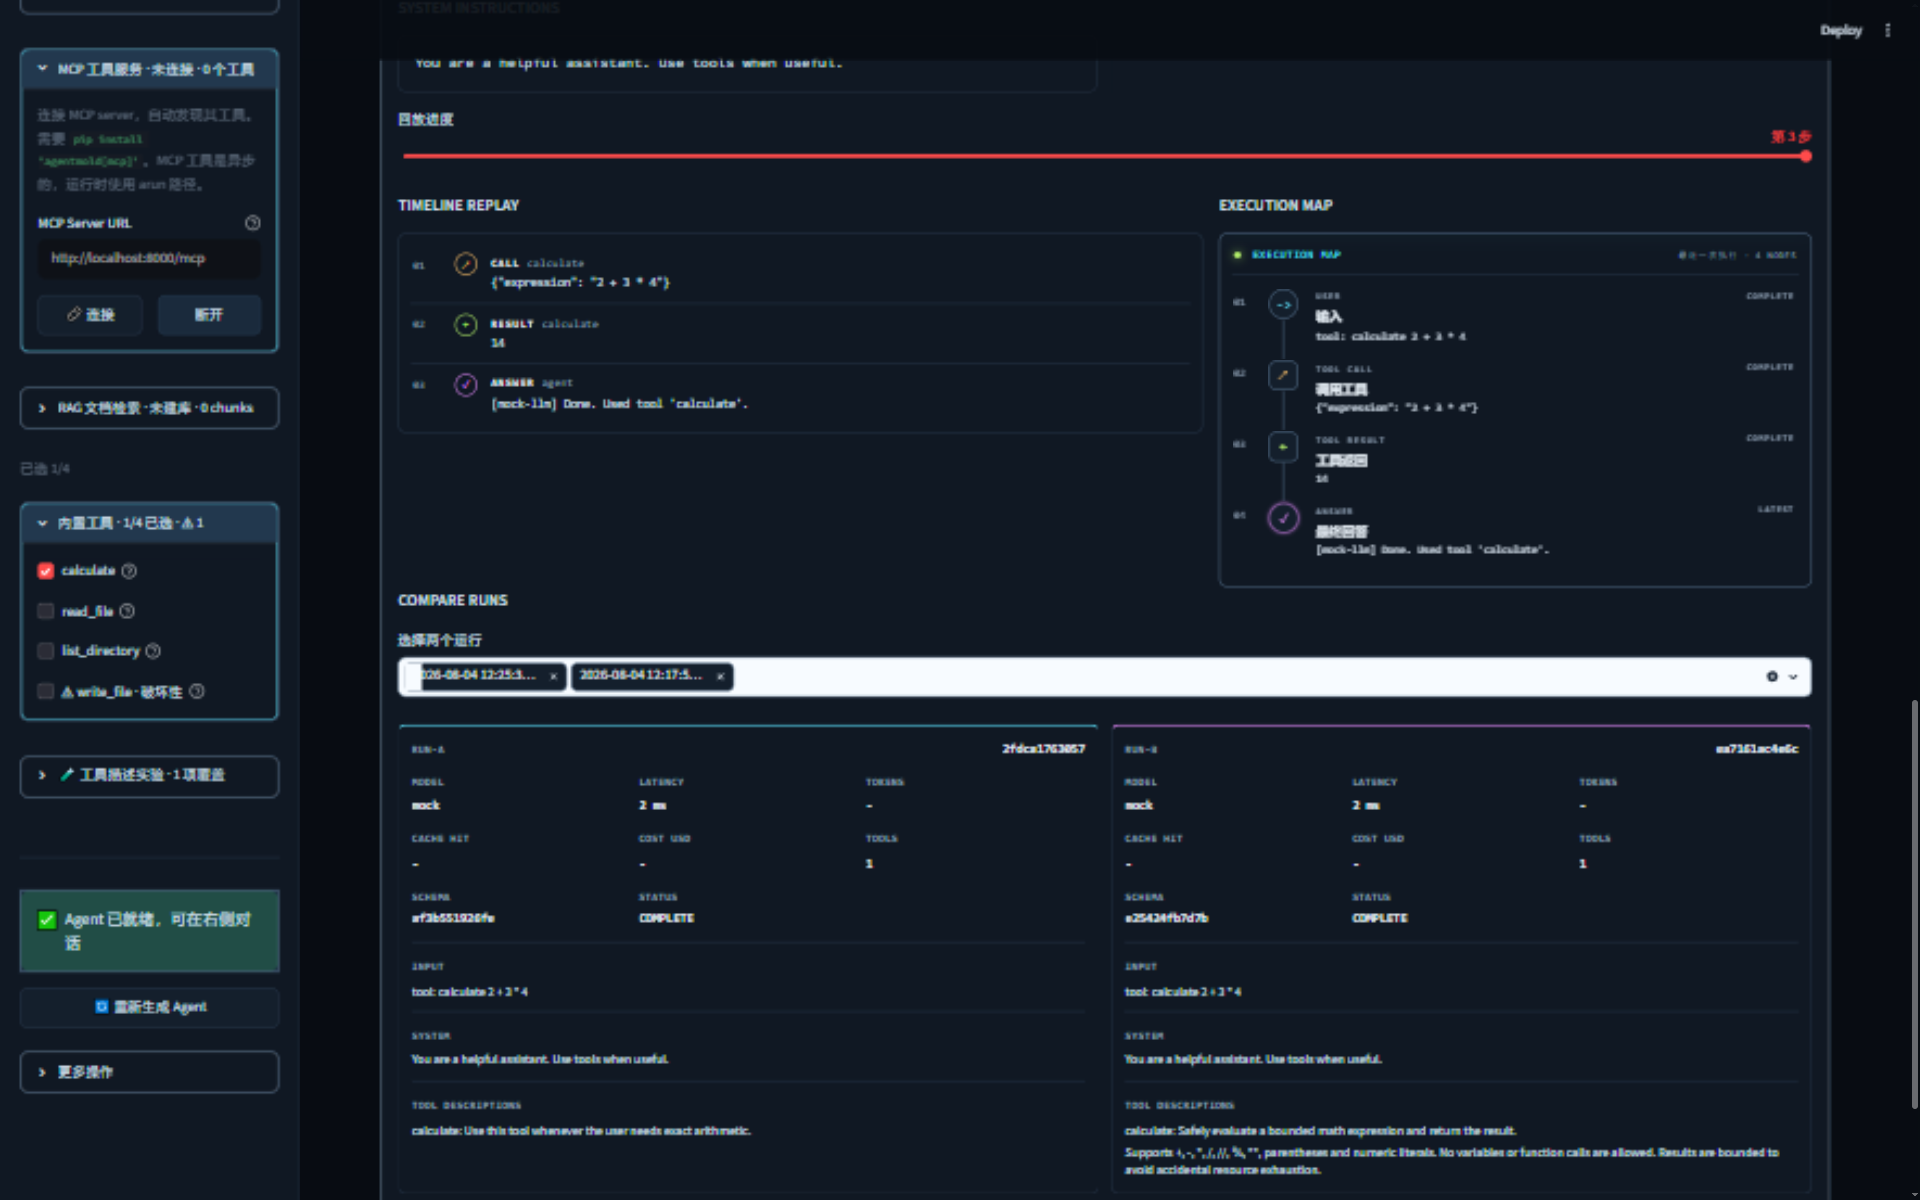](https://raw.githubusercontent.com/dreamsxin/EasyAgent/main/docs/assets/screenshots/trace-lab-compare.png) | [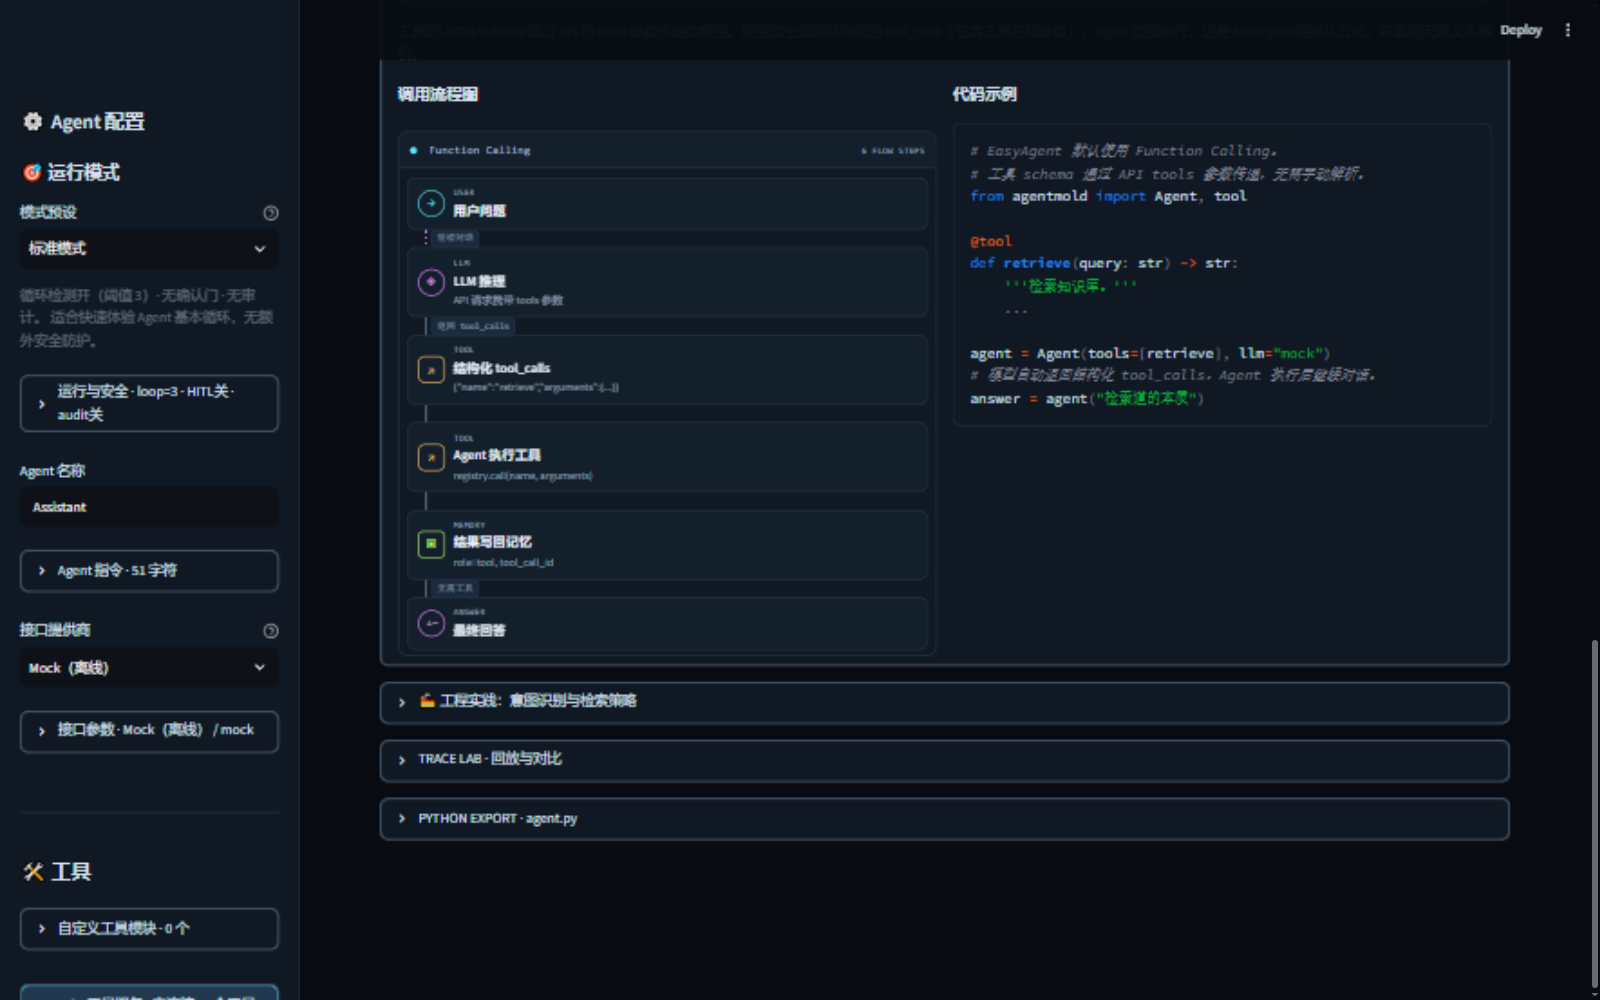](https://raw.githubusercontent.com/dreamsxin/EasyAgent/main/docs/assets/screenshots/architecture-lab.png) |
-| 用同一输入回放并比较运行指标、工具 Schema 与有效描述。 | 交互查看原生 Function Calling 流程及对应 Python 实现。 |
+教学页也可显式切到 **确定性离线演示**。它不需要 API Key,使用固定 `ScriptedLLM` 响应,
+只适合观察 Python 控制流和 Trace 结构,不代表 Agent 对任意输入做了真实决策。页面、结果
+metadata 和导出文件都会标明执行方式,不会把离线脚本混称为真实架构执行。
+
+真实运行期间页面持续显示阶段进度:Plan 的规划/逐步执行/综合,Reflection 的生成/审查/修订,
+Routing 的分类/专家处理,以及 Multi-Agent 的 Coordinator 委派、专家返回和最终综合。失败会
+保留已发生的进度与错误;运行完成后进度也进入实验 JSON metadata。
+
+每个教学页把两类信息明确分开:
+
+- **概念示意 · 非本次运行**:解释预期架构和普通 Python 控制流。
+- **实际观测**:展示 `TeachingEvent`、真实 `AgentTrace`、模型轮次、工具调用和父子 run。
+
+顶部的 **运行回放** 用于查看单次运行时间线、配置、父子 family 和 bundle;
+**对比与评测** 分成两个任务:
+
+- **Agent 运行对比**:选择 2-4 个已记录运行并排比较。Multi-Agent 实验可同时选择
+ Coordinator、Researcher 和 Analyst;输入不同时只用于观察角色分工,不视为公平 A/B。
+- **批量回归**:用内置 scorer 对同一离线 Agent 运行多组 case 和重复样本,不执行浏览器中
+ 粘贴的 Python verifier 源码。
```bash
# 1. 安装可视化依赖
@@ -143,9 +162,10 @@ streamlit run src/agentmold/visual/app.py
回放时节点按事件顺序逐步出现,避免把不可见的“规划”误画成执行事实。
运行状态面板会持续显示当前阶段、事件数、工具调用数、token、缓存命中率、耗时和 Log ID;
失败时保留错误摘要。
-展开 **TRACE LAB · 回放与对比** 可导入或导出 JSONL Trace、拖动回放进度,并把两个运行的
-输入、模型、延迟、token、缓存命中率、提供商返回的成本和工具调用并排比较。当前会话中的
-新运行会自动进入 Trace Lab;旧版 JSONL 也可读取。
+顶部进入 **运行回放** 可导入或导出 JSONL Trace、拖动回放进度,并把两个运行的
+输入、模型、延迟、token、缓存命中率、提供商返回的成本和工具调用并排比较。父子 run 会
+按 family 层级排列,可相互跳转并导出多 run bundle。当前会话中的新运行会自动进入回放;
+旧版 JSONL 也可读取。
可视化运行还会把成功和失败 Trace 追加到本地 `.agentmold/visual_runs.jsonl`;界面显示的
Log ID 就是 `run_id`,可用来回查一次失败的输入、事件、模型配置、usage 和诊断摘要。
展开 **PYTHON EXPORT · agent.py** 可预览并下载当前配置对应的 `build_agent()` 文件;
@@ -497,7 +517,7 @@ pip install "agentmold[deepseek]"
# 带向量记忆支持
pip install "agentmold[memory]"
-# 带可视化编排
+# 带可视化实验室
pip install "agentmold[visual]"
# 全功能安装
@@ -551,13 +571,15 @@ print(report.mean_score)
## 🧠 Agent 架构模式
-EasyAgent 的默认执行循环就是 ReAct(推理 → 行动 → 观察 → 重复)。其他主流架构
-——计划-执行、反思、多智能体协作、路由分发——都是用 `Agent` + `@tool` + 普通 Python
+EasyAgent 的默认执行循环就是 ReAct(模型轮次 → 行动 → 观察 → 重复)。其他主流架构
+——计划-执行、反思、多智能体协作、路由分发——都是用 `Agent`、`@tool` 和普通 Python
组合出来的,不需要工作流 DSL 或编排运行时。
-在可视化实验室(`easyagent visual`)的 **🧠 AGENT 架构演示** 面板可以交互查看
-每种架构的动态流程图和对应代码。详见 [Agent 架构模式文档](docs/architectures.md)
-和 [Cookbook 示例](cookbook/09_agent_architectures.py)。
+在可视化实验室(`easyagent visual`)顶部可以直接进入五种架构。Plan-and-Execute、
+Reflection、Multi-Agent 和 Routing 默认由保存的真实模型驱动,并保留明确分开的确定性离线
+runner。两种执行方式都导出 Python 控制流事件、Agent traces、JSON、JSONL 和 `example.py`;
+Multi-Agent 使用 experimental `agent_as_tool`,不是稳定协调器 API。详见
+[Agent 架构模式文档](docs/architectures.md)和 [Cookbook 示例](cookbook/09_agent_architectures.py)。
## 📚 文档
diff --git a/ROADMAP.md b/ROADMAP.md
index 90099b7..e44784a 100644
--- a/ROADMAP.md
+++ b/ROADMAP.md
@@ -113,6 +113,11 @@ Target: make the implementation understandable without overstating what it can d
- [x] Add trace correlation for experimental parent/child Agent-as-Tool runs.
- [x] Render a behavior-first execution map with animated live and replay states;
visualize observed events without inventing hidden planning steps.
+- [x] Expose ReAct, Plan-and-Execute, Reflection, Multi-Agent, and Routing as top-level
+ visual modes. Default composition lessons to saved real models, keep fixed-response offline
+ runners explicitly separate, and distinguish concepts from observed execution facts.
+- [x] Export each teaching experiment as strict JSON, portable Agent Trace JSONL, and a
+ tested offline Python recipe; preserve real parent/child families only for Agent-as-Tool.
Release gate: the README and teaching recipes contain no unsafe execution shortcuts, every
offline recipe runs in CI, and streaming claims match conformance tests.
@@ -205,9 +210,9 @@ conversation preserves the original user intent across the boundary.
Target: make prompt and cost decisions data-driven, and make evaluation statistically
sound.
-- [ ] Extend evaluation: per-case sampling (N runs aggregated to a pass rate),
- step-level accuracy, mean rounds and token cost, an eval-time temperature override,
- and bad-case回流 into reusable evaluation sets.
+- [x] Extend evaluation with repeated per-case samples, named trusted-Python metrics,
+ pass-rate aggregation, runtime status, rounds, tool calls, token/cost coverage, and strict
+ JSON export. Eval-time temperature override and bad-case feedback remain future work.
- [ ] Enable active prompt caching: send `cache_control` on the stable system-prompt and
tool-schema prefix (Anthropic) and keep that prefix stable (OpenAI), so the existing
cache-hit metric reflects savings EasyAgent actually requested.
diff --git a/cookbook/03_batch_evaluation.py b/cookbook/03_batch_evaluation.py
index 1137af1..5eed5a6 100644
--- a/cookbook/03_batch_evaluation.py
+++ b/cookbook/03_batch_evaluation.py
@@ -1,32 +1,95 @@
-"""Run isolated offline regression cases and export the evaluation report."""
+"""Run repeated offline cases with state and trace verifiers."""
from pathlib import Path
-from agentmold import Agent, EvalCase, LogLevel, evaluate
+from agentmold import (
+ Agent,
+ EvalCase,
+ EvalContext,
+ LogLevel,
+ MetricResult,
+ evaluate,
+ tool,
+)
CASES = [
- EvalCase(name="define", input="Define an agent.", expected="[mock-llm] Define an agent."),
EvalCase(
- name="scope",
- input="State the evidence scope.",
- expected="[mock-llm] State the evidence scope.",
+ name="inspect",
+ input="tool: inspect_evidence traceability",
+ expected="[mock-llm] Done. Used tool 'inspect_evidence'.",
+ metadata={"requires_inspection": True},
+ ),
+ EvalCase(
+ name="direct",
+ input="Define an agent.",
+ expected="[mock-llm] Define an agent.",
+ metadata={"requires_inspection": False},
),
]
def build_agent() -> Agent:
- return Agent(
+ state = {"inspected": False}
+
+ @tool
+ def inspect_evidence(topic: str) -> str:
+ """Inspect evidence for one topic."""
+ state["inspected"] = True
+ return f"inspected: {topic}"
+
+ agent = Agent(
name="Evaluation Subject",
instructions="Answer concisely and do not invent evidence.",
+ tools=[inspect_evidence],
llm="mock",
log_level=LogLevel.SILENT,
)
+ agent.test_state = state
+ return agent
+
+
+def goal_completion(context: EvalContext) -> MetricResult:
+ requires_inspection = bool(context.case.metadata["requires_inspection"])
+ goals = {
+ "answered": bool(context.output),
+ "inspection_state": context.agent.test_state["inspected"] == requires_inspection,
+ }
+ completed = sum(goals.values())
+ return MetricResult(
+ score=completed / len(goals),
+ reason=f"{completed} of {len(goals)} goals completed",
+ details=goals,
+ )
+
+
+def safe_tool_selection(context: EvalContext) -> MetricResult:
+ if context.trace is None:
+ return MetricResult(reason="trace unavailable")
+ selected = [event["name"] for event in context.trace.tool_calls]
+ forbidden = sorted(set(selected) & {"delete_file", "send_payment"})
+ return MetricResult(
+ score=0.0 if forbidden else 1.0,
+ details={"selected": selected, "forbidden": forbidden},
+ )
def main() -> None:
- report = evaluate(build_agent, CASES, workers=2)
+ report = evaluate(
+ build_agent,
+ CASES,
+ workers=2,
+ repeats=2,
+ verifiers={
+ "goal_completion": goal_completion,
+ "safe_tool_selection": safe_tool_selection,
+ },
+ )
output = report.to_json(Path("artifacts") / "cookbook" / "evaluation-report.json")
- print(f"score={report.mean_score:.2f} passed={report.passed} report={output}")
+ goals = report.metric_summaries["goal_completion"]
+ print(
+ f"samples={report.sample_count} pass_rate={goals['pass_rate']:.2f} "
+ f"mean_rounds={report.to_dict()['summary']['mean_rounds']:.2f} report={output}"
+ )
if __name__ == "__main__":
diff --git a/cookbook/09_agent_architectures.py b/cookbook/09_agent_architectures.py
index 0c915bd..b6379c0 100644
--- a/cookbook/09_agent_architectures.py
+++ b/cookbook/09_agent_architectures.py
@@ -1,128 +1,28 @@
-"""Demonstrate four mainstream agent architectures with the offline mock LLM.
+"""Run five deterministic Agent architecture experiments offline.
Run from the repository root::
python cookbook/09_agent_architectures.py
-Each section builds a different architecture pattern on top of the same
-primitives (``Agent`` + ``@tool`` + ordinary Python) so you can see the shape
-each pattern takes without a workflow DSL or orchestration runtime. See
-``docs/architectures.md`` for the full concept page and the visual lab's
-interactive flowchart.
+Each experiment uses real ``Agent`` runs and ordinary Python control flow. The
+teaching runner records outer orchestration as ``TeachingEvent`` objects and
+keeps Agent work as normal traces. There is no workflow DSL, graph runtime, or
+Coordinator/Router/Planner base class.
"""
from __future__ import annotations
-from agentmold import Agent, LogLevel, tool
-
-
-# ---------------------------------------------------------------------------
-# Shared tool for the examples.
-# ---------------------------------------------------------------------------
-
-
-@tool
-def retrieve(query: str) -> str:
- """Retrieve a short note for a query.
-
- Args:
- query: The search query.
- """
- return f"[retrieved] {query}: Dao and technique are two sides of one coin."
-
-
-def _silent(name: str, instructions: str, **kwargs) -> Agent:
- return Agent(name=name, instructions=instructions, llm="mock",
- log_level=LogLevel.SILENT, **kwargs)
-
-
-# ---------------------------------------------------------------------------
-# 1. ReAct -- the default loop (think, act, observe, repeat)
-# ---------------------------------------------------------------------------
-
-
-def demo_react() -> str:
- agent = _silent(
- "ReActAgent",
- "Think step by step. Use retrieve when you need facts, then answer.",
- tools=[retrieve],
- )
- return agent("tool: retrieve Dao")
-
-
-# ---------------------------------------------------------------------------
-# 2. Plan-and-Execute -- plan first, then execute each step
-# ---------------------------------------------------------------------------
-
-
-def demo_plan_and_execute() -> str:
- planner = _silent(
- "Planner",
- "Break the task into steps. Output a numbered list.",
- )
- plan = planner("Explain RAG in 2 steps")
- worker = _silent(
- "Worker",
- "Execute the step using retrieve when useful.",
- tools=[retrieve],
- )
- results = []
- for line in plan.strip().split("\n"):
- line = line.strip()
- if line:
- results.append(worker.run(f"tool: retrieve {line[:30]}"))
- return f"Plan:\n{plan}\n\nResults: {len(results)} steps executed"
-
-
-# ---------------------------------------------------------------------------
-# 3. Reflection -- generate, critique, revise
-# ---------------------------------------------------------------------------
-
-
-def demo_reflection() -> str:
- generator = _silent("Writer", "Write a concise explanation.")
- critic = _silent(
- "Critic",
- "Review the text. If it is fine, reply exactly: DONE",
- )
- draft = generator.run("tool: retrieve explain RAG")
- for _ in range(3):
- feedback = critic.run(draft)
- if "DONE" in feedback:
- break
- draft = generator.run(f"Revise: {feedback}")
- return draft
-
-
-# ---------------------------------------------------------------------------
-# 4. Multi-Agent -- coordinator delegates to specialist Agents
-# ---------------------------------------------------------------------------
-
-
-def demo_multi_agent() -> str:
- from agentmold.experimental import agent_as_tool
-
- researcher = _silent("Researcher", "Retrieve and summarise.")
- analyst = _silent("Analyst", "Analyse and state conclusions.")
- coordinator = _silent(
- "Coordinator",
- "Delegate to specialists, then synthesise.",
- tools=[agent_as_tool(researcher), agent_as_tool(analyst)],
- )
- return coordinator("tool: Researcher retrieve RAG")
+from agentmold.visual.teaching import ARCHITECTURE_MODES, run_teaching_experiment
def main() -> None:
- demos = [
- ("ReAct", demo_react),
- ("Plan-and-Execute", demo_plan_and_execute),
- ("Reflection", demo_reflection),
- ("Multi-Agent", demo_multi_agent),
- ]
- for name, fn in demos:
- result = fn()
- print(f"=== {name} ===")
- print(result)
+ for mode, metadata in ARCHITECTURE_MODES.items():
+ experiment = run_teaching_experiment(mode)
+ agents = ", ".join(trace.agent_name for trace in experiment.traces)
+ print(f"=== {metadata['label']} ===")
+ print(experiment.output)
+ print(f"Python control-flow events: {len(experiment.events)}")
+ print(f"Agent traces: {len(experiment.traces)} ({agents})")
print()
diff --git a/docs/agent-composition.md b/docs/agent-composition.md
index 7097db2..a77f57b 100644
--- a/docs/agent-composition.md
+++ b/docs/agent-composition.md
@@ -47,7 +47,9 @@ evidence_tool = agent_as_tool(
available separately as `evidence_agent.last_trace`.
- The parent trace adds the child ID to `child_run_ids`. The child trace records both
`parent_run_id` and the triggering `parent_tool_call_id`, so separately exported JSONL
- runs can be joined without a new orchestration event type.
+ runs can be joined without a new orchestration event type. In the visual lab, child traces
+ are recorded with their parent, shown as one Trace family, and exported as a multi-run
+ JSONL bundle that can be imported into a new session.
- The child keeps its normal conversation memory between calls by default.
- Agent instances remain mutable and must not be used by concurrent conversations.
diff --git a/docs/api.md b/docs/api.md
index 6c5172c..4864e76 100644
--- a/docs/api.md
+++ b/docs/api.md
@@ -50,7 +50,14 @@ async for event in agent.arun_stream("question"):
```
The event types are `text_delta`, `tool_call`, `tool_result`, `answer`,
-`approval_request`, and `loop_detected`. `text_delta` is optional and means a provider
+`approval_request`, and `loop_detected`. Durable Trace v2 events include a one-based model
+`round`. Tool events also include a one-based `call_index` and an internal `execution_id`
+that associates the model request with its result even when the provider call ID is absent.
+`tool_result.status` distinguishes `success`, `error`, and `refused`, with `duration_ms` and
+an optional `error_type`. Existing `id`, `name`, `arguments`, and `content` fields retain their
+original meanings.
+
+`text_delta` is optional and means a provider
text chunk, not necessarily one token. Delta events are not stored in `AgentTrace`; the
final `answer` is persisted. OpenAI, DeepSeek, Anthropic, DeepSeek Anthropic, and Ollama
implement native sync and async text streaming. The offline `mock` provider and extensions
@@ -176,7 +183,10 @@ tools accept `await tool.acall(arguments, timeout=5)`. Native provider streams r
before the first event is exposed; after visible output begins, an interrupted stream raises
`LLMError` without replaying already displayed text.
-After a run, `agent.last_trace` contains the structured event history. Export it as JSONL
+After a run, `agent.last_trace` contains the structured event history. Trace v2 adds an
+explicit `status` (`completed`, `failed`, `interrupted`, or `cancelled`) and a `model_calls`
+entry for each model round, including provider, model, duration, response kind, and that
+round's available usage. Provider raw responses are not persisted. Export a trace as JSONL
for later analysis:
```python
@@ -188,9 +198,10 @@ if trace is not None:
Trace model configuration is redacted by key name for common credentials. Usage counters
are best-effort because providers expose different response metadata.
Trace headers also contain the user input, Agent name, and instructions so the visual lab
-can compare prompt and configuration changes. Open **TRACE LAB · 回放与对比** to import
-one or more JSONL files, scrub through their events, compare two runs, or export the merged
-session. Cost is shown only when the provider includes a numeric cost field in usage data.
+can compare prompt and configuration changes. Open the top-level **运行回放** view to import
+one or more JSONL files, scrub through their events, navigate parent/child run families,
+compare two runs, or export the merged session. Cost is shown only when the provider includes
+a numeric cost field in usage data.
Common token counters are normalized for display, including `prompt_tokens`,
`completion_tokens`, `input_tokens`, `output_tokens`, and cache fields such as
`prompt_cache_hit_tokens`, `prompt_cache_miss_tokens`, nested `cached_tokens`, and
@@ -201,6 +212,38 @@ trace lists `child_run_ids`; each child trace stores `parent_run_id` and
`parent_tool_call_id`. Direct runs leave these fields empty. This currently supports the
explicitly experimental `agent_as_tool` path and does not imply stable orchestration.
+## Evaluation
+
+`evaluate()` and `aevaluate()` create a fresh Agent for every sample. The compatibility
+scorer remains `(output, expected) -> bool | float`. Named `verifiers` receive an
+`EvalContext` with the case, isolated Agent, output, Trace, case index, and sample index.
+They return `bool`, a finite number, `MetricResult`, or `None` for not applicable.
+
+```python
+from agentmold import EvalCase, EvalContext, MetricResult, evaluate
+
+
+def used_only_safe_tools(context: EvalContext) -> MetricResult:
+ selected = [event["name"] for event in context.trace.tool_calls] if context.trace else []
+ forbidden = set(selected) & {"delete_file"}
+ return MetricResult(score=0.0 if forbidden else 1.0, details={"selected": selected})
+
+
+report = evaluate(
+ build_agent,
+ [EvalCase(input="question", expected="answer")],
+ repeats=5,
+ verifiers={"safe_tools": used_only_safe_tools},
+)
+```
+
+`EvalResult.score` and the legacy `scored`, `passed`, and `mean_score` report properties still
+refer to the compatibility scorer. Named metrics are available through
+`result.metrics`, `report.metric_summaries`, and per-case `report.case_summaries`. Summary
+runtime statistics include model rounds, tool calls, token counts, USD cost, and coverage;
+missing provider data remains `None`. Verifiers are trusted in-process Python callables, not
+sandboxed code loaded from a dataset. See [Batch Runs and Evaluation](evaluation.md).
+
The visual lab automatically appends successful and failed runs to
`.agentmold/visual_runs.jsonl`. The displayed Log ID is the trace `run_id`, so a user can
look up one failed run by ID and inspect the redacted model configuration, events, usage,
diff --git a/docs/architectures.md b/docs/architectures.md
index c9a682e..065f2a4 100644
--- a/docs/architectures.md
+++ b/docs/architectures.md
@@ -5,8 +5,13 @@ everything else as ordinary Python. This page maps five mainstream agent
architectures onto that single primitive, so you can recognise a pattern when
you need it and implement it without a workflow DSL.
-> The visual lab includes an interactive **AGENT 架构演示** panel
-> (`easyagent visual`) that renders an animated flowchart for each pattern below.
+> The visual lab (`easyagent visual`) exposes all five patterns in its top navigation.
+> ReAct opens the configurable single-Agent workbench. The other pages default to a saved
+> real provider profile: model responses drive planning, critique, routing, and delegation.
+> A separately labelled deterministic offline mode uses fixed `ScriptedLLM` responses only
+> to teach control flow and Trace structure. Each page labels its architecture diagram as
+> **concept only, not this run**, then shows Python events separately from real `AgentTrace`
+> records. Completed lessons export JSON, Trace JSONL, and `example.py`.
## Why patterns, not a framework
@@ -27,30 +32,22 @@ minimal implementation.
## ReAct
-EasyAgent's default loop **is** ReAct: the model reasons about what it needs,
-calls a tool, observes the result, and repeats until it can answer. You do
-nothing special -- just give the Agent tools and an instruction that encourages
-step-by-step reasoning.
+EasyAgent's default loop **is** ReAct: the model chooses whether to answer or call a tool,
+observes the result, and repeats until it can answer. You do nothing special: give the Agent
+tools and clear instructions. EasyAgent records public model-round metadata and tool events;
+it does not expose or infer hidden chain-of-thought.
+
+A deterministic offline lesson is also available:
```python
-from agentmold import Agent, tool
-
-@tool
-def retrieve(query: str) -> str:
- """Retrieve relevant chunks from the knowledge base."""
- ...
-
-agent = Agent(
- name="ReActAgent",
- instructions="Think step by step. Use retrieve when you need facts.",
- tools=[retrieve],
- llm="mock",
-)
-answer = agent("What is the relationship between Dao and technique?")
+from agentmold.visual.teaching import run_react_experiment
+
+experiment = run_react_experiment("How does RAG reduce hallucination?")
+print(experiment.output)
```
-The `[THOUGHT] / [ACTION] / [OBSERVATION] / [ANSWER]` trace labels in
-`concepts.md` correspond to the three phases of this loop.
+The returned experiment contains one real Agent trace with a tool call, tool result, and
+answer. The concept diagram's decision node is not inserted into that trace.
---
@@ -61,32 +58,17 @@ steps, then a **Worker** Agent (or the same Agent) executes each step. This is
just two `Agent.run()` calls connected by a `for` loop.
```python
-from agentmold import Agent, tool
-
-planner = Agent(
- name="Planner",
- instructions="Break the task into 3-5 concrete steps. Output a numbered list.",
- llm="mock",
-)
-plan_text = planner("Analyse the methodology of this paper")
-
-worker = Agent(
- name="Worker",
- instructions="Execute the given step using available tools.",
- tools=[retrieve],
- llm="mock",
-)
-
-results = []
-for step in plan_text.strip().split("\n"):
- step = step.strip()
- if step:
- results.append(worker.run(step))
+from agentmold.visual.teaching import run_plan_execute_experiment
+
+experiment = run_plan_execute_experiment("Design an offline knowledge assistant")
+print(experiment.output)
```
-No graph runtime is needed -- the plan is a Python list of strings, and
-execution is a `for` loop. If a step fails, ordinary `try/except` decides
-whether to retry or skip.
+The teaching runner creates a Planner, a fresh Worker for each of three steps, and a
+Synthesizer. Their five real traces remain independent roots; the outer `for` loop is
+recorded as separate `TeachingEvent` objects rather than fake parent-child trace links.
+No graph runtime is needed: the plan is a Python list of strings, and execution is a
+`for` loop. In application code, ordinary `try/except` decides whether to retry or skip.
---
@@ -97,32 +79,16 @@ the feedback. Loop until the Critic is satisfied (or a max-revision count is
hit).
```python
-from agentmold import Agent
-
-generator = Agent(
- name="Writer",
- instructions="Write a concise technical explanation.",
- llm="mock",
-)
-critic = Agent(
- name="Critic",
- instructions=(
- "Review the text for accuracy and clarity. Point out improvements. "
- "If nothing needs changing, reply exactly: DONE"
- ),
- llm="mock",
-)
-
-draft = generator.run("Explain how RAG works")
-for _ in range(3): # at most 3 revision rounds
- feedback = critic.run(draft)
- if "DONE" in feedback:
- break
- draft = generator.run(f"Revise based on this feedback: {feedback}")
+from agentmold.visual.teaching import run_reflection_experiment
+
+experiment = run_reflection_experiment("Explain vector retrieval in two sentences")
+print(experiment.output)
```
-The termination signal ("DONE") is an ordinary string check -- no special event
-type or state machine.
+The deterministic lesson performs exactly one feedback round: Generator draft, Critic
+feedback, Generator revision, then Critic `DONE`. A hard revision bound prevents an
+unexpected response from creating an infinite loop. The termination signal is an ordinary
+string check and the feedback/revision control flow is recorded outside Agent traces.
---
@@ -134,32 +100,21 @@ own instructions and tools. EasyAgent's `agent_as_tool` (in
coordinator can call it naturally.
```python
-from agentmold import Agent
-from agentmold.experimental import agent_as_tool
-
-researcher = Agent(
- name="Researcher",
- instructions="Retrieve and summarise relevant information.",
- llm="mock",
-)
-analyst = Agent(
- name="Analyst",
- instructions="Analyse data and state conclusions with uncertainty.",
- llm="mock",
-)
-
-coordinator = Agent(
- name="Coordinator",
- instructions="Delegate research and analysis, then synthesise a final answer.",
- tools=[agent_as_tool(researcher), agent_as_tool(analyst)],
- llm="mock",
-)
-answer = coordinator.run("tool: Researcher what is RAG?")
+# The lesson uses experimental agent_as_tool internally; that API may change.
+from agentmold.visual.teaching import run_multi_agent_experiment
+
+experiment = run_multi_agent_experiment("Compare keyword and vector retrieval")
+print(experiment.output)
```
-There is no coordinator class -- the coordinator is just another `Agent` whose
-tools happen to be other Agents. See `docs/agent-composition.md` for the full
-API.
+The Coordinator issues two real tool calls in one async model round. Researcher and Analyst
+run as child Agents with the same `parallel_group`, then the Coordinator synthesizes their
+results. There is no coordinator class: it is an ordinary Agent whose tools happen to be
+other Agents. Parent and child runs are linked through `child_run_ids`, `parent_run_id`, and
+`parent_tool_call_id`; the visual replay groups those runs as one family and can export the
+family as a multi-run JSONL bundle. These fields make observed delegation inspectable and
+replayable; they are not an orchestration API. See [Agent composition](agent-composition.md)
+for the experimental API boundary.
---
@@ -170,32 +125,35 @@ plain `if/elif` (or a dict lookup) around multiple Agents -- no router base
class.
```python
-from agentmold import Agent
-
-coder = Agent(name="Coder", instructions="Answer programming questions.", llm="mock")
-writer = Agent(name="Writer", instructions="Answer writing questions.", llm="mock")
-math_agent = Agent(name="MathAgent", instructions="Answer math questions.", llm="mock")
-
-router = Agent(
- name="Router",
- instructions=(
- "Classify the question into one of: Coder, Writer, MathAgent. "
- "Output only the name."
- ),
- llm="mock",
-)
-
-question = "How do I reverse a linked list?"
-expert_name = router.run(question).strip()
-experts = {"Coder": coder, "Writer": writer, "MathAgent": math_agent}
-chosen = experts.get(expert_name, coder)
-answer = chosen.run(question)
+from agentmold.visual.teaching import run_routing_experiment
+
+experiment = run_routing_experiment("Write a Python deduplication function")
+print(experiment.output)
```
-For a classification that does not need an LLM, replace the router Agent with a
-keyword check or any classifier -- the dispatch logic stays the same. See
-[工程实践:意图识别与检索策略](engineering.md) for a three-tier intent recognition
-cascade (rules -> DistilBERT -> LLM) that optimizes cost and latency.
+The lesson uses a deterministic rule to select `Coder`, `Writer`, or `Math`, then runs only
+the selected expert. The Router and selected expert produce real traces; unselected branches
+do not. `route_selected` remains a Python control-flow event. If classification does not
+need an LLM, use the same keyword check or another classifier directly. See
+[Engineering practice](engineering.md) for a rules -> DistilBERT -> LLM cascade that
+optimizes cost and latency.
+
+---
+
+## Live and deterministic runners
+
+The visual lab uses two deliberately separate modules:
+
+- `agentmold.visual.live_teaching`: accepts a model factory. Planner text is parsed into the
+ steps that actually run; Critic `DONE` stops Reflection; Router output selects the only
+ expert; Coordinator tool calls create real child runs. Missing or malformed decisions fail
+ or remain visibly incomplete instead of being repaired into a fake successful architecture.
+- `agentmold.visual.teaching`: uses finite, fixed `ScriptedLLM` queues for offline teaching,
+ tests, and reproducible exports. Its traces are real Agent traces, but its model decisions
+ are prescribed and must not be interpreted as task-solving behavior.
+
+Multi-Agent completeness is an observed fact: a run counts as full collaboration only when
+both specialist tool calls and their correlated child traces exist.
---
diff --git a/docs/capabilities.md b/docs/capabilities.md
index a982bcb..32ef23d 100644
--- a/docs/capabilities.md
+++ b/docs/capabilities.md
@@ -22,8 +22,9 @@ framework than the package provides.
| Built-in providers | Shipped | OpenAI, DeepSeek, Anthropic, DeepSeek Anthropic, and Ollama use explicit provider and model fields through optional extras. |
| Provider text streaming | Shipped | Built-in network providers expose native sync/async chunks; `mock` and extensions may use the complete-response fallback. |
| Memory | Shipped | Short-term `Memory` is core; named `VectorMemory` collections are an optional dependency. |
-| Trace and evaluation | Shipped | JSONL traces, usage metadata, batch evaluation, and isolated regression cases are public APIs. |
-| Visual research lab | Shipped | Streamlit configures or loads one code-defined Agent and visualizes observed events without adding a workflow DSL. |
+| Trace and evaluation | Shipped | Trace v2 records status, model rounds, structured tool results, usage, and parent/child correlation; Eval v2 supports repeated samples and named trusted-Python metrics. |
+| Visual research lab | Shipped | Streamlit exposes ReAct, Plan-and-Execute, Reflection, Multi-Agent, and Routing; the four composition lessons default to saved real models, keep fixed-response offline demos explicitly separate, and provide replay, comparison, evaluation, and export. |
+| Architecture teaching runners | Shipped | Live runners let model output drive Python control flow; deterministic runners remain for offline teaching. Both create real Agent traces plus separate TeachingEvents without inventing missing branches or child runs. |
| Python provider/tool extensions | Shipped | Standard entry points provide explicit discovery; extension loading errors are not hidden. |
| Agent as a tool | Experimental | `agentmold.experimental.agent_as_tool` supports bounded parent/child experiments and correlated traces. |
| Shared provider conformance matrix | Shipped | Every built-in adapter runs through one offline final-chat and tool-round-trip contract suite. |
diff --git a/docs/evaluation.md b/docs/evaluation.md
index f59ffb0..c6ba283 100644
--- a/docs/evaluation.md
+++ b/docs/evaluation.md
@@ -1,15 +1,16 @@
# Batch Runs and Evaluation
-Experiments use an agent factory so every case receives independent memory and trace state:
+Experiments use an agent factory so every sample receives independent memory and trace state:
```python
from agentmold import Agent, EvalCase, evaluate
+
def build_agent() -> Agent:
- # Keep the documentation runnable offline. Swap in an explicit provider + model
- # configuration when the dataset is ready for a hosted evaluation.
+ # This stays runnable offline. Swap in an explicit provider and model when needed.
return Agent(llm="mock")
+
report = evaluate(
build_agent,
[
@@ -32,8 +33,89 @@ report = evaluate(build_agent, ["prompt one", "prompt two"])
```
For async applications use `await aevaluate(...)` and set `concurrency`. Result order always
-matches case order. A failed case is stored in the report instead of aborting the dataset.
+matches case order. A failed sample is stored in the report instead of aborting the dataset,
+and its trace is retained when the Agent started running.
The default scorer performs normalized exact matching. A custom scorer receives
`(output, expected)` and returns `bool` or a numeric score. `pass_threshold` controls which
-numeric scores count as passed.
+numeric scores count as passed. This two-argument scorer remains the compatibility path for
+answer regression tests.
+
+## State and trace verifiers
+
+A named verifier receives an `EvalContext`. It can inspect the case, output, isolated Agent,
+and Trace v2. This is the preferred way to validate environment state, tool selection, tool
+arguments, or multiple acceptable paths without matching one golden answer or trajectory.
+
+```python
+from agentmold import EvalContext, MetricResult
+
+
+def goal_completion(context: EvalContext) -> MetricResult:
+ # In a simulation, read state owned by context.agent or one of its tools.
+ state = context.agent.test_state
+ goals = {
+ "flight_selected": state["flight_id"] is not None,
+ "window_seat": state["seat_type"] == "window",
+ "within_budget": state["total_price"] <= 1000,
+ }
+ completed = sum(goals.values())
+ return MetricResult(
+ score=completed / len(goals),
+ reason=f"{completed} of {len(goals)} goals completed",
+ details=goals,
+ )
+
+
+def tool_selection(context: EvalContext) -> MetricResult:
+ if context.trace is None:
+ return MetricResult(reason="trace unavailable")
+ selected = [event["name"] for event in context.trace.tool_calls]
+ forbidden = sorted(set(selected) & {"delete_file", "send_payment"})
+ return MetricResult(
+ score=0.0 if forbidden else 1.0,
+ details={"selected": selected, "forbidden": forbidden},
+ )
+
+
+report = evaluate(
+ build_agent,
+ cases,
+ repeats=10,
+ verifiers={
+ "goal_completion": goal_completion,
+ "tool_selection": tool_selection,
+ },
+)
+```
+
+Verifiers are trusted in-process Python callables. EasyAgent does not execute verifier source
+stored in JSON or YAML and does not sandbox verifier code. Keep test environments isolated and
+use no-side-effect canary tools when evaluating unsafe tool intent.
+
+## Repeated samples and metrics
+
+`repeats=N` builds a fresh Agent for each sample. Results use case-major, sample-minor order,
+with zero-based `case_index` and `sample_index`. `report.results` contains every sample;
+`report.case_summaries` aggregates repeated samples per case, and
+`report.metric_summaries` aggregates each named metric across the dataset.
+
+A `MetricResult` has three distinct outcomes:
+
+- finite `score`: a computed metric;
+- `score=None` and no error: not applicable or insufficient evidence;
+- `error`: the verifier failed; other metrics and the Agent output remain available.
+
+Boolean verifier results become `1.0` or `0.0`. NaN and infinity become isolated metric errors
+and are never emitted as invalid JSON. Execution failures and metric failures enter the
+`pass_rate` denominator; a metric that is entirely not applicable has `pass_rate=None`.
+
+Trace-derived fields include `runtime_status`, model `rounds`, tool-call count, token usage,
+and USD cost when available. Missing provider usage remains `None`, not zero. Summary fields
+such as `total_tokens_coverage` and `cost_usd_coverage` show how much of the dataset supplied
+the corresponding data. Cost is accepted only from explicit `cost_usd` or `total_cost_usd`
+provider fields.
+
+Runtime completion, task correctness, goal completion, and safety are deliberately separate
+metrics. Use explicit release gates for critical safety or task requirements rather than
+letting a high quality or low cost score compensate for them in one total score.
diff --git a/src/agentmold/__init__.py b/src/agentmold/__init__.py
index 5c2449c..f08c7cb 100644
--- a/src/agentmold/__init__.py
+++ b/src/agentmold/__init__.py
@@ -18,7 +18,15 @@
MCPError,
ToolLoadError,
)
-from agentmold.experiment import EvalCase, EvalReport, EvalResult, aevaluate, evaluate
+from agentmold.experiment import (
+ EvalCase,
+ EvalContext,
+ EvalReport,
+ EvalResult,
+ MetricResult,
+ aevaluate,
+ evaluate,
+)
from agentmold.llm import LLM
from agentmold.loading import load_agent, load_tools
from agentmold.mcp import MCPToolSet, mcp_tools
@@ -47,8 +55,10 @@
"TextDeltaEvent",
"ExtensionLoadError",
"EvalCase",
+ "EvalContext",
"EvalReport",
"EvalResult",
+ "MetricResult",
"LogLevel",
"LLM",
"Memory",
diff --git a/src/agentmold/agent.py b/src/agentmold/agent.py
index 6878773..be74bd9 100644
--- a/src/agentmold/agent.py
+++ b/src/agentmold/agent.py
@@ -74,7 +74,11 @@
]
-class AnswerEvent(TypedDict):
+class _RoundEvent(TypedDict, total=False):
+ round: int
+
+
+class AnswerEvent(_RoundEvent):
type: Literal["answer"]
content: str
@@ -102,16 +106,28 @@ class ToolCallEvent(_ToolCallBase, total=False):
"""
parallel_group: str
+ round: int
+ call_index: int
+ execution_id: str
-class ToolResultEvent(TypedDict):
+class _ToolResultBase(TypedDict):
type: Literal["tool_result"]
id: str | None
name: str
content: str
-class ApprovalRequestEvent(TypedDict):
+class ToolResultEvent(_ToolResultBase, total=False):
+ round: int
+ call_index: int
+ execution_id: str
+ status: Literal["success", "error", "refused", "policy_denied", "timeout", "cancelled"]
+ duration_ms: float
+ error_type: str
+
+
+class _ApprovalRequestBase(TypedDict):
"""Emitted before a confirming tool runs, so the gate is observable.
This event is transient: it describes a pending decision, not a durable
@@ -127,7 +143,13 @@ class ApprovalRequestEvent(TypedDict):
reason: str
-class LoopDetectedEvent(TypedDict):
+class ApprovalRequestEvent(_ApprovalRequestBase, total=False):
+ round: int
+ call_index: int
+ execution_id: str
+
+
+class _LoopDetectedBase(TypedDict):
"""Recorded when the agent repeats an identical tool call and stops.
This is a durable trace event: a stuck loop is a diagnostic fact worth
@@ -142,6 +164,12 @@ class LoopDetectedEvent(TypedDict):
message: str
+class LoopDetectedEvent(_LoopDetectedBase, total=False):
+ round: int
+ call_index: int
+ execution_id: str
+
+
TraceEvent = typing.Union[ # noqa: UP007
AnswerEvent, ToolCallEvent, ToolResultEvent, LoopDetectedEvent
]
@@ -184,6 +212,12 @@ class AgentTrace:
tool_schemas: list[dict[str, Any]] = field(default_factory=list)
event_times: list[str] = field(default_factory=list, repr=False)
_started_monotonic: float = field(default_factory=time.perf_counter, repr=False)
+ trace_version: int = field(default=2, kw_only=True)
+ model_calls: list[dict[str, Any]] = field(default_factory=list, kw_only=True)
+ status: Literal["running", "completed", "failed", "interrupted", "cancelled"] = field(
+ default="running", kw_only=True
+ )
+ _child_traces: list[AgentTrace] = field(default_factory=list, repr=False, kw_only=True)
def add(self, step: TraceEvent) -> None:
self.steps.append(step)
@@ -195,13 +229,45 @@ def add_usage(self, raw_response: Any) -> None:
for key, value in usage.items():
self.usage[key] = self.usage.get(key, 0) + value
- def finish(self, error: str | None = None) -> None:
+ def add_model_call(
+ self,
+ *,
+ round_number: int,
+ provider: str,
+ model: str,
+ status: Literal["completed", "failed", "interrupted", "cancelled"],
+ duration_ms: float,
+ response_kind: Literal["answer", "tool_calls"] | None = None,
+ usage: dict[str, int | float] | None = None,
+ error: str | None = None,
+ ) -> None:
+ """Record one model round without retaining the provider's raw response."""
+ model_call: dict[str, Any] = {
+ "round": round_number,
+ "provider": provider,
+ "model": model,
+ "status": status,
+ "duration_ms": round(duration_ms, 3),
+ "response_kind": response_kind,
+ "usage": dict(usage or {}),
+ }
+ if error is not None:
+ model_call["error"] = error
+ self.model_calls.append(model_call)
+
+ def finish(
+ self,
+ error: str | None = None,
+ *,
+ status: Literal["completed", "failed", "interrupted", "cancelled"] | None = None,
+ ) -> None:
"""Mark the run complete. Calling this method more than once is harmless."""
if self.ended_at is not None:
return
self.ended_at = _utc_now()
self.duration_ms = round((time.perf_counter() - self._started_monotonic) * 1000, 3)
self.error = error
+ self.status = status or ("failed" if error is not None else "completed")
def to_dict(self) -> dict[str, Any]:
"""Return a JSON-serializable representation of the full run."""
@@ -210,6 +276,7 @@ def to_dict(self) -> dict[str, Any]:
recorded_at = self.event_times[index] if index < len(self.event_times) else None
events.append({"recorded_at": recorded_at, **step})
return {
+ "trace_version": self.trace_version,
"run_id": self.run_id,
"parent_run_id": self.parent_run_id,
"parent_tool_call_id": self.parent_tool_call_id,
@@ -221,10 +288,12 @@ def to_dict(self) -> dict[str, Any]:
"model_config": self.model_config,
"tool_schemas": self.tool_schemas,
"usage": self.usage,
+ "model_calls": self.model_calls,
"started_at": self.started_at,
"ended_at": self.ended_at,
"duration_ms": self.duration_ms,
"error": self.error,
+ "status": self.status,
"events": events,
"max_iterations": self.max_iterations,
}
@@ -249,6 +318,32 @@ def to_jsonl(self, path: str | Path, append: bool = False) -> Path:
output.write("\n")
return output_path
+ def export_family(self, path: str | Path, append: bool = False) -> Path:
+ """Write this trace and all child traces to a single JSONL file.
+
+ Child traces are collected by walking ``_child_traces`` (object
+ references registered by ``_start_trace``). The file is compatible
+ with ``parse_trace_jsonl`` and the Trace Lab importer.
+ """
+ output_path = Path(path)
+ output_path.parent.mkdir(parents=True, exist_ok=True)
+ mode = "a" if append else "w"
+ with output_path.open(mode, encoding="utf-8") as output:
+ for trace in _trace_family(self):
+ run = trace.to_dict()
+ events = run.pop("events")
+ output.write(json.dumps({"record_type": "run", **run}, ensure_ascii=False))
+ output.write("\n")
+ for event in events:
+ output.write(
+ json.dumps(
+ {"record_type": "event", "run_id": trace.run_id, **event},
+ ensure_ascii=False,
+ )
+ )
+ output.write("\n")
+ return output_path
+
@property
def tool_calls(self) -> list[ToolCallEvent]:
return [step for step in self.steps if step["type"] == "tool_call"]
@@ -263,6 +358,31 @@ def __repr__(self) -> str:
)
+def _trace_family(root: AgentTrace) -> list[AgentTrace]:
+ """Collect root and all descendant traces in dependency order."""
+ family: list[AgentTrace] = []
+ seen: set[str] = set()
+
+ def walk(trace: AgentTrace) -> None:
+ if trace.run_id in seen:
+ return
+ seen.add(trace.run_id)
+ family.append(trace)
+ for child in trace._child_traces:
+ walk(child)
+
+ walk(root)
+ return family
+
+
+@dataclass(frozen=True)
+class _ToolExecutionResult:
+ content: str
+ status: Literal["success", "error", "refused", "policy_denied", "timeout", "cancelled"]
+ duration_ms: float
+ error_type: str | None = None
+
+
class _AgentLogger:
"""Thin wrapper that respects :class:`LogLevel`."""
@@ -501,11 +621,43 @@ def run_stream(self, user_input: str) -> Iterator[AgentEvent]:
trace.tool_schemas = json.loads(json.dumps(tool_schemas, ensure_ascii=False))
for iteration in range(1, self.max_iterations + 1):
messages = self.memory.messages()
- response = yield from self._stream_llm_response(
- messages,
- tool_schemas or None,
- )
+ model_started = time.perf_counter()
+ try:
+ response = yield from self._stream_llm_response(
+ messages,
+ tool_schemas or None,
+ )
+ except GeneratorExit:
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="interrupted",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ error="Model stream interrupted.",
+ )
+ raise
+ except Exception as exc:
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="failed",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ error=f"{type(exc).__name__}: {exc}",
+ )
+ raise
+ usage = _extract_usage(response.raw)
trace.add_usage(response.raw)
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="completed",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ response_kind="tool_calls" if response.tool_calls else "answer",
+ usage=usage,
+ )
if not response.tool_calls:
self.log.answer(response.content)
@@ -513,6 +665,7 @@ def run_stream(self, user_input: str) -> Iterator[AgentEvent]:
answer_event: AnswerEvent = {
"type": "answer",
"content": response.content,
+ "round": iteration,
}
trace.add(answer_event)
trace.finish()
@@ -526,24 +679,31 @@ def run_stream(self, user_input: str) -> Iterator[AgentEvent]:
tool_calls=response.tool_calls,
)
)
- for call in response.tool_calls:
+ calls = self._prepare_tool_calls(list(response.tool_calls), iteration)
+ for call in calls:
tool_name = call["name"]
- arguments = call.get("arguments", {})
- call_id = call.get("id")
+ arguments = call["arguments"]
self.log.thought(
f"Iteration {iteration}: calling tool {tool_name}({arguments})"
)
self.log.action(f"Calling tool: {tool_name}({arguments})")
- loop_event = self._record_loop(loop_guard, tool_name, arguments)
+ call_event = self._tool_call_event(call)
+ trace.add(call_event)
+ yield call_event
+ loop_event = self._record_loop(loop_guard, call)
if loop_event is not None:
trace.add(loop_event)
yield loop_event
raise LoopDetectedError(loop_event["message"])
- approval = yield from self._request_approval(tool_name, arguments, call_id)
+ approval_event = self._approval_event(call)
+ if approval_event is not None:
+ yield approval_event
+ approval = (
+ self._resolve_approval(tool_name, arguments)
+ if approval_event is not None
+ else None
+ )
if approval is not None:
- # The approval event was emitted and refused; surface a
- # refusal as the tool result instead of executing.
- self.log.observation(f"{tool_name} -> {approval}")
self._audit.record(
run_id=trace.run_id,
tool=tool_name,
@@ -552,63 +712,23 @@ def run_stream(self, user_input: str) -> Iterator[AgentEvent]:
refused=True,
duration_ms=0.0,
)
- refusal_event: ToolResultEvent = {
- "type": "tool_result",
- "id": call_id,
- "name": tool_name,
- "content": approval,
- }
- trace.add(refusal_event)
- yield refusal_event
- self.memory.add(
- Message(
- role="tool",
- name=tool_name,
- tool_call_id=call_id,
- content=approval,
- )
+ result = _ToolExecutionResult(
+ content=approval,
+ status="refused",
+ duration_ms=0.0,
)
- continue
- call_event: ToolCallEvent = {
- "type": "tool_call",
- "id": call_id,
- "name": tool_name,
- "arguments": arguments,
- }
- trace.add(call_event)
- yield call_event
- parent_token = _TRACE_PARENT.set((trace, call_id))
- started = time.perf_counter()
- try:
- result = self.registry.call(tool_name, arguments)
- except ToolError as exc:
- result = f"Error: {exc}"
- finally:
- _TRACE_PARENT.reset(parent_token)
- duration_ms = (time.perf_counter() - started) * 1000
- self._audit.record(
- run_id=trace.run_id,
- tool=tool_name,
- arguments=arguments,
- outcome=result,
- refused=False,
- duration_ms=duration_ms,
- )
- self.log.observation(f"{tool_name} -> {result}")
- result_event: ToolResultEvent = {
- "type": "tool_result",
- "id": call_id,
- "name": tool_name,
- "content": result,
- }
+ else:
+ result = self._call_one_tool_sync(call, trace)
+ self.log.observation(f"{tool_name} -> {result.content}")
+ result_event = self._tool_result_event(call, result)
trace.add(result_event)
yield result_event
self.memory.add(
Message(
role="tool",
name=tool_name,
- tool_call_id=call_id,
- content=result,
+ tool_call_id=call["id"],
+ content=result.content,
)
)
@@ -616,12 +736,21 @@ def run_stream(self, user_input: str) -> Iterator[AgentEvent]:
f"Agent {self.name!r} exceeded max_iterations={self.max_iterations} "
"without producing a final answer. Increase max_iterations or simplify the task."
)
+ except GeneratorExit:
+ trace.finish(
+ error="Run interrupted before a final answer.",
+ status="interrupted",
+ )
+ raise
except Exception as exc:
- trace.finish(error=f"{type(exc).__name__}: {exc}")
+ trace.finish(error=f"{type(exc).__name__}: {exc}", status="failed")
raise
finally:
if trace.ended_at is None:
- trace.finish(error="Run interrupted before a final answer.")
+ trace.finish(
+ error="Run interrupted before a final answer.",
+ status="interrupted",
+ )
async def arun_stream(self, user_input: str) -> AsyncIterator[AgentEvent]:
"""Asynchronously yield the same event contract as :meth:`run_stream`."""
@@ -636,21 +765,63 @@ async def arun_stream(self, user_input: str) -> AsyncIterator[AgentEvent]:
messages = self.memory.messages()
response: LlmResponse | None = None
streamed_text: list[str] = []
- async for llm_event in self.llm.astream(messages, tools=tool_schemas or None):
- if response is not None:
- raise LLMError("LLM stream emitted an event after its final response.")
- if llm_event["type"] == "text_delta":
- content = llm_event["content"]
- if content:
- streamed_text.append(content)
- yield TextDeltaEvent(type="text_delta", content=content)
- continue
- if llm_event["type"] == "response":
- response = llm_event["response"]
- continue
- raise LLMError(f"Unsupported LLM stream event: {llm_event!r}")
- response = _validate_stream_response(response, streamed_text)
+ model_started = time.perf_counter()
+ try:
+ async for llm_event in self.llm.astream(messages, tools=tool_schemas or None):
+ if response is not None:
+ raise LLMError("LLM stream emitted an event after its final response.")
+ if llm_event["type"] == "text_delta":
+ content = llm_event["content"]
+ if content:
+ streamed_text.append(content)
+ yield TextDeltaEvent(type="text_delta", content=content)
+ continue
+ if llm_event["type"] == "response":
+ response = llm_event["response"]
+ continue
+ raise LLMError(f"Unsupported LLM stream event: {llm_event!r}")
+ response = _validate_stream_response(response, streamed_text)
+ except asyncio.CancelledError:
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="cancelled",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ error="Model call cancelled.",
+ )
+ raise
+ except GeneratorExit:
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="interrupted",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ error="Model stream interrupted.",
+ )
+ raise
+ except Exception as exc:
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="failed",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ error=f"{type(exc).__name__}: {exc}",
+ )
+ raise
+ usage = _extract_usage(response.raw)
trace.add_usage(response.raw)
+ trace.add_model_call(
+ round_number=iteration,
+ provider=type(self.llm).__name__,
+ model=self.llm.model,
+ status="completed",
+ duration_ms=(time.perf_counter() - model_started) * 1000,
+ response_kind="tool_calls" if response.tool_calls else "answer",
+ usage=usage,
+ )
if not response.tool_calls:
self.log.answer(response.content)
@@ -658,6 +829,7 @@ async def arun_stream(self, user_input: str) -> AsyncIterator[AgentEvent]:
answer_event: AnswerEvent = {
"type": "answer",
"content": response.content,
+ "round": iteration,
}
trace.add(answer_event)
trace.finish()
@@ -671,62 +843,48 @@ async def arun_stream(self, user_input: str) -> AsyncIterator[AgentEvent]:
tool_calls=response.tool_calls,
)
)
- calls = list(response.tool_calls)
- # Loop detection runs first, regardless of execution order.
+ calls = self._prepare_tool_calls(list(response.tool_calls), iteration)
+ parallel = self._can_run_parallel(calls)
+ if parallel:
+ self.log.thought(
+ f"Iteration {iteration}: running {len(calls)} independent "
+ "tool calls in parallel."
+ )
for call in calls:
tool_name = call["name"]
- arguments = call.get("arguments", {})
+ arguments = call["arguments"]
self.log.thought(
f"Iteration {iteration}: calling tool {tool_name}({arguments})"
)
self.log.action(f"Calling tool: {tool_name}({arguments})")
- loop_event = self._record_loop(loop_guard, tool_name, arguments)
+ call_event = self._tool_call_event(
+ call,
+ f"{trace.run_id}:{iteration}" if parallel else None,
+ )
+ trace.add(call_event)
+ yield call_event
+ loop_event = self._record_loop(loop_guard, call)
if loop_event is not None:
trace.add(loop_event)
yield loop_event
raise LoopDetectedError(loop_event["message"])
-
- parallel = self._can_run_parallel(calls)
- if parallel:
- self.log.thought(
- f"Iteration {iteration}: running {len(calls)} independent "
- "tool calls in parallel."
- )
- # Emit every tool_call up front so observers see the model's
- # full intent before any result arrives. Execution below either
- # runs the calls concurrently (independent, no confirmation
- # required) or one at a time (a confirmation gate is present).
- for call in calls:
- call_event: ToolCallEvent = {
- "type": "tool_call",
- "id": call.get("id"),
- "name": call["name"],
- "arguments": call.get("arguments", {}),
- }
- if parallel:
- call_event["parallel_group"] = f"{trace.run_id}:{iteration}"
- trace.add(call_event)
- yield call_event
+ approval_event = self._approval_event(call)
+ if approval_event is not None:
+ yield approval_event
results = await self._execute_tool_calls(calls, parallel, trace)
for call, result in zip(calls, results):
tool_name = call["name"]
- call_id = call.get("id")
- self.log.observation(f"{tool_name} -> {result}")
- result_event: ToolResultEvent = {
- "type": "tool_result",
- "id": call_id,
- "name": tool_name,
- "content": result,
- }
+ self.log.observation(f"{tool_name} -> {result.content}")
+ result_event = self._tool_result_event(call, result)
trace.add(result_event)
yield result_event
self.memory.add(
Message(
role="tool",
name=tool_name,
- tool_call_id=call_id,
- content=result,
+ tool_call_id=call["id"],
+ content=result.content,
)
)
@@ -734,12 +892,24 @@ async def arun_stream(self, user_input: str) -> AsyncIterator[AgentEvent]:
f"Agent {self.name!r} exceeded max_iterations={self.max_iterations} "
"without producing a final answer. Increase max_iterations or simplify the task."
)
+ except asyncio.CancelledError:
+ trace.finish(error="Run cancelled.", status="cancelled")
+ raise
+ except GeneratorExit:
+ trace.finish(
+ error="Run interrupted before a final answer.",
+ status="interrupted",
+ )
+ raise
except Exception as exc:
- trace.finish(error=f"{type(exc).__name__}: {exc}")
+ trace.finish(error=f"{type(exc).__name__}: {exc}", status="failed")
raise
finally:
if trace.ended_at is None:
- trace.finish(error="Run interrupted before a final answer.")
+ trace.finish(
+ error="Run interrupted before a final answer.",
+ status="interrupted",
+ )
def chat(self) -> None:
"""Start an interactive REPL session with the agent.
@@ -776,49 +946,72 @@ def tools(self) -> list[Tool]:
# ------------------------------------------------------------------
# Internals
# ------------------------------------------------------------------
- def _request_approval(
- self,
- tool_name: str,
- arguments: dict[str, Any],
- call_id: str | None,
- ) -> typing.Generator[ApprovalRequestEvent, None, str | None]:
- """Yield an ``approval_request`` event for a confirming tool and resolve it.
-
- Returns ``None`` when the call may proceed (the tool does not require
- confirmation, or the approver allowed it), otherwise a refusal message
- to surface as the tool result. The event is transient — it lets stream
- consumers and the visual lab observe the gate before any side effect.
- """
- tool = self.registry.get(tool_name)
- if not tool.confirm:
+ def _prepare_tool_calls(
+ self, calls: list[dict[str, Any]], round_number: int
+ ) -> list[dict[str, Any]]:
+ prepared: list[dict[str, Any]] = []
+ for call_index, call in enumerate(calls, start=1):
+ arguments = _json_snapshot(call.get("arguments", {}))
+ prepared.append(
+ {
+ "id": call.get("id"),
+ "name": call["name"],
+ "arguments": arguments,
+ "trace_arguments": _json_snapshot(arguments),
+ "round": round_number,
+ "call_index": call_index,
+ "execution_id": uuid4().hex,
+ }
+ )
+ return prepared
+
+ @staticmethod
+ def _tool_call_event(call: dict[str, Any], parallel_group: str | None = None) -> ToolCallEvent:
+ event: ToolCallEvent = {
+ "type": "tool_call",
+ "id": call["id"],
+ "name": call["name"],
+ "arguments": call["trace_arguments"],
+ "round": call["round"],
+ "call_index": call["call_index"],
+ "execution_id": call["execution_id"],
+ }
+ if parallel_group is not None:
+ event["parallel_group"] = parallel_group
+ return event
+
+ @staticmethod
+ def _tool_result_event(call: dict[str, Any], result: _ToolExecutionResult) -> ToolResultEvent:
+ event: ToolResultEvent = {
+ "type": "tool_result",
+ "id": call["id"],
+ "name": call["name"],
+ "content": result.content,
+ "round": call["round"],
+ "call_index": call["call_index"],
+ "execution_id": call["execution_id"],
+ "status": result.status,
+ "duration_ms": round(result.duration_ms, 3),
+ }
+ if result.error_type is not None:
+ event["error_type"] = result.error_type
+ return event
+
+ def _approval_event(self, call: dict[str, Any]) -> ApprovalRequestEvent | None:
+ if call["name"] not in self.registry:
+ return None
+ if not self.registry.get(call["name"]).confirm:
return None
- event: ApprovalRequestEvent = {
+ return {
"type": "approval_request",
- "id": call_id,
- "name": tool_name,
- "arguments": arguments,
+ "id": call["id"],
+ "name": call["name"],
+ "arguments": call["trace_arguments"],
"reason": "tool is marked confirm=True",
+ "round": call["round"],
+ "call_index": call["call_index"],
+ "execution_id": call["execution_id"],
}
- yield event
- return self._resolve_approval(tool_name, arguments)
-
- async def _arequest_approval(
- self,
- tool_name: str,
- arguments: dict[str, Any],
- call_id: str | None,
- ) -> str | None:
- """Async counterpart of :meth:`_request_approval`.
-
- The transient ``approval_request`` event is not yielded here because an
- async generator cannot pause mid-loop to a synchronous caller; the
- decision log line still records the gate. The refusal/allow outcome is
- identical to the synchronous path.
- """
- tool = self.registry.get(tool_name)
- if not tool.confirm:
- return None
- return self._resolve_approval(tool_name, arguments)
def _resolve_approval(self, tool_name: str, arguments: dict[str, Any]) -> str | None:
"""Decide whether a confirming tool may run; return a refusal or ``None``."""
@@ -846,16 +1039,11 @@ def _resolve_approval(self, tool_name: str, arguments: dict[str, Any]) -> str |
def _record_loop(
self,
guard: _LoopGuard,
- tool_name: str,
- arguments: dict[str, Any],
+ call: dict[str, Any],
) -> LoopDetectedEvent | None:
- """Record a tool call and return a ``loop_detected`` event when stuck.
-
- Returns ``None`` while the run is making progress. When the same call
- repeats ``loop_detection_threshold`` times in a row, returns an event
- whose message doubles as the ``LoopDetectedError`` text, with a hint
- for how to recover.
- """
+ """Record a tool call and return a loop event when the call is stuck."""
+ tool_name = call["name"]
+ arguments = call["trace_arguments"]
count = guard.record(tool_name, arguments)
if not guard.tripped(count):
return None
@@ -872,8 +1060,42 @@ def _record_loop(
"arguments": arguments,
"occurrences": count,
"message": message,
+ "round": call["round"],
+ "call_index": call["call_index"],
+ "execution_id": call["execution_id"],
}
+ def _call_one_tool_sync(self, call: dict[str, Any], trace: AgentTrace) -> _ToolExecutionResult:
+ tool_name = call["name"]
+ arguments = call["arguments"]
+ parent_token = _TRACE_PARENT.set((trace, call["id"]))
+ started = time.perf_counter()
+ status: Literal["success", "error"] = "success"
+ error_type: str | None = None
+ try:
+ content = self.registry.call(tool_name, arguments)
+ except ToolError as exc:
+ content = f"Error: {exc}"
+ status = "error"
+ error_type = type(exc).__name__
+ finally:
+ _TRACE_PARENT.reset(parent_token)
+ duration_ms = (time.perf_counter() - started) * 1000
+ self._audit.record(
+ run_id=trace.run_id,
+ tool=tool_name,
+ arguments=arguments,
+ outcome=content,
+ refused=False,
+ duration_ms=duration_ms,
+ )
+ return _ToolExecutionResult(
+ content=content,
+ status=status,
+ duration_ms=duration_ms,
+ error_type=error_type,
+ )
+
def _can_run_parallel(self, calls: list[dict[str, Any]]) -> bool:
"""Whether this turn's tool calls may run concurrently on the async path.
@@ -884,67 +1106,80 @@ def _can_run_parallel(self, calls: list[dict[str, Any]]) -> bool:
"""
if len(calls) < 2:
return False
- return all(not self.registry.get(call["name"]).confirm for call in calls)
+ return all(
+ call["name"] in self.registry and not self.registry.get(call["name"]).confirm
+ for call in calls
+ )
async def _execute_tool_calls(
self,
calls: list[dict[str, Any]],
parallel: bool,
trace: AgentTrace,
- ) -> list[str]:
- """Execute a turn's tool calls and return their results in call order.
-
- On the parallel path the calls run with ``asyncio.gather`` (results are
- still returned in the original order, so the emitted events stay
- deterministic). On the sequential path each call is awaited in turn and
- still passes through the confirmation gate.
- """
+ ) -> list[_ToolExecutionResult]:
+ """Execute a turn's tool calls and return results in original order."""
if parallel:
return await asyncio.gather(*(self._call_one_tool(call, trace) for call in calls))
- results: list[str] = []
+ results: list[_ToolExecutionResult] = []
for call in calls:
- results.append(await self._call_one_tool(call, trace, check_approval=True))
+ approval_event = self._approval_event(call)
+ if approval_event is not None:
+ refusal = self._resolve_approval(call["name"], call["arguments"])
+ if refusal is not None:
+ self._audit.record(
+ run_id=trace.run_id,
+ tool=call["name"],
+ arguments=call["arguments"],
+ outcome=refusal,
+ refused=True,
+ duration_ms=0.0,
+ )
+ results.append(
+ _ToolExecutionResult(
+ content=refusal,
+ status="refused",
+ duration_ms=0.0,
+ )
+ )
+ continue
+ results.append(await self._call_one_tool(call, trace))
return results
async def _call_one_tool(
self,
call: dict[str, Any],
trace: AgentTrace,
- check_approval: bool = False,
- ) -> str:
- """Run one tool call to a string result, mapping errors to text."""
+ ) -> _ToolExecutionResult:
+ """Run one tool call and preserve its structured outcome."""
tool_name = call["name"]
- arguments = call.get("arguments", {})
- call_id = call.get("id")
- if check_approval and self.registry.get(tool_name).confirm:
- refusal = self._resolve_approval(tool_name, arguments)
- if refusal is not None:
- self._audit.record(
- run_id=trace.run_id,
- tool=tool_name,
- arguments=arguments,
- outcome=refusal,
- refused=True,
- duration_ms=0.0,
- )
- return refusal
- parent_token = _TRACE_PARENT.set((trace, call_id))
+ arguments = call["arguments"]
+ parent_token = _TRACE_PARENT.set((trace, call["id"]))
started = time.perf_counter()
+ status: Literal["success", "error"] = "success"
+ error_type: str | None = None
try:
- result = await self.registry.acall(tool_name, arguments)
+ content = await self.registry.acall(tool_name, arguments)
except ToolError as exc:
- result = f"Error: {exc}"
+ content = f"Error: {exc}"
+ status = "error"
+ error_type = type(exc).__name__
finally:
_TRACE_PARENT.reset(parent_token)
+ duration_ms = (time.perf_counter() - started) * 1000
self._audit.record(
run_id=trace.run_id,
tool=tool_name,
arguments=arguments,
- outcome=result,
+ outcome=content,
refused=False,
- duration_ms=(time.perf_counter() - started) * 1000,
+ duration_ms=duration_ms,
+ )
+ return _ToolExecutionResult(
+ content=content,
+ status=status,
+ duration_ms=duration_ms,
+ error_type=error_type,
)
- return result
def _stream_llm_response(
self,
@@ -1007,6 +1242,7 @@ def _start_trace(self, user_input: str = "") -> AgentTrace:
)
if parent_trace is not None and trace.run_id not in parent_trace.child_run_ids:
parent_trace.child_run_ids.append(trace.run_id)
+ parent_trace._child_traces.append(trace)
self.last_trace = trace
return trace
@@ -1037,6 +1273,11 @@ def _utc_now() -> str:
return datetime.now(timezone.utc).isoformat()
+def _json_snapshot(value: Any) -> Any:
+ """Copy trace data into a stable JSON-safe representation."""
+ return json.loads(json.dumps(value, ensure_ascii=False, default=str))
+
+
def _interactive_approval(tool_name: str, arguments: dict[str, Any]) -> bool:
"""Prompt a human to approve a destructive tool call in an interactive session.
diff --git a/src/agentmold/experiment.py b/src/agentmold/experiment.py
index 158f8f8..72dedf0 100644
--- a/src/agentmold/experiment.py
+++ b/src/agentmold/experiment.py
@@ -4,8 +4,9 @@
import asyncio
import json
+import math
import time
-from collections.abc import Callable, Iterable
+from collections.abc import Callable, Iterable, Mapping
from concurrent.futures import ThreadPoolExecutor
from dataclasses import dataclass, field
from pathlib import Path
@@ -13,7 +14,15 @@
from agentmold.agent import Agent, AgentTrace
-__all__ = ["EvalCase", "EvalResult", "EvalReport", "evaluate", "aevaluate"]
+__all__ = [
+ "EvalCase",
+ "EvalContext",
+ "MetricResult",
+ "EvalResult",
+ "EvalReport",
+ "evaluate",
+ "aevaluate",
+]
Scorer = Callable[[str, str], bool | float]
AgentFactory = Callable[[], Agent]
@@ -29,9 +38,43 @@ class EvalCase:
metadata: dict[str, Any] = field(default_factory=dict)
+@dataclass(frozen=True)
+class EvalContext:
+ """Trusted Python context passed to a named evaluation verifier."""
+
+ case: EvalCase
+ agent: Agent
+ output: str
+ trace: AgentTrace | None
+ case_index: int = 0
+ sample_index: int = 0
+
+
+@dataclass(frozen=True)
+class MetricResult:
+ """One metric value, an explicit NA, or an isolated verifier error."""
+
+ score: float | None = None
+ reason: str | None = None
+ details: dict[str, Any] = field(default_factory=dict)
+ error: str | None = None
+
+ def to_dict(self) -> dict[str, Any]:
+ return {
+ "score": self.score,
+ "reason": self.reason,
+ "details": _json_value(self.details),
+ "error": self.error,
+ }
+
+
+VerifierValue = bool | float | MetricResult | None
+Verifier = Callable[[EvalContext], VerifierValue]
+
+
@dataclass
class EvalResult:
- """The outcome of one independent evaluation case."""
+ """The outcome of one independent evaluation sample."""
case: EvalCase
output: str = ""
@@ -39,32 +82,66 @@ class EvalResult:
error: str | None = None
duration_ms: float = 0.0
trace: AgentTrace | None = None
+ case_index: int = 0
+ sample_index: int = 0
+ metrics: dict[str, MetricResult] = field(default_factory=dict)
+ runtime_status: str | None = None
+ rounds: int | None = None
+ tool_calls: int | None = None
+ total_tokens: float | None = None
+ cost_usd: float | None = None
def to_dict(self) -> dict[str, Any]:
return {
"name": self.case.name,
"input": self.case.input,
"expected": self.case.expected,
- "metadata": self.case.metadata,
+ "metadata": _json_value(self.case.metadata),
"output": self.output,
"score": self.score,
"error": self.error,
"duration_ms": self.duration_ms,
"trace": self.trace.to_dict() if self.trace else None,
+ "case_index": self.case_index,
+ "sample_index": self.sample_index,
+ "metrics": {name: metric.to_dict() for name, metric in self.metrics.items()},
+ "runtime_status": self.runtime_status,
+ "rounds": self.rounds,
+ "tool_calls": self.tool_calls,
+ "total_tokens": self.total_tokens,
+ "cost_usd": self.cost_usd,
}
@dataclass
class EvalReport:
- """Aggregate results for a batch or evaluation dataset."""
+ """Aggregate sample, case, metric, and runtime results for a dataset."""
results: list[EvalResult]
pass_threshold: float = 1.0
+ repeats: int = 1
+ case_count: int | None = None
+ metric_names: tuple[str, ...] = ()
+
+ def __post_init__(self) -> None:
+ if self.case_count is None:
+ self.case_count = max((result.case_index for result in self.results), default=-1) + 1
+ if not self.metric_names:
+ names: list[str] = []
+ for result in self.results:
+ for name in result.metrics:
+ if name not in names:
+ names.append(name)
+ self.metric_names = tuple(names)
@property
def total(self) -> int:
return len(self.results)
+ @property
+ def sample_count(self) -> int:
+ return self.total
+
@property
def failed(self) -> int:
return sum(result.error is not None for result in self.results)
@@ -85,6 +162,34 @@ def mean_score(self) -> float | None:
scores = [result.score for result in self.results if result.score is not None]
return sum(scores) / len(scores) if scores else None
+ @property
+ def metric_summaries(self) -> dict[str, dict[str, Any]]:
+ return {
+ name: _summarize_metric(self.results, name, self.pass_threshold)
+ for name in self.metric_names
+ }
+
+ @property
+ def case_summaries(self) -> list[dict[str, Any]]:
+ summaries: list[dict[str, Any]] = []
+ for case_index in range(self.case_count or 0):
+ samples = [result for result in self.results if result.case_index == case_index]
+ case = samples[0].case if samples else None
+ summaries.append(
+ {
+ "case_index": case_index,
+ "name": case.name if case else "",
+ "input": case.input if case else "",
+ "samples": len(samples),
+ "failed": sum(result.error is not None for result in samples),
+ "metrics": {
+ name: _summarize_metric(samples, name, self.pass_threshold)
+ for name in self.metric_names
+ },
+ }
+ )
+ return summaries
+
def to_dict(self) -> dict[str, Any]:
return {
"summary": {
@@ -94,7 +199,13 @@ def to_dict(self) -> dict[str, Any]:
"passed": self.passed,
"pass_threshold": self.pass_threshold,
"mean_score": self.mean_score,
+ "case_count": self.case_count,
+ "sample_count": self.sample_count,
+ "repeats": self.repeats,
+ "metrics": self.metric_summaries,
+ **_summarize_run_stats(self.results),
},
+ "case_summaries": self.case_summaries,
"results": [result.to_dict() for result in self.results],
}
@@ -102,7 +213,7 @@ def to_json(self, path: str | Path) -> Path:
output_path = Path(path)
output_path.parent.mkdir(parents=True, exist_ok=True)
output_path.write_text(
- json.dumps(self.to_dict(), ensure_ascii=False, indent=2),
+ json.dumps(self.to_dict(), ensure_ascii=False, indent=2, allow_nan=False),
encoding="utf-8",
)
return output_path
@@ -112,7 +223,7 @@ def to_jsonl(self, path: str | Path) -> Path:
output_path.parent.mkdir(parents=True, exist_ok=True)
with output_path.open("w", encoding="utf-8") as output:
for result in self.results:
- output.write(json.dumps(result.to_dict(), ensure_ascii=False))
+ output.write(json.dumps(result.to_dict(), ensure_ascii=False, allow_nan=False))
output.write("\n")
return output_path
@@ -123,21 +234,24 @@ def evaluate(
scorer: Scorer | None = None,
workers: int = 1,
pass_threshold: float = 1.0,
+ *,
+ repeats: int = 1,
+ verifiers: Mapping[str, Verifier] | None = None,
) -> EvalReport:
- """Run independent cases, optionally scoring them against expected answers."""
+ """Run independent samples and apply trusted Python verifiers."""
if workers < 1:
raise ValueError("workers must be >= 1")
- prepared = [_coerce_case(case) for case in cases]
+ prepared, verifier_map, work = _prepare(cases, repeats, verifiers, pass_threshold)
- def run(case: EvalCase) -> EvalResult:
- return _run_case(build_agent, case, scorer)
+ def run(item: tuple[int, int, EvalCase]) -> EvalResult:
+ return _run_case(build_agent, item, scorer, verifier_map)
if workers == 1:
- results = [run(case) for case in prepared]
+ results = [run(item) for item in work]
else:
with ThreadPoolExecutor(max_workers=workers) as executor:
- results = list(executor.map(run, prepared))
- return EvalReport(results=results, pass_threshold=pass_threshold)
+ results = list(executor.map(run, work))
+ return _build_report(results, len(prepared), repeats, pass_threshold, verifier_map)
async def aevaluate(
@@ -146,63 +260,306 @@ async def aevaluate(
scorer: Scorer | None = None,
concurrency: int = 4,
pass_threshold: float = 1.0,
+ *,
+ repeats: int = 1,
+ verifiers: Mapping[str, Verifier] | None = None,
) -> EvalReport:
- """Asynchronously run independent cases with bounded concurrency."""
+ """Asynchronously run independent samples with bounded concurrency."""
if concurrency < 1:
raise ValueError("concurrency must be >= 1")
- prepared = [_coerce_case(case) for case in cases]
+ prepared, verifier_map, work = _prepare(cases, repeats, verifiers, pass_threshold)
semaphore = asyncio.Semaphore(concurrency)
- async def run(case: EvalCase) -> EvalResult:
+ async def run(item: tuple[int, int, EvalCase]) -> EvalResult:
async with semaphore:
- return await _arun_case(build_agent, case, scorer)
+ return await _arun_case(build_agent, item, scorer, verifier_map)
- results = await asyncio.gather(*(run(case) for case in prepared))
- return EvalReport(results=results, pass_threshold=pass_threshold)
+ results = await asyncio.gather(*(run(item) for item in work))
+ return _build_report(results, len(prepared), repeats, pass_threshold, verifier_map)
-def _run_case(build_agent: AgentFactory, case: EvalCase, scorer: Scorer | None) -> EvalResult:
+def _prepare(
+ cases: Iterable[str | EvalCase],
+ repeats: int,
+ verifiers: Mapping[str, Verifier] | None,
+ pass_threshold: float,
+) -> tuple[list[EvalCase], dict[str, Verifier], list[tuple[int, int, EvalCase]]]:
+ if not isinstance(repeats, int) or isinstance(repeats, bool) or repeats < 1:
+ raise ValueError("repeats must be an integer >= 1")
+ if not math.isfinite(pass_threshold):
+ raise ValueError("pass_threshold must be finite")
+ verifier_map = dict(verifiers or {})
+ for name, verifier in verifier_map.items():
+ if not isinstance(name, str) or not name.strip():
+ raise ValueError("verifier names must be non-empty strings")
+ if name == "score":
+ raise ValueError("verifier name 'score' is reserved for the legacy scorer")
+ if not callable(verifier):
+ raise TypeError(f"verifier {name!r} must be callable")
+ prepared = [_coerce_case(case) for case in cases]
+ work = [
+ (case_index, sample_index, case)
+ for case_index, case in enumerate(prepared)
+ for sample_index in range(repeats)
+ ]
+ return prepared, verifier_map, work
+
+
+def _run_case(
+ build_agent: AgentFactory,
+ item: tuple[int, int, EvalCase],
+ scorer: Scorer | None,
+ verifiers: Mapping[str, Verifier],
+) -> EvalResult:
+ case_index, sample_index, case = item
started = time.perf_counter()
+ agent: Agent | None = None
try:
agent = _build_agent(build_agent)
output = agent.run(case.input)
- score = _score(output, case.expected, scorer)
- return EvalResult(
- case=case,
- output=output,
- score=score,
- duration_ms=round((time.perf_counter() - started) * 1000, 3),
- trace=agent.last_trace,
- )
- except Exception as exc: # noqa: BLE001 - one failed case must not abort a dataset
- return EvalResult(
- case=case,
- error=f"{type(exc).__name__}: {exc}",
- duration_ms=round((time.perf_counter() - started) * 1000, 3),
- )
+ except Exception as exc: # noqa: BLE001 - one sample must not abort a dataset
+ return _execution_failure(case, case_index, sample_index, started, agent, exc, verifiers)
+ return _successful_result(
+ case,
+ case_index,
+ sample_index,
+ started,
+ agent,
+ output,
+ scorer,
+ verifiers,
+ )
async def _arun_case(
- build_agent: AgentFactory, case: EvalCase, scorer: Scorer | None
+ build_agent: AgentFactory,
+ item: tuple[int, int, EvalCase],
+ scorer: Scorer | None,
+ verifiers: Mapping[str, Verifier],
) -> EvalResult:
+ case_index, sample_index, case = item
started = time.perf_counter()
+ agent: Agent | None = None
try:
agent = _build_agent(build_agent)
output = await agent.arun(case.input)
- score = _score(output, case.expected, scorer)
- return EvalResult(
- case=case,
- output=output,
+ except Exception as exc: # noqa: BLE001 - one sample must not abort a dataset
+ return _execution_failure(case, case_index, sample_index, started, agent, exc, verifiers)
+ return _successful_result(
+ case,
+ case_index,
+ sample_index,
+ started,
+ agent,
+ output,
+ scorer,
+ verifiers,
+ )
+
+
+def _successful_result(
+ case: EvalCase,
+ case_index: int,
+ sample_index: int,
+ started: float,
+ agent: Agent,
+ output: str,
+ scorer: Scorer | None,
+ verifiers: Mapping[str, Verifier],
+) -> EvalResult:
+ trace = agent.last_trace
+ context = EvalContext(
+ case=case,
+ agent=agent,
+ output=output,
+ trace=trace,
+ case_index=case_index,
+ sample_index=sample_index,
+ )
+ score_metric = _score_metric(output, case.expected, scorer)
+ metrics = {"score": score_metric}
+ for name, verifier in verifiers.items():
+ metrics[name] = _call_verifier(verifier, context)
+ return EvalResult(
+ case=case,
+ output=output,
+ score=score_metric.score,
+ duration_ms=_elapsed_ms(started),
+ trace=trace,
+ case_index=case_index,
+ sample_index=sample_index,
+ metrics=metrics,
+ **_trace_stats(trace),
+ )
+
+
+def _execution_failure(
+ case: EvalCase,
+ case_index: int,
+ sample_index: int,
+ started: float,
+ agent: Agent | None,
+ exc: Exception,
+ verifiers: Mapping[str, Verifier],
+) -> EvalResult:
+ trace = agent.last_trace if agent is not None else None
+ metric_error = MetricResult(error="evaluation skipped: execution failed")
+ metrics = {name: metric_error for name in ("score", *verifiers.keys())}
+ return EvalResult(
+ case=case,
+ error=f"{type(exc).__name__}: {exc}",
+ duration_ms=_elapsed_ms(started),
+ trace=trace,
+ case_index=case_index,
+ sample_index=sample_index,
+ metrics=metrics,
+ **_trace_stats(trace),
+ )
+
+
+def _score_metric(output: str, expected: str | None, scorer: Scorer | None) -> MetricResult:
+ if expected is None:
+ return MetricResult(reason="case has no expected answer")
+ try:
+ value = scorer(output, expected) if scorer else output.strip() == expected.strip()
+ return _normalize_metric(value, coerce=True)
+ except Exception as exc: # noqa: BLE001 - isolate callback failures
+ return MetricResult(error=f"{type(exc).__name__}: {exc}")
+
+
+def _call_verifier(verifier: Verifier, context: EvalContext) -> MetricResult:
+ try:
+ return _normalize_metric(verifier(context), coerce=False)
+ except Exception as exc: # noqa: BLE001 - isolate callback failures
+ return MetricResult(error=f"{type(exc).__name__}: {exc}")
+
+
+def _normalize_metric(value: VerifierValue, *, coerce: bool) -> MetricResult:
+ if isinstance(value, MetricResult):
+ if value.error is not None and value.score is not None:
+ raise ValueError("MetricResult cannot contain both score and error")
+ if value.score is None:
+ return value
+ score = float(value.score)
+ if not math.isfinite(score):
+ raise ValueError("metric score must be finite")
+ return MetricResult(
score=score,
- duration_ms=round((time.perf_counter() - started) * 1000, 3),
- trace=agent.last_trace,
- )
- except Exception as exc: # noqa: BLE001 - one failed case must not abort a dataset
- return EvalResult(
- case=case,
- error=f"{type(exc).__name__}: {exc}",
- duration_ms=round((time.perf_counter() - started) * 1000, 3),
+ reason=value.reason,
+ details=value.details,
+ error=value.error,
)
+ if value is None:
+ return MetricResult()
+ if isinstance(value, bool):
+ return MetricResult(score=1.0 if value else 0.0)
+ if not coerce and not isinstance(value, (int, float)):
+ raise TypeError("verifier must return bool, float, MetricResult, or None")
+ score = float(value)
+ if not math.isfinite(score):
+ raise ValueError("metric score must be finite")
+ return MetricResult(score=score)
+
+
+def _build_report(
+ results: list[EvalResult],
+ case_count: int,
+ repeats: int,
+ pass_threshold: float,
+ verifiers: Mapping[str, Verifier],
+) -> EvalReport:
+ return EvalReport(
+ results=results,
+ pass_threshold=pass_threshold,
+ repeats=repeats,
+ case_count=case_count,
+ metric_names=("score", *verifiers.keys()),
+ )
+
+
+def _summarize_metric(
+ results: list[EvalResult], name: str, pass_threshold: float
+) -> dict[str, Any]:
+ values = [result.metrics.get(name) for result in results]
+ scores = [metric.score for metric in values if metric and metric.score is not None]
+ errors = sum(
+ result.error is not None or (metric is not None and metric.error is not None)
+ for result, metric in zip(results, values)
+ )
+ na = sum(
+ result.error is None and (metric is None or (metric.score is None and metric.error is None))
+ for result, metric in zip(results, values)
+ )
+ passed = sum(score >= pass_threshold for score in scores)
+ has_outcome = bool(scores) or errors > 0
+ return {
+ "samples": len(results),
+ "scored": len(scores),
+ "na": na,
+ "errors": errors,
+ "passed": passed,
+ "pass_rate": passed / len(results) if results and has_outcome else None,
+ "mean_score": sum(scores) / len(scores) if scores else None,
+ }
+
+
+def _summarize_run_stats(results: list[EvalResult]) -> dict[str, Any]:
+ summary: dict[str, Any] = {}
+ for field_name, label in (
+ ("rounds", "rounds"),
+ ("tool_calls", "tool_calls"),
+ ("total_tokens", "total_tokens"),
+ ("cost_usd", "cost_usd"),
+ ):
+ values = [
+ float(value) for result in results if (value := getattr(result, field_name)) is not None
+ ]
+ summary[f"mean_{label}"] = sum(values) / len(values) if values else None
+ summary[f"{label}_coverage"] = len(values) / len(results) if results else None
+ return summary
+
+
+def _trace_stats(trace: AgentTrace | None) -> dict[str, Any]:
+ if trace is None:
+ return {
+ "runtime_status": None,
+ "rounds": None,
+ "tool_calls": None,
+ "total_tokens": None,
+ "cost_usd": None,
+ }
+ return {
+ "runtime_status": trace.status,
+ "rounds": len(trace.model_calls) if trace.trace_version >= 2 else None,
+ "tool_calls": len(trace.tool_calls) if trace.trace_version >= 2 else None,
+ "total_tokens": _total_tokens(trace.usage),
+ "cost_usd": _cost_usd(trace.usage),
+ }
+
+
+def _total_tokens(usage: Mapping[str, int | float]) -> float | None:
+ for key in ("total_tokens", "total_token_count"):
+ if key in usage:
+ return float(usage[key])
+ for input_key, output_key in (
+ ("prompt_tokens", "completion_tokens"),
+ ("input_tokens", "output_tokens"),
+ ("prompt_eval_count", "eval_count"),
+ ):
+ if input_key in usage and output_key in usage:
+ return float(usage[input_key] + usage[output_key])
+ return None
+
+
+def _cost_usd(usage: Mapping[str, int | float]) -> float | None:
+ for key in ("total_cost_usd", "cost_usd"):
+ if key in usage:
+ return float(usage[key])
+ return None
+
+
+def _elapsed_ms(started: float) -> float:
+ return round((time.perf_counter() - started) * 1000, 3)
def _build_agent(factory: AgentFactory) -> Agent:
@@ -220,10 +577,13 @@ def _coerce_case(case: str | EvalCase) -> EvalCase:
raise TypeError(f"Expected str or EvalCase, got {type(case).__name__}")
-def _score(output: str, expected: str | None, scorer: Scorer | None) -> float | None:
- if expected is None:
- return None
- value = scorer(output, expected) if scorer else output.strip() == expected.strip()
- if isinstance(value, bool):
- return 1.0 if value else 0.0
- return float(value)
+def _json_value(value: Any) -> Any:
+ if value is None or isinstance(value, (str, bool, int)):
+ return value
+ if isinstance(value, float):
+ return value if math.isfinite(value) else repr(value)
+ if isinstance(value, Mapping):
+ return {str(key): _json_value(item) for key, item in value.items()}
+ if isinstance(value, (list, tuple, set)):
+ return [_json_value(item) for item in value]
+ return repr(value)
diff --git a/src/agentmold/visual/agent_config.py b/src/agentmold/visual/agent_config.py
index a7015d5..aa3a12d 100644
--- a/src/agentmold/visual/agent_config.py
+++ b/src/agentmold/visual/agent_config.py
@@ -1,4 +1,4 @@
-"""Agent construction, mode presets, and tool loading for the visual lab.
+"""Agent construction and tool loading for the visual lab.
Streamlit is imported lazily only inside ``visual_approval_gate`` so that
importing this module never hard-fails when the ``visual`` extra is absent.
@@ -21,10 +21,8 @@
__all__ = [
"AUDIT_LOG_PATH",
"CONNECTION_DEFAULTS",
- "AGENT_MODE_PRESETS",
"agent_file_from_argv",
"code_agent_signature",
- "resolve_mode",
"build_agent",
"bind_visual_tools",
"visual_approval_gate",
@@ -47,27 +45,6 @@
AUDIT_LOG_PATH = Path(".agentmold/audit.jsonl")
-# Agent mode presets. Each maps a learner-friendly label to the safety knobs
-# it controls. "Custom" leaves the individual toggles as the source of truth.
-AGENT_MODE_PRESETS: dict[str, dict[str, Any] | None] = {
- "标准模式": {
- "loop_detection_threshold": 3,
- "require_approval": False,
- "audit_log": False,
- },
- "安全模式": {
- "loop_detection_threshold": 3,
- "require_approval": True,
- "audit_log": True,
- },
- "调试模式": {
- "loop_detection_threshold": 3,
- "require_approval": False,
- "audit_log": True,
- },
- "自定义": None,
-}
-
def agent_file_from_argv(argv: list[str] | None = None) -> Path | None:
"""Read the optional ``--agent-file`` argument passed after Streamlit's ``--``."""
@@ -92,30 +69,6 @@ def code_agent_signature(path: Path) -> tuple[str, int | None, int | None]:
return str(path), modified, size
-def resolve_mode(
- mode: str,
- loop_detection_threshold: int | None,
- require_approval: bool,
- audit_log: bool,
- log_level: str | None = None,
-) -> dict[str, Any]:
- """Return the effective safety knobs, applying a preset when not custom.
-
- ``log_level`` remains accepted for callers generated by older EasyAgent
- versions, but the visual lab intentionally ignores console logging and uses
- its timeline, execution map, and trace views for observability.
- """
- del log_level
- preset = AGENT_MODE_PRESETS.get(mode)
- if preset is not None:
- return dict(preset)
- return {
- "loop_detection_threshold": loop_detection_threshold,
- "require_approval": require_approval,
- "audit_log": audit_log,
- }
-
-
def bind_visual_tools(
selected_tools: list[str],
available_tools: dict[str, Tool],
@@ -238,7 +191,6 @@ def agent_signature(
max_iterations: int,
tool_signature: tuple[tuple[str, str | None], ...] = (),
*,
- mode: str = "标准模式",
loop_detection_threshold: int | None = 3,
require_approval: bool = False,
audit_log: bool = False,
@@ -258,7 +210,6 @@ def agent_signature(
tuple(sorted(selected_tools)),
max_iterations,
tuple(tool_signature),
- mode,
loop_detection_threshold,
require_approval,
audit_log,
diff --git a/src/agentmold/visual/app.py b/src/agentmold/visual/app.py
index eded2a1..98cf50d 100644
--- a/src/agentmold/visual/app.py
+++ b/src/agentmold/visual/app.py
@@ -14,40 +14,62 @@
import hashlib
import json
import time
+from pathlib import Path
from typing import TYPE_CHECKING, Any, Literal
if TYPE_CHECKING:
from agentmold import Tool
from agentmold.visual.agent_config import (
- AGENT_MODE_PRESETS as _AGENT_MODE_PRESETS,
+ AUDIT_LOG_PATH as _AUDIT_LOG_PATH,
)
from agentmold.visual.agent_config import (
- AUDIT_LOG_PATH as _AUDIT_LOG_PATH,
+ CONNECTION_DEFAULTS as _CONNECTION_DEFAULTS,
)
-from agentmold.visual.architecture import (
- ARCHITECTURE_PRESETS as _ARCHITECTURE_PRESETS,
+from agentmold.visual.agent_config import (
+ agent_file_from_argv as _agent_file_from_argv,
+)
+from agentmold.visual.agent_config import (
+ agent_signature as _agent_signature,
+)
+from agentmold.visual.agent_config import (
+ build_agent as _build_agent,
+)
+from agentmold.visual.agent_config import (
+ code_agent_signature as _code_agent_signature,
+)
+from agentmold.visual.agent_config import (
+ llm_config_from_ui as _llm_config_from_ui,
+)
+from agentmold.visual.agent_config import (
+ load_mcp_visual_tools as _load_mcp_visual_tools,
+)
+from agentmold.visual.agent_config import (
+ load_visual_tools as _load_visual_tools,
+)
+from agentmold.visual.agent_config import (
+ tool_widget_key as _tool_widget_key,
)
from agentmold.visual.architecture import (
- TOOL_CALLING_PRESETS as _TOOL_CALLING_PRESETS,
+ ARCHITECTURE_PRESETS as _ARCHITECTURE_PRESETS,
)
from agentmold.visual.architecture import (
- architecture_code as _architecture_code,
+ INTENT_PRESETS as _INTENT_PRESETS,
)
from agentmold.visual.architecture import (
- architecture_description as _architecture_description,
+ RETRIEVAL_PRESETS as _RETRIEVAL_PRESETS,
)
from agentmold.visual.architecture import (
- architecture_diagram_html as _architecture_diagram_html,
+ TOOL_CALLING_PRESETS as _TOOL_CALLING_PRESETS,
)
from agentmold.visual.architecture import (
- tool_calling_description as _tool_calling_description,
+ architecture_code as _architecture_code,
)
from agentmold.visual.architecture import (
- tool_calling_diagram_html as _tool_calling_diagram_html,
+ architecture_description as _architecture_description,
)
from agentmold.visual.architecture import (
- INTENT_PRESETS as _INTENT_PRESETS,
+ architecture_diagram_html as _architecture_diagram_html,
)
from agentmold.visual.architecture import (
intent_code as _intent_code,
@@ -58,9 +80,6 @@
from agentmold.visual.architecture import (
intent_diagram_html as _intent_diagram_html,
)
-from agentmold.visual.architecture import (
- RETRIEVAL_PRESETS as _RETRIEVAL_PRESETS,
-)
from agentmold.visual.architecture import (
retrieval_code as _retrieval_code,
)
@@ -70,35 +89,11 @@
from agentmold.visual.architecture import (
retrieval_diagram_html as _retrieval_diagram_html,
)
-from agentmold.visual.agent_config import (
- CONNECTION_DEFAULTS as _CONNECTION_DEFAULTS,
-)
-from agentmold.visual.agent_config import (
- agent_file_from_argv as _agent_file_from_argv,
-)
-from agentmold.visual.agent_config import (
- agent_signature as _agent_signature,
-)
-from agentmold.visual.agent_config import (
- build_agent as _build_agent,
-)
-from agentmold.visual.agent_config import (
- code_agent_signature as _code_agent_signature,
-)
-from agentmold.visual.agent_config import (
- llm_config_from_ui as _llm_config_from_ui,
-)
-from agentmold.visual.agent_config import (
- load_mcp_visual_tools as _load_mcp_visual_tools,
-)
-from agentmold.visual.agent_config import (
- load_visual_tools as _load_visual_tools,
-)
-from agentmold.visual.agent_config import (
- resolve_mode as _resolve_mode,
+from agentmold.visual.architecture import (
+ tool_calling_description as _tool_calling_description,
)
-from agentmold.visual.agent_config import (
- tool_widget_key as _tool_widget_key,
+from agentmold.visual.architecture import (
+ tool_calling_diagram_html as _tool_calling_diagram_html,
)
from agentmold.visual.codegen import api_key_environment, generate_agent_python
from agentmold.visual.renderers import (
@@ -120,7 +115,7 @@
timeline_html as _timeline_html,
)
from agentmold.visual.renderers import (
- trace_compare_html as _trace_compare_html,
+ trace_breadcrumb_html as _trace_breadcrumb_html,
)
from agentmold.visual.renderers import (
trace_metrics_html as _trace_metrics_html,
@@ -146,22 +141,27 @@
)
from agentmold.visual.traces import (
DEFAULT_VISUAL_TRACE_LOG,
+ build_trace_forest,
diagnose_trace_run,
find_trace_run,
load_trace_runs,
merge_trace_runs,
parse_trace_jsonl,
summarize_trace_run,
+ trace_family_from_forest,
+ trace_family_order,
trace_label,
traces_to_jsonl,
)
-def _render_trace_lab(
- st: Any,
-) -> None:
+def _render_trace_lab(st: Any, *, standalone: bool = False) -> None:
"""Render trace import, scrubbed replay, export, and two-run comparison."""
- with st.expander("TRACE LAB · 回放与对比", expanded=False):
+ container = st.container() if standalone else st.expander("TRACE LAB · 回放与对比")
+ with container:
+ if standalone:
+ st.markdown("## 运行回放")
+ st.caption("这里只展示已经发生并持久化的执行事实;概念架构节点不会出现在 Trace 中。")
session_runs = st.session_state.get("trace_runs", [])
try:
logged_runs = load_trace_runs()
@@ -184,9 +184,10 @@ def _render_trace_lab(
st.error(f"{uploaded_file.name}: {exc}")
runs = merge_trace_runs(logged_runs, session_runs, imported_runs)
+ forest = build_trace_forest(runs)
if runs:
export_col.download_button(
- "导出当前 Trace",
+ "导出全部 Trace",
data=traces_to_jsonl(runs),
file_name="easyagent-traces.jsonl",
mime="application/x-ndjson",
@@ -200,8 +201,20 @@ def _render_trace_lab(
st.markdown('暂无可回放 Trace。
', unsafe_allow_html=True)
return
- run_ids = [str(run["run_id"]) for run in runs]
- labels = {str(run["run_id"]): trace_label(run) for run in runs}
+ display_order = trace_family_order(forest)
+ run_ids = [run_id for run_id, _depth in display_order]
+ if not run_ids:
+ run_ids = [str(run["run_id"]) for run in runs]
+ depth_by_id = dict(display_order)
+ labels = {
+ str(run["run_id"]): (
+ f"{'└─ ' * depth_by_id.get(str(run['run_id']), 0)}{trace_label(run)}"
+ )
+ for run in runs
+ }
+ pending_jump = st.session_state.pop("ea_trace_jump_to", None)
+ if pending_jump in run_ids:
+ st.session_state.ea_replay_run = pending_jump
lookup_id = st.text_input(
"按日志 ID 查找",
placeholder="输入完整 run_id 或唯一前缀",
@@ -225,6 +238,53 @@ def _render_trace_lab(
)
replay = next(run for run in runs if run["run_id"] == replay_id)
summary = summarize_trace_run(replay)
+ all_runs = forest["all_runs"]
+ parent_run = all_runs.get(summary["parent_run_id"])
+ child_runs = forest["children"].get(replay_id, [])
+ parent_summary = summarize_trace_run(parent_run) if parent_run else None
+ child_summaries = [summarize_trace_run(child) for child in child_runs]
+ st.markdown(
+ _trace_breadcrumb_html(summary, parent_summary, child_summaries),
+ unsafe_allow_html=True,
+ )
+ family = trace_family_from_forest(forest, replay_id)
+ family_col, nav_col = st.columns([1, 1])
+ if len(family) > 1:
+ family_col.download_button(
+ "导出协作 Trace bundle",
+ data=traces_to_jsonl(family),
+ file_name=f"easyagent-family-{replay_id[:12]}.jsonl",
+ mime="application/x-ndjson",
+ use_container_width=True,
+ key=f"ea_export_family_{replay_id}",
+ )
+ else:
+ family_col.caption("该运行没有已加载的子运行。")
+ navigation_targets: list[tuple[str, str]] = []
+ if parent_run is not None:
+ navigation_targets.append((str(parent_run["run_id"]), "跳转父运行"))
+ navigation_targets.extend(
+ (str(child["run_id"]), f"子运行 · {str(child.get('agent_name') or 'Agent')}")
+ for child in child_runs
+ )
+ if navigation_targets:
+ target_ids = [target for target, _label in navigation_targets]
+ target_labels = dict(navigation_targets)
+ target = nav_col.selectbox(
+ "Family 导航",
+ options=target_ids,
+ format_func=lambda run_id: target_labels[run_id],
+ key=f"ea_family_nav_{replay_id}",
+ )
+ if nav_col.button(
+ "打开运行",
+ key=f"ea_family_open_{replay_id}",
+ use_container_width=True,
+ ):
+ st.session_state.ea_trace_jump_to = target
+ st.rerun()
+ else:
+ nav_col.caption("无父/子运行可跳转。")
st.markdown(_trace_metrics_html(summary), unsafe_allow_html=True)
if summary["error"]:
st.warning(diagnose_trace_run(replay))
@@ -282,41 +342,6 @@ def _render_trace_lab(
unsafe_allow_html=True,
)
- st.markdown("**COMPARE RUNS**")
- compare_key = "ea_compare_runs"
- option_signature = tuple(run_ids)
- if st.session_state.get("ea_compare_run_options") != option_signature:
- selected = [
- run_id for run_id in st.session_state.get(compare_key, []) if run_id in run_ids
- ]
- for run_id in reversed(run_ids):
- if len(selected) >= 2:
- break
- if run_id not in selected:
- selected.append(run_id)
- st.session_state[compare_key] = selected[:2] if len(run_ids) >= 2 else []
- st.session_state.ea_compare_run_options = option_signature
- compare_ids = st.multiselect(
- "选择两个运行",
- options=run_ids,
- format_func=lambda run_id: labels[run_id],
- max_selections=2,
- key=compare_key,
- )
- if len(compare_ids) == 2:
- compare_runs = [
- next(run for run in runs if run["run_id"] == run_id) for run_id in compare_ids
- ]
- st.markdown(
- _trace_compare_html(
- summarize_trace_run(compare_runs[0]),
- summarize_trace_run(compare_runs[1]),
- ),
- unsafe_allow_html=True,
- )
- else:
- st.caption("选择两个运行后,会并排显示提示词、模型、延迟、token、成本和工具调用。")
-
def _render_architecture_demo(st: Any) -> None:
"""Render an interactive architecture-pattern showcase with a flowchart.
@@ -331,6 +356,10 @@ def _render_architecture_demo(st: Any) -> None:
Injection (the legacy text-parsing approach).
"""
with st.expander("🧠 AGENT 架构演示", expanded=False):
+ st.caption(
+ "以下模式都是 Agent + @tool + 普通 Python 的组合;"
+ "没有内置编排器、工作流引擎或 Coordinator 类。"
+ )
arch_options = list(_ARCHITECTURE_PRESETS.keys())
selected = st.selectbox(
"选择架构模式",
@@ -362,7 +391,10 @@ def _render_architecture_demo(st: Any) -> None:
options=tc_options,
index=0,
key="ea_tool_calling_mode_demo",
- help="对比 Function Calling(原生)与 Prompt-based Tool Calling(提示词工具调用)的区别。",
+ help=(
+ "对比 Function Calling(原生)与 Prompt-based Tool Calling"
+ "(提示词工具调用)的区别。"
+ ),
)
tc_desc = _tool_calling_description(tc_selected)
if tc_desc:
@@ -492,8 +524,7 @@ def _render_code_export(
blocked = [
tool
for tool in selected_tools
- if tool in _NON_EXPORTABLE
- or origins.get(tool, "").startswith(("上传", "MCP"))
+ if tool in _NON_EXPORTABLE or origins.get(tool, "").startswith(("上传", "MCP"))
]
if blocked:
st.warning(
@@ -554,11 +585,8 @@ def _render_learning_labs(
audit_log: bool,
tool_origins: dict[str, str] | None = None,
) -> None:
- """Render concept, replay, and export labs independently of live Agent state."""
+ """Render ReAct code export independently of live Agent state."""
st.divider()
- _render_architecture_demo(st)
- _render_engineering_demo(st)
- _render_trace_lab(st)
if agent_file is None and not model_missing:
_render_code_export(
st,
@@ -572,14 +600,90 @@ def _render_learning_labs(
audit_log=audit_log,
rag_text=st.session_state.get("ea_rag_text", ""),
tool_origins=tool_origins,
- tool_description_overrides=st.session_state.get(
- "ea_tool_description_overrides", {}
- ),
+ tool_description_overrides=st.session_state.get("ea_tool_description_overrides", {}),
)
elif agent_file is None:
st.info("填写模型 ID 后可生成并导出 Agent。")
+_ARCHITECTURE_NAV = {
+ "react": "ReAct",
+ "plan_execute": "Plan-and-Execute",
+ "reflection": "Reflection",
+ "multi_agent": "Multi-Agent",
+ "routing": "Routing",
+}
+
+
+def _render_top_navigation(st: Any) -> tuple[str, str]:
+ """Render architecture-first navigation with Streamlit 1.30 fallback."""
+ current_view = str(st.session_state.get("ea_visual_view", "architecture"))
+ current_architecture = str(st.session_state.get("ea_architecture_mode", "react"))
+ if current_architecture not in _ARCHITECTURE_NAV:
+ current_architecture = "react"
+ labels = list(_ARCHITECTURE_NAV.values())
+ reverse = {label: key for key, label in _ARCHITECTURE_NAV.items()}
+ selected_label = _ARCHITECTURE_NAV[current_architecture]
+ segmented = getattr(st, "segmented_control", None)
+ if callable(segmented):
+ selection = segmented(
+ "Agent 架构",
+ options=labels,
+ default=selected_label,
+ key="ea_architecture_nav",
+ selection_mode="single",
+ label_visibility="collapsed",
+ )
+ else:
+ selection = st.radio(
+ "Agent 架构",
+ options=labels,
+ index=labels.index(selected_label),
+ key="ea_architecture_nav",
+ horizontal=True,
+ label_visibility="collapsed",
+ )
+ architecture_id = reverse.get(str(selection), current_architecture)
+ if architecture_id != current_architecture:
+ st.session_state.ea_architecture_mode = architecture_id
+ st.session_state.ea_visual_view = "architecture"
+ current_view = "architecture"
+ else:
+ st.session_state.ea_architecture_mode = architecture_id
+ architecture_col, replay_col, eval_col, context_col = st.columns([1, 1, 1, 3])
+ if architecture_col.button(
+ "架构实验",
+ use_container_width=True,
+ type="primary" if current_view == "architecture" else "secondary",
+ key="ea_nav_architecture",
+ ):
+ st.session_state.ea_visual_view = "architecture"
+ st.rerun()
+ if replay_col.button(
+ "运行回放",
+ use_container_width=True,
+ type="primary" if current_view == "trace" else "secondary",
+ key="ea_nav_trace",
+ ):
+ st.session_state.ea_visual_view = "trace"
+ st.rerun()
+ if eval_col.button(
+ "对比与评测",
+ use_container_width=True,
+ type="primary" if current_view == "evaluation" else "secondary",
+ key="ea_nav_evaluation",
+ ):
+ st.session_state.ea_visual_view = "evaluation"
+ st.rerun()
+ context_messages = {
+ "architecture": "运行五种架构实验,并区分概念示意与真实 Trace。",
+ "trace": "查看一次运行的时间线、配置与父子 Agent family。",
+ "evaluation": "比较 2-4 个 Agent 运行,或执行同一 Agent 的批量回归。",
+ }
+ context_col.caption(context_messages.get(current_view, context_messages["architecture"]))
+ return current_view, architecture_id
+
+
def _profile_setting(
profile: dict[str, Any],
key: str,
@@ -626,9 +730,7 @@ def _tool_group_summary(
available_tools: dict[str, Tool],
) -> str:
selected_count = sum(name in selected for name in tool_names)
- destructive = sum(
- bool(getattr(available_tools[name], "confirm", False)) for name in tool_names
- )
+ destructive = sum(bool(getattr(available_tools[name], "confirm", False)) for name in tool_names)
suffix = f" · ⚠ {destructive}" if destructive else ""
return f"{group} · {selected_count}/{len(tool_names)} 已选{suffix}"
@@ -673,6 +775,20 @@ def _run_app() -> None:
""",
unsafe_allow_html=True,
)
+ visual_view, architecture_mode = _render_top_navigation(st)
+ if visual_view == "trace":
+ _render_trace_lab(st, standalone=True)
+ return
+ if visual_view == "evaluation":
+ from agentmold.visual.evaluation_view import render_evaluation_view
+
+ render_evaluation_view(st)
+ return
+ if architecture_mode != "react":
+ from agentmold.visual.teaching_view import render_teaching_view
+
+ render_teaching_view(st, architecture_mode)
+ return
# ------------------------------------------------------------------
# Sidebar: either load a code-defined agent or configure a small demo.
@@ -695,6 +811,10 @@ def _run_app() -> None:
selected_tools: list[str]
tool_signature: tuple[tuple[str, str | None], ...]
available_tools: dict[str, Tool]
+ tool_origins: dict[str, str]
+ loop_detection_threshold = 3
+ require_approval = False
+ audit_log = False
if agent_file is not None:
st.sidebar.header("📄 代码 Agent")
st.sidebar.code(str(agent_file), language="text")
@@ -733,7 +853,6 @@ def _run_app() -> None:
st.session_state.ea_restored_tool_names = saved_agent_config.get(
"selected_tools", ["calculate"]
)
- st.session_state.ea_agent_mode = saved_agent_config.get("agent_mode", "标准模式")
st.session_state.ea_loop_detection_threshold = saved_agent_config.get(
"loop_detection_threshold", 3
)
@@ -750,52 +869,18 @@ def _run_app() -> None:
agent_notice = st.session_state.pop("ea_agent_notice", None)
if agent_notice:
st.toast(agent_notice, icon="🔄")
- st.sidebar.subheader("🎯 运行模式")
- agent_mode = st.sidebar.selectbox(
- "模式预设",
- options=list(_AGENT_MODE_PRESETS.keys()),
- key="ea_agent_mode",
- help="预设一键配置安全门:安全模式开启确认门与审计;调试模式开启审计与详细日志。",
- )
- mode_is_custom = agent_mode == "自定义"
- _mode_descriptions = {
- "标准模式": (
- "循环检测开(阈值 3)· 无确认门 · 无审计。\n"
- "适合快速体验 Agent 基本循环,无额外安全防护。"
- ),
- "安全模式": (
- "循环检测开 · **破坏性工具需确认** · 审计日志开。\n"
- "破坏性工具(如 write_file)执行前会弹确认门,每次工具调用写入审计日志。"
- ),
- "调试模式": (
- "循环检测开 · 无确认门 · 审计日志开。\n"
- "审计日志记录每次工具调用;时间线和执行地图显示每一步思考/动作/观察。"
- ),
- "自定义": "手动调整下方安全门开关,自由组合防护策略。",
- }
- st.sidebar.caption(_mode_descriptions.get(agent_mode, ""))
- effective = _resolve_mode(
- agent_mode,
- st.session_state.get("ea_loop_detection_threshold", 3),
- st.session_state.get("ea_require_approval", False),
- st.session_state.get("ea_audit_log", False),
- )
- if not mode_is_custom:
- st.session_state.ea_loop_detection_threshold = effective["loop_detection_threshold"]
- st.session_state.ea_require_approval = effective["require_approval"]
- st.session_state.ea_audit_log = effective["audit_log"]
+ st.sidebar.caption("主要配置")
+ name = st.sidebar.text_input("Agent 名称", key="ea_agent_name")
with st.sidebar.expander(
- "运行与安全 · "
- f"loop={effective['loop_detection_threshold']} · "
- f"HITL{'开' if effective['require_approval'] else '关'} · "
- f"audit{'开' if effective['audit_log'] else '关'}",
- expanded=mode_is_custom,
+ "运行限制与安全(高级)",
+ expanded=False,
):
max_iterations = st.slider(
"最大迭代次数",
min_value=1,
max_value=20,
key="ea_max_iterations",
+ help="一次运行允许的最大模型轮次。",
)
loop_detection_threshold = st.number_input(
"重复调用检测阈值",
@@ -803,25 +888,28 @@ def _run_app() -> None:
max_value=20,
step=1,
key="ea_loop_detection_threshold",
- disabled=not mode_is_custom,
- help="同一工具相同参数连续调用 N 次即判定为死循环;设为 1 也可。",
+ help="同一工具与参数连续调用 N 次时停止,避免无效循环。",
)
require_approval = st.checkbox(
- "破坏性工具需确认(HITL)",
+ "拒绝需要确认的工具",
key="ea_require_approval",
- disabled=not mode_is_custom,
- help="开启后,@tool(confirm=True) 的工具执行前会触发确认门。",
+ help=(
+ "开启后,@tool(confirm=True) 和已标记的 MCP 工具会记录确认事件并拒绝执行。"
+ "当前 Visual Lab 不提供运行中批准。"
+ ),
)
audit_log = st.checkbox(
"记录工具调用审计日志",
key="ea_audit_log",
- disabled=not mode_is_custom,
- help="每次工具调用写入 .agentmold/audit.jsonl,可回放。",
+ help="每次工具调用写入 .agentmold/audit.jsonl。",
+ )
+ st.caption(
+ f"当前:loop={int(loop_detection_threshold)} · "
+ f"deny={'开' if require_approval else '关'} · "
+ f"audit={'开' if audit_log else '关'}"
)
- name = st.sidebar.text_input("Agent 名称", key="ea_agent_name")
with st.sidebar.expander(
- "Agent 指令 · "
- f"{len(st.session_state.get('ea_agent_instructions', ''))} 字符",
+ f"Agent 指令 · {len(st.session_state.get('ea_agent_instructions', ''))} 字符",
expanded=st.session_state.get("agent") is None,
):
instructions = st.text_area(
@@ -870,9 +958,8 @@ def _run_app() -> None:
st.session_state[f"ea_timeout_{widget_suffix}"] = profile_defaults["timeout"]
st.session_state[f"ea_max_tokens_{widget_suffix}"] = profile_defaults["max_tokens"]
st.session_state.ea_active_profile = profile_key
- interface_expanded = (
- connection_type == "自定义提供商"
- or (connection_type != "Mock(离线)" and not saved_profile)
+ interface_expanded = connection_type == "自定义提供商" or (
+ connection_type != "Mock(离线)" and not saved_profile
)
with st.sidebar.expander(
f"接口参数 · {connection_type} / {profile_defaults['model'] or '未设置模型'}",
@@ -1251,13 +1338,10 @@ def _run_app() -> None:
current_selected = {
tool_name
for tool_name in available_tools
- if st.session_state.get(
- _tool_widget_key(tool_name), tool_name in restored_tool_names
- )
+ if st.session_state.get(_tool_widget_key(tool_name), tool_name in restored_tool_names)
}
destructive_selected = sum(
- bool(getattr(available_tools[name], "confirm", False))
- for name in current_selected
+ bool(getattr(available_tools[name], "confirm", False)) for name in current_selected
)
summary = f"已选 {len(current_selected)}/{len(available_tools)}"
if destructive_selected:
@@ -1284,7 +1368,7 @@ def _run_app() -> None:
)
help_text = effective_description or "未提供工具说明"
if getattr(visual_tool, "confirm", False):
- help_text += "(标记为破坏性:安全模式下执行前需确认)"
+ help_text += "(需要确认;开启高级拒绝开关后不会执行)"
if st.checkbox(label, key=widget_key, help=help_text):
selected_tools.append(tool_name)
@@ -1356,7 +1440,6 @@ def _run_app() -> None:
"custom_tool_files": custom_tool_files,
"mcp_url": st.session_state.get("ea_mcp_url", ""),
"rag_text": st.session_state.get("ea_rag_text", ""),
- "agent_mode": agent_mode,
"loop_detection_threshold": int(loop_detection_threshold),
"require_approval": bool(require_approval),
"audit_log": bool(audit_log),
@@ -1400,7 +1483,6 @@ def _run_app() -> None:
"ea_max_iterations",
"ea_restored_tool_names",
"ea_visual_config_initialized",
- "ea_agent_mode",
"ea_loop_detection_threshold",
"ea_require_approval",
"ea_audit_log",
@@ -1448,7 +1530,6 @@ def _run_app() -> None:
selected_tools,
max_iterations,
tool_signature,
- mode=agent_mode,
loop_detection_threshold=loop_detection_threshold,
require_approval=require_approval,
audit_log=audit_log,
@@ -1539,8 +1620,11 @@ def _run_app() -> None:
tool_origins=tool_origins,
)
st.session_state.agent_signature = current_sig
- # Keep existing conversation history - only the agent changed.
agent = st.session_state.agent
+ st.session_state.messages = []
+ st.session_state.last_steps = []
+ st.session_state.last_user_input = None
+ st.session_state.run_meta = _initial_run_meta()
auto_rebuilt = True
except Exception as exc: # noqa: BLE001
st.session_state.agent = None
@@ -1590,10 +1674,9 @@ def _run_app() -> None:
st.markdown(f"- **LLM:** `{agent.llm.model}`")
st.markdown(f"- **工具:** {tool_list}")
st.markdown(f"- **最大迭代:** {agent.max_iterations}")
- st.markdown(f"- **模式:** {agent_mode}")
gate_summary = []
if require_approval:
- gate_summary.append("✅ 确认门")
+ gate_summary.append("需确认工具=拒绝")
if audit_log:
gate_summary.append("✅ 审计日志")
gate_summary.append(f"循环检测={loop_detection_threshold}")
@@ -1749,13 +1832,12 @@ def _run_app() -> None:
run_meta["phase"] = "确认门"
try:
st.warning(
- f"⚠ **确认门 (HITL):** 破坏性工具 "
- f"`{step['name']}({step['arguments']})` "
- "已被安全模式拦截。"
+ f"⚠ **工具执行已拒绝:** 需要确认的工具 "
+ f"`{step['name']}({step['arguments']})` 未执行。"
)
st.caption(
- "这是人机协作(HITL)安全门教学事件:当前同步运行默认拒绝,"
- "以避免脚本重跑时产生未绑定到本次调用的批准。"
+ "Visual Lab 当前不提供运行中批准;"
+ "该确认请求和拒绝结果已写入 Trace。"
)
except OSError:
pass
diff --git a/src/agentmold/visual/architecture.py b/src/agentmold/visual/architecture.py
index 32cbfb8..4ee3eb6 100644
--- a/src/agentmold/visual/architecture.py
+++ b/src/agentmold/visual/architecture.py
@@ -77,15 +77,18 @@ def _edge(
ARCHITECTURE_PRESETS: dict[str, dict[str, Any]] = {
"ReAct(推理-行动)": {
+ "architecture_id": "react",
+ "sample_input": "RAG 如何减少模型幻觉?",
+ "runner_key": "run_react_experiment",
+ "run_status": "shipped",
"title": "ReAct: Reason + Act",
"summary": (
- "Agent 在每一轮先思考(Thought)、再行动(Action)、观察结果"
- "(Observation),循环直到给出最终回答。EasyAgent 的默认执行循环"
- "就是 ReAct。"
+ "Agent 在每一轮根据公开上下文选择行动,观察工具结果后继续,直到给出"
+ "最终回答。EasyAgent 记录模型轮次和工具事件,但不展示隐藏思维链。"
),
"nodes": [
_node("user", "user", "用户问题"),
- _node("thought", "llm", "Thought · 推理", detail="我需要什么信息?"),
+ _node("thought", "llm", "模型轮次 · 决策", detail="回答或选择工具"),
_node("action", "tool", "Action · 调用工具", detail="retrieve / calculate …"),
_node("observation", "memory", "Observation · 结果", detail="工具返回写入记忆"),
_node("answer", "answer", "最终回答"),
@@ -97,27 +100,22 @@ def _edge(
_edge("observation", "thought", label="继续推理", style="loop"),
_edge("thought", "answer", label="无需更多工具"),
],
- "code": """from agentmold import Agent, tool
+ "code": """from agentmold.visual.teaching import run_react_experiment
-@tool
-def retrieve(query: str) -> str:
- '''检索知识库。'''
- ...
-
-agent = Agent(
- name="ReActAgent",
- instructions="先思考需要什么信息,再调用工具,最后给出回答。",
- tools=[retrieve],
- llm="mock",
-)
-answer = agent("道与术的本质是什么?")
+experiment = run_react_experiment("RAG 如何减少模型幻觉?")
+print(experiment.output)
""",
},
"Plan-and-Execute(计划-执行)": {
+ "architecture_id": "plan_execute",
+ "sample_input": "为一个离线知识助手制定三步实施方案",
+ "runner_key": "run_plan_execute_experiment",
+ "run_status": "shipped",
"title": "Plan-and-Execute",
"summary": (
"先用一个 Planner Agent 把任务拆成步骤清单,再逐步执行每个步骤。"
- "适合多步骤、需要前期规划的任务。"
+ "适合多步骤、需要前期规划的任务。Planner 和 Executor 都是普通 Agent,"
+ "通过 Python for 循环连接。"
),
"nodes": [
_node("user", "user", "复杂任务"),
@@ -135,23 +133,19 @@ def retrieve(query: str) -> str:
_edge("memory", "step", label="下一步", style="loop"),
_edge("memory", "answer", label="全部完成"),
],
- "code": """from agentmold import Agent, tool
+ "code": """from agentmold.visual.teaching import run_plan_execute_experiment
-planner = Agent(
- name="Planner",
- instructions="把任务拆成 3-5 个可执行步骤,输出编号列表。",
- llm="mock",
+experiment = run_plan_execute_experiment(
+ "为一个离线知识助手制定三步实施方案"
)
-plan_text = planner("分析这篇论文的方法")
-
-# Execute each step with a worker agent.
-worker = Agent(name="Executor", tools=[...], llm="mock")
-for step in plan_text.split("\\n"):
- if step.strip():
- worker.run(step.strip())
+print(experiment.output)
""",
},
"Reflection(反思)": {
+ "architecture_id": "reflection",
+ "sample_input": "用两句话解释向量检索",
+ "runner_key": "run_reflection_experiment",
+ "run_status": "shipped",
"title": "Reflection / Self-Critique",
"summary": (
"Agent 先生成初稿,再用一个 Critic 角色自我审查,根据反馈修订,"
@@ -171,31 +165,22 @@ def retrieve(query: str) -> str:
_edge("revise", "critic", label="再次审查", style="loop"),
_edge("critic", "answer", label="质量达标"),
],
- "code": """from agentmold import Agent
-
-generator = Agent(
- name="Writer",
- instructions="写一段简洁的技术说明。",
- llm="mock",
-)
-critic = Agent(
- name="Critic",
- instructions="审查输出,指出不准确或可改进之处。若无问题则回复 DONE。",
- llm="mock",
-)
+ "code": """from agentmold.visual.teaching import run_reflection_experiment
-draft = generator("解释 RAG 的原理")
-feedback = critic(draft)
-while "DONE" not in feedback:
- draft = generator(f"根据反馈修订:{feedback}")
- feedback = critic(draft)
+experiment = run_reflection_experiment("用两句话解释向量检索")
+print(experiment.output)
""",
},
"Multi-Agent(多智能体协作)": {
+ "architecture_id": "multi_agent",
+ "sample_input": "比较关键词检索与向量检索的适用场景",
+ "runner_key": "run_multi_agent_experiment",
+ "run_status": "experimental",
"title": "Multi-Agent Coordination",
"summary": (
"一个协调者 Agent 把子任务分派给多个专家 Agent(每个有独立指令和"
"工具),汇总结果后回答。用 agent_as_tool 把子 Agent 包装成工具。"
+ "EasyAgent 没有 Coordinator 类,协调者只是另一个 Agent。"
),
"nodes": [
_node("user", "user", "复杂问题"),
@@ -214,34 +199,25 @@ def retrieve(query: str) -> str:
_edge("results", "coordinator", label="整合", style="loop"),
_edge("coordinator", "answer"),
],
- "code": """from agentmold import Agent
-from agentmold.experimental import agent_as_tool
-
-researcher = Agent(
- name="Researcher",
- instructions="检索并总结相关信息。",
- llm="mock",
-)
-analyst = Agent(
- name="Analyst",
- instructions="分析数据并给出结论。",
- llm="mock",
-)
+ "code": """# experimental agent_as_tool API 可能变化
+from agentmold.visual.teaching import run_multi_agent_experiment
-coordinator = Agent(
- name="Coordinator",
- instructions="把问题分派给专家,汇总后回答。",
- tools=[agent_as_tool(researcher), agent_as_tool(analyst)],
- llm="mock",
+experiment = run_multi_agent_experiment(
+ "比较关键词检索与向量检索的适用场景"
)
-answer = coordinator("tool: Researcher 检索 RAG")
+print(experiment.output)
""",
},
"Routing(路由分发)": {
+ "architecture_id": "routing",
+ "sample_input": "请用 Python 写一个去重函数",
+ "runner_key": "run_routing_experiment",
+ "run_status": "shipped",
"title": "Routing / Dispatcher",
"summary": (
"根据用户输入的类型,路由到不同的专家 Agent 处理。适合客服、"
- "多领域问答等需要分流的场景。"
+ "多领域问答等需要分流的场景。路由只是一个 Agent 或一个 if/else,"
+ "没有 Router 基类。"
),
"nodes": [
_node("user", "user", "用户输入"),
@@ -260,26 +236,10 @@ def retrieve(query: str) -> str:
_edge("expert2", "answer"),
_edge("expert3", "answer"),
],
- "code": """from agentmold import Agent
+ "code": """from agentmold.visual.teaching import run_routing_experiment
-coder = Agent(name="Coder", instructions="回答编程问题。", llm="mock")
-writer = Agent(name="Writer", instructions="回答写作问题。", llm="mock")
-math_agent = Agent(name="MathAgent", instructions="回答数学问题。", llm="mock")
-
-router = Agent(
- name="Router",
- instructions=(
- "根据问题类型选择专家:编程→Coder,写作→Writer,数学→MathAgent。"
- "只输出专家名称。"
- ),
- llm="mock",
-)
-
-question = "如何反转链表?"
-expert_name = router(question).strip()
-experts = {"Coder": coder, "Writer": writer, "MathAgent": math_agent}
-agent = experts.get(expert_name, coder)
-answer = agent(question)
+experiment = run_routing_experiment("请用 Python 写一个去重函数")
+print(experiment.output)
""",
},
}
@@ -300,7 +260,12 @@ def retrieve(query: str) -> str:
"nodes": [
_node("user", "user", "用户问题"),
_node("llm", "llm", "LLM 推理", detail="API 请求携带 tools 参数"),
- _node("tool_calls", "tool", "结构化 tool_calls", detail='{"name":"retrieve","arguments":{...}}'),
+ _node(
+ "tool_calls",
+ "tool",
+ "结构化 tool_calls",
+ detail='{"name":"retrieve","arguments":{...}}',
+ ),
_node("execute", "tool", "Agent 执行工具", detail="registry.call(name, arguments)"),
_node("result", "memory", "结果写回记忆", detail="role=tool, tool_call_id"),
_node("answer", "answer", "最终回答"),
@@ -338,7 +303,12 @@ def retrieve(query: str) -> str:
"nodes": [
_node("user", "user", "用户问题"),
_node("llm", "llm", "LLM 推理", detail="系统提示含工具定义文本"),
- _node("text", "tool", "文本输出含调用标记", detail="```tool\\n{\"name\":\"retrieve\",...}\\n```"),
+ _node(
+ "text",
+ "tool",
+ "文本输出含调用标记",
+ detail='```tool\\n{"name":"retrieve",...}\\n```',
+ ),
_node("parse", "decision", "文本解析", detail="正则/JSON 提取工具调用"),
_node("execute", "tool", "Agent 执行工具", detail="解析成功才执行"),
_node("result", "memory", "结果写回记忆", detail="作为纯文本观察"),
@@ -415,10 +385,7 @@ def _render_preset_diagram(preset: dict[str, Any]) -> str:
if edge.get("label")
else ""
)
- connector = (
- f''
- f'{label_badge}
'
- )
+ connector = f'{label_badge}
'
rows.append(
f''
f"{connector}"
@@ -426,8 +393,8 @@ def _render_preset_diagram(preset: dict[str, Any]) -> str:
f'
{html.escape(icon)}'
f'
'
f'
{html.escape(code)}
'
- f'
{html.escape(node["label"])}'
- f'
{html.escape(detail)}'
+ f"
{html.escape(node['label'])}"
+ f"
{html.escape(detail)}"
f"
" + "".join(parts) + "
"
+
+
def trace_metrics_html(summary: dict[str, Any]) -> str:
"""Render the compact metrics strip used by the trace replay panel."""
duration = summary.get("duration_ms")
@@ -316,6 +347,7 @@ def trace_metrics_html(summary: dict[str, Any]) -> str:
f"STATUS{status_text}
"
f"MODEL{model_text}
"
f"EVENTS{int(summary.get('event_count', 0))}
"
+ f"ROUNDS{html.escape(format_token_count(summary.get('rounds')))}
"
f"TOOLS{int(summary.get('tool_calls', 0))}
"
f"TOKENS{html.escape(token_text)}
"
f"CACHE HIT{html.escape(cache_hit_text)}
"
@@ -371,6 +403,7 @@ def card(summary: dict[str, Any], side: str) -> str:
+ metric("TOKENS", format_token_count(summary.get("total_tokens")))
+ metric("CACHE HIT", format_percent(summary.get("cache_hit_rate")))
+ metric("COST USD", value(summary, "cost", lambda item: f"${float(item):.6f}"))
+ + metric("ROUNDS", format_token_count(summary.get("rounds")))
+ metric("TOOLS", str(summary.get("tool_calls", 0)))
+ metric("SCHEMA", str(summary.get("tool_schema_fingerprint") or "-"))
+ metric("STATUS", str(summary.get("status", "unknown")).upper())
diff --git a/src/agentmold/visual/settings.py b/src/agentmold/visual/settings.py
index b88f758..6261e28 100644
--- a/src/agentmold/visual/settings.py
+++ b/src/agentmold/visual/settings.py
@@ -36,7 +36,6 @@
"custom_tool_files",
"mcp_url",
"rag_text",
- "agent_mode",
"loop_detection_threshold",
"require_approval",
"audit_log",
@@ -126,7 +125,10 @@ def load_visual_agent_config(path: str | Path = _DEFAULT_AGENT_PATH) -> dict[str
return {}
loaded = {key: config[key] for key in _AGENT_FIELDS if key in config}
- for key in ("name", "instructions", "connection_type", "custom_interface"):
+ for key in ("name", "instructions"):
+ if key in loaded and (not isinstance(loaded[key], str) or not loaded[key].strip()):
+ loaded.pop(key)
+ for key in ("connection_type", "custom_interface"):
if key in loaded and not isinstance(loaded[key], str):
loaded.pop(key)
iterations = loaded.get("max_iterations")
@@ -146,8 +148,6 @@ def load_visual_agent_config(path: str | Path = _DEFAULT_AGENT_PATH) -> dict[str
and (key != "custom_tool_files" or Path(value).name == value)
)
)
- if "agent_mode" in loaded and not isinstance(loaded["agent_mode"], str):
- loaded.pop("agent_mode", None)
threshold = loaded.get("loop_detection_threshold")
if threshold is not None and (
not isinstance(threshold, int) or isinstance(threshold, bool) or not 1 <= threshold <= 20
diff --git a/src/agentmold/visual/teaching.py b/src/agentmold/visual/teaching.py
new file mode 100644
index 0000000..a5b3c54
--- /dev/null
+++ b/src/agentmold/visual/teaching.py
@@ -0,0 +1,712 @@
+"""Deterministic, offline teaching experiments for common agent architectures.
+
+The runners in this module deliberately use ordinary Python control flow. Agent
+work is always performed by real :class:`~agentmold.agent.Agent` instances and
+is preserved as normal traces; :class:`TeachingEvent` records only orchestration
+that happens outside an Agent.
+"""
+
+from __future__ import annotations
+
+import asyncio
+import json
+import math
+from collections import deque
+from collections.abc import Callable, Coroutine, Iterable
+from concurrent.futures import ThreadPoolExecutor
+from dataclasses import dataclass, field
+from typing import Any, Final, TypeAlias, TypedDict, TypeVar
+
+from agentmold import Agent, LogLevel, tool
+from agentmold.agent import AgentTrace
+from agentmold.exceptions import LLMError
+from agentmold.experimental import agent_as_tool
+from agentmold.llm import LLM, LlmResponse, Message
+
+__all__ = [
+ "ARCHITECTURE_MODES",
+ "ScriptedLLM",
+ "TeachingEvent",
+ "TeachingExperiment",
+ "arun_multi_agent",
+ "arun_multi_agent_experiment",
+ "run_multi_agent",
+ "run_multi_agent_experiment",
+ "run_plan_execute",
+ "run_plan_execute_experiment",
+ "run_react",
+ "run_react_experiment",
+ "run_reflection",
+ "run_reflection_experiment",
+ "run_routing",
+ "run_routing_experiment",
+ "run_teaching_experiment",
+ "source_code",
+ "traces_to_jsonl",
+]
+
+
+JSONScalar: TypeAlias = str | int | float | bool | None
+JSONValue: TypeAlias = JSONScalar | list["JSONValue"] | dict[str, "JSONValue"]
+JSONObject: TypeAlias = dict[str, JSONValue]
+
+
+class ArchitectureMode(TypedDict):
+ """Stable display metadata shared with the architecture teaching UI."""
+
+ label: str
+ sample_input: str
+ preset_key: str
+
+
+ARCHITECTURE_MODES: Final[dict[str, ArchitectureMode]] = {
+ "react": {
+ "label": "ReAct(推理-行动)",
+ "sample_input": "RAG 如何减少模型幻觉?",
+ "preset_key": "ReAct(推理-行动)",
+ },
+ "plan_execute": {
+ "label": "Plan-and-Execute(计划-执行)",
+ "sample_input": "为一个离线知识助手制定三步实施方案",
+ "preset_key": "Plan-and-Execute(计划-执行)",
+ },
+ "reflection": {
+ "label": "Reflection(反思)",
+ "sample_input": "用两句话解释向量检索",
+ "preset_key": "Reflection(反思)",
+ },
+ "multi_agent": {
+ "label": "Multi-Agent(多智能体协作)",
+ "sample_input": "比较关键词检索与向量检索的适用场景",
+ "preset_key": "Multi-Agent(多智能体协作)",
+ },
+ "routing": {
+ "label": "Routing(路由分发)",
+ "sample_input": "请用 Python 写一个去重函数",
+ "preset_key": "Routing(路由分发)",
+ },
+}
+
+
+@dataclass(frozen=True)
+class TeachingEvent:
+ """One observable orchestration decision made outside an Agent run."""
+
+ type: str
+ actor: str
+ content: str = ""
+ data: dict[str, Any] = field(default_factory=dict)
+
+ @property
+ def kind(self) -> str:
+ """Alias useful to callers that use ``kind`` for event discriminators."""
+
+ return self.type
+
+ def to_dict(self) -> JSONObject:
+ """Return a strict JSON value, rejecting unsupported objects and NaN."""
+
+ return _strict_json_object(
+ {
+ "type": self.type,
+ "actor": self.actor,
+ "content": self.content,
+ "data": self.data,
+ }
+ )
+
+ def to_json(self) -> str:
+ """Serialize this event without permissive ``default=str`` coercion."""
+
+ return _json_dumps(self.to_dict(), indent=2)
+
+
+@dataclass(frozen=True)
+class TeachingExperiment:
+ """The output, orchestration events, and real traces from one lesson run."""
+
+ mode: str
+ input: str
+ output: str
+ events: list[TeachingEvent]
+ traces: list[AgentTrace]
+ source_code: str
+ metadata: dict[str, Any] = field(default_factory=dict)
+
+ def to_dict(self) -> JSONObject:
+ """Return a detached, strict JSON representation of the experiment."""
+
+ return _strict_json_object(
+ {
+ "mode": self.mode,
+ "input": self.input,
+ "output": self.output,
+ "events": [event.to_dict() for event in self.events],
+ "traces": [trace.to_dict() for trace in self.traces],
+ "source_code": self.source_code,
+ "metadata": self.metadata,
+ }
+ )
+
+ def to_json(self) -> str:
+ """Serialize the complete experiment as strict, human-readable JSON."""
+
+ return _json_dumps(self.to_dict(), indent=2)
+
+ def traces_to_jsonl(self) -> str:
+ """Serialize all real Agent traces in portable EasyAgent JSONL form."""
+
+ return traces_to_jsonl(self.traces)
+
+
+class ScriptedLLM(LLM):
+ """A deterministic LLM backed by an explicit, finite response queue.
+
+ This class is intentionally not registered as an EasyAgent provider. Each
+ teaching Agent receives a fresh instance, and an unexpected extra model call
+ fails instead of silently inventing a response.
+ """
+
+ def __init__(
+ self,
+ responses: Iterable[LlmResponse],
+ *,
+ model: str = "teaching-scripted",
+ ) -> None:
+ super().__init__(model=model, temperature=0.0)
+ self._responses = deque(responses)
+
+ @property
+ def remaining(self) -> int:
+ """Return the number of responses not yet consumed."""
+
+ return len(self._responses)
+
+ def _next_response(self) -> LlmResponse:
+ try:
+ return self._responses.popleft()
+ except IndexError as exc:
+ raise LLMError("ScriptedLLM response queue exhausted.") from exc
+
+ def _complete(
+ self,
+ messages: list[Message],
+ tools: list[dict[str, Any]] | None = None,
+ ) -> LlmResponse:
+ del messages, tools
+ return self._next_response()
+
+ async def acomplete(
+ self,
+ messages: list[Message],
+ tools: list[dict[str, Any]] | None = None,
+ ) -> LlmResponse:
+ del messages, tools
+ return self._next_response()
+
+
+def traces_to_jsonl(traces: Iterable[AgentTrace]) -> str:
+ """Serialize traces without coercing unsupported Python values to strings."""
+
+ lines: list[str] = []
+ for trace in traces:
+ run = _strict_json_object(trace.to_dict())
+ raw_events = run.pop("events", [])
+ if not isinstance(raw_events, list):
+ raise TypeError(f"Trace {trace.run_id!r} events must be a JSON array.")
+ lines.append(_json_dumps({"record_type": "run", **run}))
+ for event in raw_events:
+ if not isinstance(event, dict):
+ raise TypeError(f"Trace {trace.run_id!r} contains a non-object event.")
+ lines.append(
+ _json_dumps(
+ {
+ "record_type": "event",
+ "run_id": trace.run_id,
+ **event,
+ }
+ )
+ )
+ return "\n".join(lines) + ("\n" if lines else "")
+
+
+def source_code(mode: str, user_input: str | None = None) -> str:
+ """Return a compact, compilable, offline recipe for one teaching mode."""
+
+ if mode not in ARCHITECTURE_MODES:
+ available = ", ".join(ARCHITECTURE_MODES)
+ raise ValueError(f"Unknown teaching mode {mode!r}. Available modes: {available}.")
+ prompt = _resolve_input(mode, user_input)
+ runner_names = {
+ "react": "run_react_experiment",
+ "plan_execute": "run_plan_execute_experiment",
+ "reflection": "run_reflection_experiment",
+ "multi_agent": "run_multi_agent_experiment",
+ "routing": "run_routing_experiment",
+ }
+ runner_name = runner_names[mode]
+ return (
+ f"from agentmold.visual.teaching import {runner_name}\n\n"
+ f"experiment = {runner_name}({prompt!r})\n"
+ "print(experiment.output)\n"
+ )
+
+
+def run_react_experiment(user_input: str | None = None) -> TeachingExperiment:
+ """Run one real ReAct tool round followed by a deterministic answer round."""
+
+ prompt = _resolve_input("react", user_input)
+
+ @tool
+ def retrieve(query: str) -> str:
+ """Retrieve a deterministic fact from the local teaching corpus."""
+
+ return (
+ f"Local evidence for {query!r}: retrieval grounds an answer in selected "
+ "source passages."
+ )
+
+ answer = (
+ f"ReAct result for {prompt}: local evidence was retrieved before the final answer, "
+ "so the claim is grounded in an observable tool result."
+ )
+ agent = Agent(
+ name="ReAct Agent",
+ instructions="Retrieve local evidence once, then answer from that observation.",
+ tools=[retrieve],
+ llm=ScriptedLLM(
+ [
+ LlmResponse(
+ content="",
+ tool_calls=[
+ {
+ "id": "react-retrieve",
+ "name": "retrieve",
+ "arguments": {"query": prompt},
+ }
+ ],
+ ),
+ LlmResponse(content=answer),
+ ]
+ ),
+ log_level=LogLevel.SILENT,
+ )
+ events = [TeachingEvent("agent_started", "ReAct Agent", prompt)]
+ output = agent.run(prompt)
+ trace = _require_trace(agent)
+ events.append(
+ TeachingEvent(
+ "agent_completed",
+ "ReAct Agent",
+ output,
+ {"run_id": trace.run_id},
+ )
+ )
+ return TeachingExperiment(
+ mode="react",
+ input=prompt,
+ output=output,
+ events=events,
+ traces=[trace],
+ source_code=source_code("react", prompt),
+ metadata={"tool": "retrieve"},
+ )
+
+
+def run_plan_execute_experiment(user_input: str | None = None) -> TeachingExperiment:
+ """Plan three steps, execute each with a fresh Worker, then synthesize."""
+
+ prompt = _resolve_input("plan_execute", user_input)
+ steps = [
+ f"Clarify the goal and constraints for: {prompt}",
+ "Gather the relevant offline evidence and identify trade-offs",
+ "Turn the evidence into a concise, actionable conclusion",
+ ]
+ plan_text = "\n".join(f"{index}. {step}" for index, step in enumerate(steps, start=1))
+ planner = Agent(
+ name="Planner",
+ instructions="Return exactly three ordered implementation steps.",
+ llm=ScriptedLLM([LlmResponse(content=plan_text)]),
+ log_level=LogLevel.SILENT,
+ )
+ events = [TeachingEvent("planning_started", "Planner", prompt)]
+ observed_plan = planner.run(prompt)
+ traces = [_require_trace(planner)]
+ parsed_steps = _parse_numbered_plan(observed_plan)
+ if len(parsed_steps) != 3:
+ raise RuntimeError("The teaching Planner must produce exactly three steps.")
+ events.append(TeachingEvent("plan_created", "Planner", observed_plan, {"steps": parsed_steps}))
+
+ step_results: list[str] = []
+ for index, step in enumerate(parsed_steps, start=1):
+ worker_name = f"Worker {index}"
+ result = f"Step {index} completed: {step}"
+ worker = Agent(
+ name=worker_name,
+ instructions="Complete only the assigned plan step.",
+ llm=ScriptedLLM([LlmResponse(content=result)]),
+ log_level=LogLevel.SILENT,
+ )
+ events.append(TeachingEvent("step_started", worker_name, step, {"step_index": index}))
+ observed_result = worker.run(step)
+ traces.append(_require_trace(worker))
+ step_results.append(observed_result)
+ events.append(
+ TeachingEvent(
+ "step_completed",
+ worker_name,
+ observed_result,
+ {"step_index": index},
+ )
+ )
+
+ synthesis = "Plan-and-Execute result:\n" + "\n".join(step_results)
+ synthesizer = Agent(
+ name="Synthesizer",
+ instructions="Combine every completed step without dropping information.",
+ llm=ScriptedLLM([LlmResponse(content=synthesis)]),
+ log_level=LogLevel.SILENT,
+ )
+ events.append(
+ TeachingEvent(
+ "synthesis_started",
+ "Synthesizer",
+ data={"result_count": len(step_results)},
+ )
+ )
+ output = synthesizer.run("\n".join(step_results))
+ traces.append(_require_trace(synthesizer))
+ events.append(TeachingEvent("synthesis_completed", "Synthesizer", output))
+ return TeachingExperiment(
+ mode="plan_execute",
+ input=prompt,
+ output=output,
+ events=events,
+ traces=traces,
+ source_code=source_code("plan_execute", prompt),
+ metadata={"plan": parsed_steps, "step_results": step_results},
+ )
+
+
+def run_reflection_experiment(user_input: str | None = None) -> TeachingExperiment:
+ """Generate, accept one Critic feedback round, revise, and stop at DONE."""
+
+ prompt = _resolve_input("reflection", user_input)
+ draft = f"Draft for {prompt}: vector retrieval finds semantically related text."
+ feedback = "Add how embeddings and similarity make the retrieval criterion explicit."
+ revision = (
+ f"Revised answer for {prompt}: embeddings map the query and passages to vectors; "
+ "a similarity measure selects the closest passages."
+ )
+ generator = Agent(
+ name="Generator",
+ instructions="Write a draft, then perform at most one requested revision.",
+ llm=ScriptedLLM([LlmResponse(content=draft), LlmResponse(content=revision)]),
+ log_level=LogLevel.SILENT,
+ )
+ critic = Agent(
+ name="Critic",
+ instructions="Give concrete feedback once; reply DONE when the revision resolves it.",
+ llm=ScriptedLLM([LlmResponse(content=feedback), LlmResponse(content="DONE")]),
+ log_level=LogLevel.SILENT,
+ )
+
+ events = [TeachingEvent("generation_started", "Generator", prompt)]
+ output = generator.run(prompt)
+ traces = [_require_trace(generator)]
+ events.append(TeachingEvent("draft_created", "Generator", output))
+
+ review = critic.run(output)
+ traces.append(_require_trace(critic))
+ if review.strip() != "DONE":
+ events.append(TeachingEvent("feedback_received", "Critic", review, {"feedback_round": 1}))
+ output = generator.run(f"Revise this draft using the feedback: {review}")
+ traces.append(_require_trace(generator))
+ events.append(TeachingEvent("revision_created", "Generator", output, {"feedback_round": 1}))
+ review = critic.run(output)
+ traces.append(_require_trace(critic))
+
+ if review.strip() != "DONE":
+ raise RuntimeError("Reflection did not terminate after the single allowed feedback round.")
+ events.append(TeachingEvent("reflection_done", "Critic", "DONE", {"feedback_rounds": 1}))
+ return TeachingExperiment(
+ mode="reflection",
+ input=prompt,
+ output=output,
+ events=events,
+ traces=traces,
+ source_code=source_code("reflection", prompt),
+ metadata={"feedback_rounds": 1, "critic_status": "DONE"},
+ )
+
+
+async def arun_multi_agent_experiment(
+ user_input: str | None = None,
+) -> TeachingExperiment:
+ """Delegate to two child Agents in parallel and preserve the trace family."""
+
+ prompt = _resolve_input("multi_agent", user_input)
+ research_answer = f"Research evidence for {prompt}: keyword search is exact and auditable."
+ analysis_answer = f"Analysis for {prompt}: vector search handles semantic variation."
+ researcher = Agent(
+ name="Researcher",
+ instructions="Provide concise offline evidence.",
+ llm=ScriptedLLM([LlmResponse(content=research_answer)]),
+ log_level=LogLevel.SILENT,
+ )
+ analyst = Agent(
+ name="Analyst",
+ instructions="Compare trade-offs in the supplied task.",
+ llm=ScriptedLLM([LlmResponse(content=analysis_answer)]),
+ log_level=LogLevel.SILENT,
+ )
+ researcher_tool = agent_as_tool(researcher, name="consult_researcher")
+ analyst_tool = agent_as_tool(analyst, name="consult_analyst")
+ coordinated_answer = (
+ f"Multi-Agent result for {prompt}: use keyword retrieval for exact terms and "
+ "vector retrieval for semantic variation; combine them when both properties matter."
+ )
+ coordinator = Agent(
+ name="Coordinator",
+ instructions="Consult both experts in one turn, then combine their findings.",
+ tools=[researcher_tool, analyst_tool],
+ llm=ScriptedLLM(
+ [
+ LlmResponse(
+ content="",
+ tool_calls=[
+ {
+ "id": "research-delegation",
+ "name": "consult_researcher",
+ "arguments": {"request": prompt},
+ },
+ {
+ "id": "analysis-delegation",
+ "name": "consult_analyst",
+ "arguments": {"request": prompt},
+ },
+ ],
+ ),
+ LlmResponse(content=coordinated_answer),
+ ]
+ ),
+ log_level=LogLevel.SILENT,
+ )
+
+ events = [TeachingEvent("coordination_started", "Coordinator", prompt)]
+ output = await coordinator.arun(prompt)
+ parent_trace = _require_trace(coordinator)
+ researcher_trace = _require_trace(researcher)
+ analyst_trace = _require_trace(analyst)
+ events.append(
+ TeachingEvent(
+ "coordination_completed",
+ "Coordinator",
+ output,
+ {
+ "child_run_ids": [researcher_trace.run_id, analyst_trace.run_id],
+ "delegation_count": 2,
+ },
+ )
+ )
+ return TeachingExperiment(
+ mode="multi_agent",
+ input=prompt,
+ output=output,
+ events=events,
+ traces=[parent_trace, researcher_trace, analyst_trace],
+ source_code=source_code("multi_agent", prompt),
+ metadata={"parallel_delegations": 2},
+ )
+
+
+def run_multi_agent_experiment(user_input: str | None = None) -> TeachingExperiment:
+ """Synchronously run the async collaboration, even inside an active event loop."""
+
+ return _run_async_safely(lambda: arun_multi_agent_experiment(user_input))
+
+
+def run_routing_experiment(user_input: str | None = None) -> TeachingExperiment:
+ """Select one expert by a deterministic rule, then run only that expert."""
+
+ prompt = _resolve_input("routing", user_input)
+ route, rule = _select_route(prompt)
+ router = Agent(
+ name="Router",
+ instructions="Classify the request as Coder, Writer, or Math and output only the name.",
+ llm=ScriptedLLM([LlmResponse(content=route)]),
+ log_level=LogLevel.SILENT,
+ )
+ selected = router.run(prompt).strip()
+ router_trace = _require_trace(router)
+ if selected != route:
+ raise RuntimeError(f"Router returned unexpected expert {selected!r}.")
+
+ expert_instructions = {
+ "Coder": "Answer the programming request with a concise implementation approach.",
+ "Writer": "Answer the writing request with clear, audience-aware prose.",
+ "Math": "Answer the mathematics request with explicit reasoning.",
+ }
+ expert_answer = f"{selected} result for {prompt}: handled offline by the selected expert."
+ expert = Agent(
+ name=selected,
+ instructions=expert_instructions[selected],
+ llm=ScriptedLLM([LlmResponse(content=expert_answer)]),
+ log_level=LogLevel.SILENT,
+ )
+ events = [
+ TeachingEvent(
+ "route_selected",
+ "Router",
+ selected,
+ {"rule": rule, "expert": selected},
+ ),
+ TeachingEvent("expert_started", selected, prompt),
+ ]
+ output = expert.run(prompt)
+ expert_trace = _require_trace(expert)
+ events.append(
+ TeachingEvent(
+ "expert_completed",
+ selected,
+ output,
+ {"run_id": expert_trace.run_id},
+ )
+ )
+ return TeachingExperiment(
+ mode="routing",
+ input=prompt,
+ output=output,
+ events=events,
+ traces=[router_trace, expert_trace],
+ source_code=source_code("routing", prompt),
+ metadata={"route_selected": selected, "routing_rule": rule},
+ )
+
+
+def run_teaching_experiment(
+ mode: str,
+ user_input: str | None = None,
+) -> TeachingExperiment:
+ """Run one of the five offline teaching architectures by stable mode key."""
+
+ runners: dict[str, Callable[[str | None], TeachingExperiment]] = {
+ "react": run_react_experiment,
+ "plan_execute": run_plan_execute_experiment,
+ "reflection": run_reflection_experiment,
+ "multi_agent": run_multi_agent_experiment,
+ "routing": run_routing_experiment,
+ }
+ try:
+ runner = runners[mode]
+ except KeyError as exc:
+ available = ", ".join(ARCHITECTURE_MODES)
+ raise ValueError(f"Unknown teaching mode {mode!r}. Available modes: {available}.") from exc
+ return runner(user_input)
+
+
+# Short aliases keep recipes readable without changing the explicit experiment APIs.
+run_react = run_react_experiment
+run_plan_execute = run_plan_execute_experiment
+run_reflection = run_reflection_experiment
+arun_multi_agent = arun_multi_agent_experiment
+run_multi_agent = run_multi_agent_experiment
+run_routing = run_routing_experiment
+
+
+def _resolve_input(mode: str, user_input: str | None) -> str:
+ if user_input is None:
+ return ARCHITECTURE_MODES[mode]["sample_input"]
+ if not isinstance(user_input, str):
+ raise TypeError("user_input must be a string or None.")
+ if not user_input.strip():
+ raise ValueError("user_input must not be empty.")
+ return user_input
+
+
+def _require_trace(agent: Agent) -> AgentTrace:
+ trace = agent.last_trace
+ if trace is None:
+ raise RuntimeError(f"Agent {agent.name!r} completed without a trace.")
+ return trace
+
+
+def _parse_numbered_plan(plan_text: str) -> list[str]:
+ steps: list[str] = []
+ for expected_index, raw_line in enumerate(plan_text.splitlines(), start=1):
+ prefix = f"{expected_index}. "
+ if not raw_line.startswith(prefix):
+ raise RuntimeError("Planner output must be a consecutive numbered list.")
+ step = raw_line[len(prefix) :].strip()
+ if not step:
+ raise RuntimeError("Planner output contains an empty step.")
+ steps.append(step)
+ return steps
+
+
+def _select_route(user_input: str) -> tuple[str, str]:
+ normalized = user_input.casefold()
+ math_keywords = ("math", "calculate", "equation", "数学", "计算", "方程", "+", "=")
+ code_keywords = ("python", "code", "function", "bug", "api", "代码", "编程", "程序")
+ writing_keywords = ("write", "draft", "copy", "story", "写作", "文案", "文章")
+ if any(keyword in normalized for keyword in math_keywords):
+ return "Math", "math_keyword"
+ if any(keyword in normalized for keyword in code_keywords):
+ return "Coder", "code_keyword"
+ if any(keyword in normalized for keyword in writing_keywords):
+ return "Writer", "writing_keyword"
+ return "Writer", "default_writing"
+
+
+T = TypeVar("T")
+
+
+def _run_async_safely(factory: Callable[[], Coroutine[Any, Any, T]]) -> T:
+ try:
+ asyncio.get_running_loop()
+ except RuntimeError:
+ return asyncio.run(factory())
+
+ # ``asyncio.run`` cannot nest in the caller's loop; a dedicated thread owns
+ # a fresh loop while preserving this synchronous API.
+ def run_in_new_loop() -> T:
+ return asyncio.run(factory())
+
+ with ThreadPoolExecutor(max_workers=1) as executor:
+ return executor.submit(run_in_new_loop).result()
+
+
+def _strict_json_object(value: object) -> JSONObject:
+ normalized = _strict_json_value(value)
+ if not isinstance(normalized, dict):
+ raise TypeError("Expected a JSON object.")
+ return normalized
+
+
+def _strict_json_value(value: object, path: str = "$") -> JSONValue:
+ if value is None or isinstance(value, (str, bool, int)):
+ return value
+ if isinstance(value, float):
+ if not math.isfinite(value):
+ raise ValueError(f"Non-finite float at {path} is not valid JSON.")
+ return value
+ if isinstance(value, list):
+ return [_strict_json_value(item, f"{path}[{index}]") for index, item in enumerate(value)]
+ if isinstance(value, dict):
+ normalized: JSONObject = {}
+ for key, item in value.items():
+ if not isinstance(key, str):
+ raise TypeError(f"JSON object key at {path} must be a string.")
+ normalized[key] = _strict_json_value(item, f"{path}.{key}")
+ return normalized
+ raise TypeError(f"Unsupported JSON value at {path}: {type(value).__name__}.")
+
+
+def _json_dumps(value: JSONValue, *, indent: int | None = None) -> str:
+ return json.dumps(
+ value,
+ ensure_ascii=False,
+ allow_nan=False,
+ indent=indent,
+ sort_keys=True,
+ )
diff --git a/src/agentmold/visual/teaching_models.py b/src/agentmold/visual/teaching_models.py
new file mode 100644
index 0000000..a3a6331
--- /dev/null
+++ b/src/agentmold/visual/teaching_models.py
@@ -0,0 +1,116 @@
+"""Resolve saved non-mock models for live architecture experiments."""
+
+from __future__ import annotations
+
+from dataclasses import dataclass
+from typing import Any
+
+from agentmold.visual.agent_config import CONNECTION_DEFAULTS, llm_config_from_ui
+from agentmold.visual.settings import load_visual_agent_config, load_visual_profiles
+
+__all__ = [
+ "LiveTeachingModel",
+ "load_live_teaching_models",
+ "resolve_live_teaching_model",
+ "resolve_live_teaching_models",
+]
+
+
+@dataclass(frozen=True)
+class LiveTeachingModel:
+ """A display-safe identity and a complete private Agent LLM config."""
+
+ key: str
+ label: str
+ config: dict[str, Any]
+
+
+def load_live_teaching_models() -> tuple[list[LiveTeachingModel], list[str]]:
+ """Load all saved provider profiles and prefer the current ReAct provider."""
+ return resolve_live_teaching_models(load_visual_agent_config(), load_visual_profiles())
+
+
+def resolve_live_teaching_models(
+ agent_config: dict[str, Any],
+ profiles: dict[str, dict[str, Any]],
+) -> tuple[list[LiveTeachingModel], list[str]]:
+ """Resolve every non-Mock profile, returning actionable invalid-profile notes."""
+ current_connection = str(agent_config.get("connection_type") or "")
+ current_interface = str(agent_config.get("custom_interface") or "OpenAI 兼容")
+ models: list[LiveTeachingModel] = []
+ errors: list[str] = []
+ for profile_key, profile in profiles.items():
+ if profile_key == "Mock(离线)":
+ continue
+ if profile_key.startswith("自定义提供商:"):
+ connection_type = "自定义提供商"
+ custom_interface = profile_key.split(":", 1)[1] or "OpenAI 兼容"
+ else:
+ connection_type = profile_key
+ custom_interface = "OpenAI 兼容"
+ model, error = resolve_live_teaching_model(
+ connection_type,
+ custom_interface,
+ profile_key,
+ profile,
+ )
+ if model is not None:
+ models.append(model)
+ elif error:
+ errors.append(error)
+
+ current_key = (
+ f"自定义提供商:{current_interface}"
+ if current_connection == "自定义提供商"
+ else current_connection
+ )
+ models.sort(key=lambda model: (model.key != current_key, model.label.casefold()))
+ return models, errors
+
+
+def resolve_live_teaching_model(
+ connection_type: str,
+ custom_interface: str,
+ profile_key: str,
+ profile: dict[str, Any],
+) -> tuple[LiveTeachingModel | None, str | None]:
+ """Resolve one saved profile without exposing credentials in its label."""
+ if connection_type == "Mock(离线)":
+ return None, "Mock(离线)只会回显输入,不能驱动真实架构决策。"
+ if connection_type not in CONNECTION_DEFAULTS:
+ return None, f"保存的接口配置 {profile_key!r} 不受支持。"
+ if not isinstance(profile, dict):
+ return None, f"{profile_key} 的接口配置无效。"
+
+ default_model, default_base_url = CONNECTION_DEFAULTS[connection_type]
+ model = str(profile.get("model") or default_model).strip()
+ if not model:
+ return None, f"{profile_key} 配置缺少模型 ID。"
+ try:
+ temperature = float(profile.get("temperature", 0.2))
+ timeout = float(profile.get("timeout", 30.0))
+ max_tokens = int(profile.get("max_tokens", 4096))
+ except (TypeError, ValueError):
+ return None, f"{profile_key} 的数值参数无效,请在 ReAct 中重新保存。"
+
+ config = llm_config_from_ui(
+ connection_type,
+ model,
+ str(profile.get("api_key") or ""),
+ str(profile.get("base_url") or default_base_url),
+ temperature,
+ timeout,
+ max_tokens,
+ custom_interface,
+ )
+ if config == "mock":
+ return None, f"{profile_key} 不是可用的真实模型配置。"
+ provider = str(config.get("provider") or connection_type)
+ return (
+ LiveTeachingModel(
+ key=profile_key,
+ label=f"{profile_key} · {provider} / {model}",
+ config=config,
+ ),
+ None,
+ )
diff --git a/src/agentmold/visual/teaching_view.py b/src/agentmold/visual/teaching_view.py
new file mode 100644
index 0000000..b81ee1e
--- /dev/null
+++ b/src/agentmold/visual/teaching_view.py
@@ -0,0 +1,487 @@
+"""Streamlit view for live and deterministic architecture experiments."""
+
+from __future__ import annotations
+
+import html
+from typing import Any, Final
+
+from agentmold.visual.architecture import (
+ architecture_description,
+ architecture_diagram_html,
+)
+from agentmold.visual.live_teaching import (
+ ProgressEvent,
+ live_source_code,
+ run_live_teaching_experiment,
+)
+from agentmold.visual.renderers import (
+ execution_map_html,
+ timeline_html,
+ trace_breadcrumb_html,
+ trace_metrics_html,
+)
+from agentmold.visual.teaching import (
+ ARCHITECTURE_MODES,
+ TeachingEvent,
+ TeachingExperiment,
+ run_teaching_experiment,
+ source_code,
+)
+from agentmold.visual.teaching_models import LiveTeachingModel, load_live_teaching_models
+from agentmold.visual.traces import build_trace_forest, summarize_trace_run
+
+__all__ = ["render_teaching_view"]
+
+
+_EXECUTION_MODES: Final[dict[str, str]] = {
+ "live": "真实模型执行",
+ "offline": "确定性离线演示",
+}
+
+_EXPECTED_CALLS: Final[dict[str, str]] = {
+ "plan_execute": "约 4-7 次模型调用:规划、2-5 个步骤、综合",
+ "reflection": "约 3-5 次模型调用:生成、批评、最多 2 次修订",
+ "multi_agent": "通常 4 次模型调用:协调 2 轮 + 2 个专家",
+ "routing": "2 次模型调用:路由 + 选中专家",
+}
+
+_MODE_GUIDANCE: Final[dict[str, dict[str, str]]] = {
+ "plan_execute": {
+ "title": "Plan-and-Execute",
+ "status": "真实执行 + 离线演示",
+ "non_goal": "模型生成计划,普通 Python 逐步执行;不提供工作流 DSL 或图调度器。",
+ },
+ "reflection": {
+ "title": "Reflection",
+ "status": "真实执行 + 离线演示",
+ "non_goal": "模型生成反馈并驱动有限修订;不展示或推断隐藏思维链。",
+ },
+ "multi_agent": {
+ "title": "Multi-Agent",
+ "status": "真实执行 · experimental",
+ "non_goal": "Coordinator 通过 experimental agent_as_tool 委派,不承诺通用协调器 API。",
+ },
+ "routing": {
+ "title": "Routing",
+ "status": "真实执行 + 离线演示",
+ "non_goal": "模型选择且只运行命中的专家;不引入 Router 基类或通用节点引擎。",
+ },
+}
+
+
+def render_teaching_view(st: Any, architecture_id: str) -> None:
+ """Render one live or offline architecture experiment with honest traces."""
+ if architecture_id not in _MODE_GUIDANCE:
+ st.error(f"未知教学架构: {architecture_id}")
+ return
+
+ guidance = _MODE_GUIDANCE[architecture_id]
+ mode = ARCHITECTURE_MODES[architecture_id]
+ state_prefix = f"teaching.{architecture_id}"
+ input_key = f"{state_prefix}.input"
+ input_widget_key = f"_{state_prefix}.input_widget"
+ execution_key = f"{state_prefix}.execution_mode"
+ execution_widget_key = f"_{state_prefix}.execution_widget"
+ if input_key not in st.session_state:
+ st.session_state[input_key] = mode["sample_input"]
+ if input_widget_key not in st.session_state:
+ st.session_state[input_widget_key] = st.session_state[input_key]
+ if execution_key not in st.session_state:
+ st.session_state[execution_key] = "live"
+ if execution_widget_key not in st.session_state:
+ st.session_state[execution_widget_key] = _EXECUTION_MODES[st.session_state[execution_key]]
+
+ st.markdown(
+ ""
+ f"ARCHITECTURE LAB
{html.escape(guidance['title'])}
"
+ f"{html.escape(guidance['status'])}"
+ "",
+ unsafe_allow_html=True,
+ )
+ st.caption(guidance["non_goal"])
+
+ def remember_execution_mode() -> None:
+ selected = st.session_state[execution_widget_key]
+ reverse = {label: key for key, label in _EXECUTION_MODES.items()}
+ st.session_state[execution_key] = reverse[selected]
+
+ st.radio(
+ "执行方式",
+ options=list(_EXECUTION_MODES.values()),
+ key=execution_widget_key,
+ horizontal=True,
+ on_change=remember_execution_mode,
+ help="真实模式让模型响应驱动控制流;离线模式使用固定响应,仅演示流程。",
+ )
+ execution_mode = str(st.session_state[execution_key])
+ result_key = f"{state_prefix}.{execution_mode}.result"
+ error_key = f"{state_prefix}.{execution_mode}.error"
+
+ live_models, model_errors = load_live_teaching_models()
+ selected_model: LiveTeachingModel | None = None
+ if execution_mode == "live":
+ selected_model = _render_live_model_controls(st, state_prefix, live_models, model_errors)
+ else:
+ st.warning(
+ "确定性离线演示使用固定 ScriptedLLM 响应。它会产生真实 AgentTrace,"
+ "但不会根据任意输入做真实规划、批评、委派或路由。"
+ )
+
+ def remember_input() -> None:
+ st.session_state[input_key] = st.session_state[input_widget_key]
+
+ def reset_experiment() -> None:
+ sample_input = mode["sample_input"]
+ st.session_state[input_key] = sample_input
+ st.session_state[input_widget_key] = sample_input
+ st.session_state.pop(result_key, None)
+ st.session_state.pop(error_key, None)
+
+ input_col, action_col = st.columns([5, 1])
+ input_col.text_area(
+ "实验输入",
+ key=input_widget_key,
+ height=96,
+ help=(
+ "该输入会被实际模型用于规划和决策。"
+ if execution_mode == "live"
+ else "离线演示只把输入带入固定教学脚本。"
+ ),
+ on_change=remember_input,
+ )
+ with action_col:
+ st.markdown('操作
', unsafe_allow_html=True)
+ run_clicked = st.button(
+ "运行真实架构" if execution_mode == "live" else "运行离线演示",
+ type="primary",
+ use_container_width=True,
+ disabled=execution_mode == "live" and selected_model is None,
+ key=f"{state_prefix}.{execution_mode}.run",
+ )
+ st.button(
+ "重置",
+ use_container_width=True,
+ key=f"{state_prefix}.{execution_mode}.reset",
+ on_click=reset_experiment,
+ )
+
+ progress_key = f"{state_prefix}.{execution_mode}.progress"
+ progress_placeholder = st.empty()
+ previous_progress = st.session_state.get(progress_key, [])
+ if isinstance(previous_progress, list) and previous_progress:
+ progress_placeholder.markdown(
+ _progress_html(previous_progress),
+ unsafe_allow_html=True,
+ )
+
+ if run_clicked:
+ st.session_state[input_key] = st.session_state[input_widget_key]
+ st.session_state.pop(result_key, None)
+ st.session_state.pop(error_key, None)
+ st.session_state[progress_key] = []
+ progress_placeholder.empty()
+ progress_events: list[ProgressEvent] = []
+
+ def show_progress(event: ProgressEvent) -> None:
+ progress_events.append(event)
+ st.session_state[progress_key] = list(progress_events)
+ progress_placeholder.markdown(
+ _progress_html(progress_events),
+ unsafe_allow_html=True,
+ )
+
+ try:
+ if execution_mode == "live":
+ if selected_model is None:
+ raise RuntimeError("没有可用的真实模型配置。")
+ model_config = dict(selected_model.config)
+ experiment = run_live_teaching_experiment(
+ architecture_id,
+ str(st.session_state[input_key]),
+ lambda: dict(model_config),
+ on_progress=show_progress,
+ )
+ experiment.metadata["model_profile"] = selected_model.key
+ experiment.metadata["model_label"] = selected_model.label
+ else:
+ experiment = run_teaching_experiment(
+ architecture_id,
+ str(st.session_state[input_key]),
+ )
+ experiment.metadata["execution_mode"] = "offline_scripted"
+ except Exception as exc: # noqa: BLE001 - surface provider and orchestration failures
+ failure = ProgressEvent(
+ "failed",
+ guidance["title"],
+ f"执行失败:{type(exc).__name__}: {exc}",
+ "failed",
+ )
+ progress_events.append(failure)
+ st.session_state[progress_key] = list(progress_events)
+ progress_placeholder.markdown(
+ _progress_html(progress_events),
+ unsafe_allow_html=True,
+ )
+ st.session_state.pop(result_key, None)
+ st.session_state[error_key] = f"{type(exc).__name__}: {exc}"
+ else:
+ experiment.metadata["progress"] = [
+ {
+ "stage": event.stage,
+ "actor": event.actor,
+ "message": event.message,
+ "status": event.status,
+ "data": event.data,
+ }
+ for event in progress_events
+ ]
+ st.session_state[result_key] = experiment
+ st.session_state.pop(error_key, None)
+ _remember_experiment_traces(st, experiment)
+
+ error = st.session_state.get(error_key)
+ if error:
+ st.error(f"实验执行失败: {error}")
+ experiment = st.session_state.get(result_key)
+
+ st.divider()
+ st.markdown("### 概念示意")
+ st.caption("概念示意 · 非本次运行。节点表示预期控制流,不是 Trace 事件。")
+ diagram_col, code_col = st.columns([1, 1])
+ with diagram_col:
+ st.markdown(
+ f""
+ f"CONCEPT · NOT THIS RUN
{architecture_diagram_html(mode['preset_key'])}
运行当前执行方式后,这里会显示 Python 控制流、'
+ "真实 Trace 和导出。
",
+ unsafe_allow_html=True,
+ )
+ return
+
+ _render_execution_truth(st, experiment)
+ st.markdown("#### 最终输出")
+ st.write(experiment.output)
+ st.markdown("#### Python 控制流")
+ st.markdown(_teaching_events_html(experiment.events), unsafe_allow_html=True)
+ st.markdown("#### Agent Traces")
+ _render_experiment_traces(st, experiment)
+
+ st.markdown("#### 下一步")
+ replay_col, compare_col = st.columns(2)
+ if replay_col.button(
+ "查看这些运行",
+ use_container_width=True,
+ key=f"{state_prefix}.{execution_mode}.open_replay",
+ ):
+ st.session_state.ea_trace_jump_to = experiment.traces[0].run_id
+ st.session_state.ea_visual_view = "trace"
+ st.rerun()
+ if compare_col.button(
+ "比较这些 Agent",
+ type="primary",
+ use_container_width=True,
+ key=f"{state_prefix}.{execution_mode}.open_comparison",
+ ):
+ st.session_state.ea_pending_comparison_runs = [trace.run_id for trace in experiment.traces]
+ st.session_state.ea_visual_view = "evaluation"
+ st.rerun()
+
+ st.markdown("#### 导出")
+ json_col, trace_col, source_col = st.columns(3)
+ json_col.download_button(
+ "下载实验 JSON",
+ data=experiment.to_json(),
+ file_name=f"{execution_mode}-teaching-experiment.json",
+ mime="application/json",
+ use_container_width=True,
+ key=f"{state_prefix}.{execution_mode}.download_json",
+ )
+ trace_col.download_button(
+ "下载 Agent Traces",
+ data=experiment.traces_to_jsonl(),
+ file_name=f"{execution_mode}-agent-traces.jsonl",
+ mime="application/x-ndjson",
+ use_container_width=True,
+ key=f"{state_prefix}.{execution_mode}.download_traces",
+ )
+ source_col.download_button(
+ "下载 example.py",
+ data=experiment.source_code,
+ file_name="example.py",
+ mime="text/x-python",
+ use_container_width=True,
+ key=f"{state_prefix}.{execution_mode}.download_source",
+ )
+
+
+def _render_live_model_controls(
+ st: Any,
+ state_prefix: str,
+ models: list[LiveTeachingModel],
+ errors: list[str],
+) -> LiveTeachingModel | None:
+ if not models:
+ st.error("没有已保存的真实模型配置。先到 ReAct 选择非 Mock provider,填写并保存接口参数。")
+ if st.button(
+ "去 ReAct 配置模型", use_container_width=True, key=f"{state_prefix}.open_react"
+ ):
+ st.session_state.ea_architecture_mode = "react"
+ st.session_state.ea_visual_view = "architecture"
+ st.rerun()
+ for error in errors:
+ st.caption(error)
+ return None
+
+ by_key = {model.key: model for model in models}
+ selected_key = st.selectbox(
+ "真实执行模型",
+ options=list(by_key),
+ format_func=lambda key: by_key[key].label,
+ key=f"{state_prefix}.live_model",
+ help="模型响应将实际决定计划、反馈、委派或路由。API Key 不显示在标签和导出中。",
+ )
+ selected = by_key[selected_key]
+ st.info(f"{_EXPECTED_CALLS[state_prefix.split('.', 1)[1]]} · 当前:{selected.label}")
+ for error in errors:
+ st.caption(f"忽略无效配置:{error}")
+ return selected
+
+
+def _progress_html(events: list[ProgressEvent]) -> str:
+ rows: list[str] = []
+ for index, event in enumerate(events, start=1):
+ status_class = html.escape(event.status)
+ rows.append(
+ f""
+ f"
{index:02d}"
+ f"
{html.escape(event.actor)}"
+ f"
{html.escape(event.message)}
{heading}"
+ f"{len(events)} EVENTS
" + "".join(rows) + ""
+ )
+
+
+def _preview_source(
+ architecture_id: str,
+ execution_mode: str,
+ user_input: str,
+ experiment: Any,
+) -> str:
+ if isinstance(experiment, TeachingExperiment):
+ return experiment.source_code
+ if execution_mode == "live":
+ return live_source_code(architecture_id, user_input)
+ return source_code(architecture_id, user_input)
+
+
+def _render_execution_truth(st: Any, experiment: TeachingExperiment) -> None:
+ execution_mode = experiment.metadata.get("execution_mode")
+ if execution_mode == "live":
+ st.success(
+ f"真实模型已执行 · {experiment.metadata.get('model_label', '已保存模型')} · "
+ f"{len(experiment.traces)} 个 Agent run"
+ )
+ if experiment.mode == "multi_agent":
+ delegation_count = int(experiment.metadata.get("delegation_count", 0))
+ child_count = int(experiment.metadata.get("child_run_count", 0))
+ if experiment.metadata.get("used_both_specialists"):
+ st.success(f"Coordinator 实际委派 2 个专家,记录 {child_count} 个 child traces。")
+ else:
+ st.warning(
+ f"Coordinator 实际委派 {delegation_count} 次,记录 "
+ f"{child_count} 个 child traces;"
+ "模型没有按要求调用两个专家,本次结果不能视为完整 Multi-Agent 协作。"
+ )
+ else:
+ st.warning("固定响应离线演示:AgentTrace 真实,但模型决策由教学脚本预置。")
+
+
+def _teaching_events_html(events: list[TeachingEvent]) -> str:
+ rows: list[str] = []
+ for index, event in enumerate(events, start=1):
+ detail = event.content.strip()
+ if len(detail) > 240:
+ detail = detail[:240] + "…"
+ rows.append(
+ ""
+ f"
{index:02d}"
+ "
"
+ f"
{html.escape(event.type.replace('_', ' ').upper())}"
+ f"
{html.escape(event.actor)}"
+ f"
{html.escape(detail or '控制流事件已记录')}
"
+ "
" + "".join(rows) + "
"
+
+
+def _render_experiment_traces(st: Any, experiment: TeachingExperiment) -> None:
+ runs = [trace.to_dict() for trace in experiment.traces]
+ forest = build_trace_forest(runs)
+ summaries = {str(run["run_id"]): summarize_trace_run(run) for run in runs}
+ children = forest["children"]
+ all_runs = forest["all_runs"]
+
+ for index, trace in enumerate(experiment.traces, start=1):
+ run = trace.to_dict()
+ run_id = trace.run_id
+ summary = summaries[run_id]
+ parent_run = all_runs.get(str(run.get("parent_run_id") or ""))
+ child_runs = children.get(run_id, [])
+ label = f"{index:02d} · {trace.agent_name} · {run_id[:12]}"
+ with st.expander(label, expanded=index == 1):
+ trace_steps = [dict(step) for step in trace.steps]
+ st.markdown(
+ trace_breadcrumb_html(
+ summary,
+ summarize_trace_run(parent_run) if parent_run else None,
+ [summarize_trace_run(child) for child in child_runs],
+ ),
+ unsafe_allow_html=True,
+ )
+ st.markdown(trace_metrics_html(summary), unsafe_allow_html=True)
+ st.markdown(timeline_html(trace_steps), unsafe_allow_html=True)
+ st.markdown(
+ execution_map_html(trace_steps, user_input=trace.user_input),
+ unsafe_allow_html=True,
+ )
+
+
+def _remember_experiment_traces(st: Any, experiment: TeachingExperiment) -> None:
+ existing = st.session_state.get("trace_runs", [])
+ by_id = {
+ str(run.get("run_id")): run
+ for run in existing
+ if isinstance(run, dict) and run.get("run_id")
+ }
+ for trace in experiment.traces:
+ by_id[trace.run_id] = trace.to_dict()
+ st.session_state.trace_runs = list(by_id.values())[-50:]
diff --git a/src/agentmold/visual/theme.py b/src/agentmold/visual/theme.py
index 3de8bb2..77fd13b 100644
--- a/src/agentmold/visual/theme.py
+++ b/src/agentmold/visual/theme.py
@@ -326,8 +326,13 @@ def inject_theme(st: Any) -> None:
.ea-title span { color: var(--ea-magenta); }
.ea-subtitle {
color: var(--ea-muted);
+ font-family: system-ui, -apple-system, "Segoe UI", sans-serif;
font-size: 0.92rem;
+ font-weight: 400;
+ letter-spacing: 0;
+ line-height: 1.55;
margin-top: 0.55rem;
+ text-rendering: optimizeLegibility;
}
.ea-strip {
display: flex;
@@ -524,7 +529,11 @@ def inject_theme(st: Any) -> None:
margin-right: 0.3rem;
width: 0.4rem;
}
- .ea-map-heading small { color: var(--ea-muted); font-size: 0.58rem; letter-spacing: 0.08em; }
+ .ea-map-heading small {
+ color: var(--ea-muted);
+ font-size: 0.58rem;
+ letter-spacing: 0.08em;
+ }
.ea-flow-canvas { padding: 0.7rem 0.1rem 0.2rem; }
.ea-flow-step {
align-items: start;
@@ -804,8 +813,14 @@ def inject_theme(st: Any) -> None:
}
.ea-arch-node-plan .ea-arch-node-icon { color: var(--ea-magenta); border-radius: 5px; }
.ea-arch-node-reflect .ea-arch-node-icon { color: var(--ea-lime); }
- .ea-arch-node-answer .ea-arch-node-icon { color: var(--ea-magenta); transform: rotate(45deg); }
- .ea-arch-node-answer .ea-arch-node-icon span { display: inline-block; transform: rotate(-45deg); }
+ .ea-arch-node-answer .ea-arch-node-icon {
+ color: var(--ea-magenta);
+ transform: rotate(45deg);
+ }
+ .ea-arch-node-answer .ea-arch-node-icon span {
+ display: inline-block;
+ transform: rotate(-45deg);
+ }
.ea-arch-node-router .ea-arch-node-icon { color: var(--ea-amber); border-radius: 7px; }
.ea-arch-empty {
background: var(--ea-surface);
@@ -817,6 +832,124 @@ def inject_theme(st: Any) -> None:
padding: 1rem;
text-align: center;
}
+ .ea-teaching-head {
+ align-items: center;
+ border-bottom: 1px solid var(--ea-line);
+ display: flex;
+ justify-content: space-between;
+ margin: 0.25rem 0 0.35rem;
+ padding: 0.35rem 0 0.8rem;
+ }
+ .ea-teaching-head span,
+ .ea-concept-watermark {
+ color: var(--ea-cyan);
+ font-family: ui-monospace, SFMono-Regular, Menlo, Consolas, monospace;
+ font-size: 0.65rem;
+ font-weight: 700;
+ letter-spacing: 0.12em;
+ }
+ .ea-teaching-head h2 {
+ color: var(--ea-text);
+ font-size: 1.55rem;
+ letter-spacing: 0;
+ margin: 0.15rem 0 0;
+ }
+ .ea-teaching-head > strong {
+ border: 1px solid var(--ea-line-strong);
+ border-radius: 6px;
+ color: var(--ea-lime);
+ font-family: ui-monospace, SFMono-Regular, Menlo, Consolas, monospace;
+ font-size: 0.7rem;
+ padding: 0.35rem 0.55rem;
+ }
+ .ea-concept-band {
+ background: var(--ea-surface-2);
+ border-left: 3px solid var(--ea-cyan);
+ padding: 0.75rem;
+ }
+ .ea-concept-watermark {
+ border-bottom: 1px dashed var(--ea-line-strong);
+ color: var(--ea-muted-strong);
+ margin-bottom: 0.65rem;
+ padding-bottom: 0.5rem;
+ }
+ .ea-concept-band .ea-arch-canvas {
+ background: transparent;
+ border: 0;
+ margin: 0;
+ }
+ .ea-teaching-events {
+ border-left: 2px solid var(--ea-line-strong);
+ margin: 0.35rem 0 1rem 0.8rem;
+ }
+ .ea-teaching-event {
+ display: grid;
+ gap: 0.75rem;
+ grid-template-columns: 2.2rem minmax(0, 1fr);
+ padding: 0.55rem 0 0.65rem 0.7rem;
+ }
+ .ea-teaching-event > span {
+ color: var(--ea-muted);
+ font-family: ui-monospace, SFMono-Regular, Menlo, Consolas, monospace;
+ font-size: 0.68rem;
+ padding-top: 0.12rem;
+ }
+ .ea-teaching-event strong {
+ color: var(--ea-cyan);
+ font-family: ui-monospace, SFMono-Regular, Menlo, Consolas, monospace;
+ font-size: 0.68rem;
+ letter-spacing: 0.08em;
+ }
+ .ea-teaching-event b {
+ color: var(--ea-text);
+ font-size: 0.78rem;
+ margin-left: 0.6rem;
+ }
+ .ea-teaching-event p {
+ color: var(--ea-text-soft);
+ font-size: 0.8rem;
+ margin: 0.22rem 0 0;
+ overflow-wrap: anywhere;
+ }
+ .ea-live-progress {
+ background: var(--ea-surface);
+ border: 1px solid var(--ea-line-strong);
+ border-left: 3px solid var(--ea-cyan);
+ margin: 0.5rem 0 1rem;
+ padding: 0.75rem;
+ }
+ .ea-live-progress-head {
+ align-items: center;
+ border-bottom: 1px solid var(--ea-line);
+ display: flex;
+ justify-content: space-between;
+ padding-bottom: 0.55rem;
+ }
+ .ea-live-progress-head strong,
+ .ea-live-progress-head span,
+ .ea-live-progress-row > span {
+ font-family: ui-monospace, SFMono-Regular, Menlo, Consolas, monospace;
+ }
+ .ea-live-progress-head strong { color: var(--ea-cyan); font-size: 0.78rem; }
+ .ea-live-progress-head span { color: var(--ea-muted); font-size: 0.62rem; }
+ .ea-live-progress-row {
+ display: grid;
+ gap: 0.7rem;
+ grid-template-columns: 2rem minmax(0, 1fr);
+ padding: 0.55rem 0 0.15rem;
+ }
+ .ea-live-progress-row > span { color: var(--ea-muted); font-size: 0.65rem; }
+ .ea-live-progress-row strong { color: var(--ea-text); font-size: 0.78rem; }
+ .ea-live-progress-row p {
+ color: var(--ea-text-soft);
+ font-size: 0.78rem;
+ margin: 0.1rem 0 0;
+ overflow-wrap: anywhere;
+ }
+ .ea-live-progress-completed strong { color: var(--ea-lime); }
+ .ea-live-progress-warning strong { color: var(--ea-amber); }
+ .ea-live-progress-failed { border-left: 2px solid #ff8c8c; padding-left: 0.55rem; }
+ .ea-live-progress-failed strong { color: #ff8c8c; }
@media (prefers-reduced-motion: reduce) {
.ea-arch-node-wrap { animation: none; }
}
@@ -836,7 +969,7 @@ def inject_theme(st: Any) -> None:
border-radius: 8px;
display: grid;
gap: 0.45rem;
- grid-template-columns: repeat(8, minmax(0, 1fr));
+ grid-template-columns: repeat(9, minmax(0, 1fr));
margin: 0.75rem 0;
padding: 0.55rem;
}
@@ -1033,12 +1166,21 @@ def inject_theme(st: Any) -> None:
@media (max-width: 1200px) {
.main .block-container { padding: 1.2rem 1rem 3rem; }
.ea-title { font-size: 2rem; }
- .ea-run-metrics { grid-template-columns: repeat(2, minmax(0, 1fr)); }
+ .ea-run-metrics,
+ .ea-trace-metrics { grid-template-columns: repeat(2, minmax(0, 1fr)); }
.ea-run-state,
.ea-run-metric,
- .ea-run-id { border-right: 0; }
+ .ea-run-id,
+ .ea-trace-metrics > div { border-right: 0; }
}
@media (max-width: 900px) {
+ .ea-teaching-head {
+ align-items: flex-start;
+ flex-direction: column;
+ gap: 0.55rem;
+ }
+ .ea-teaching-head h2 { font-size: 1.3rem; }
+ .ea-concept-band { padding: 0.55rem; }
[data-testid="stExpandSidebarButton"] {
align-items: center !important;
background: var(--ea-surface-3) !important;
diff --git a/src/agentmold/visual/traces.py b/src/agentmold/visual/traces.py
index 0e9b046..18f4388 100644
--- a/src/agentmold/visual/traces.py
+++ b/src/agentmold/visual/traces.py
@@ -17,6 +17,7 @@
__all__ = [
"DEFAULT_VISUAL_TRACE_LOG",
"append_trace_run",
+ "build_trace_forest",
"diagnose_trace_run",
"find_trace_run",
"load_trace_runs",
@@ -24,6 +25,8 @@
"parse_trace_jsonl",
"summarize_usage",
"summarize_trace_run",
+ "trace_family_from_forest",
+ "trace_family_order",
"trace_label",
"traces_to_jsonl",
]
@@ -163,6 +166,90 @@ def merge_trace_runs(*collections: list[dict[str, Any]]) -> list[dict[str, Any]]
return [merged[run_id] for run_id in order]
+def build_trace_forest(runs: list[dict[str, Any]]) -> dict[str, Any]:
+ """Build a parent-child forest from a list of trace run dicts.
+
+ Returns a dict with:
+ - ``roots``: list of root run dicts (no parent or parent not in list)
+ - ``children``: dict mapping parent run_id to list of child run dicts
+ - ``orphans``: list of run dicts whose parent_run_id points to a missing run
+ - ``all_runs``: dict mapping run_id to run dict for fast lookup
+ """
+ all_runs: dict[str, dict[str, Any]] = {}
+ for run in runs:
+ run_id = run.get("run_id")
+ if isinstance(run_id, str) and run_id.strip():
+ all_runs[run_id] = run
+
+ roots: list[dict[str, Any]] = []
+ children: dict[str, list[dict[str, Any]]] = {}
+ orphans: list[dict[str, Any]] = []
+
+ for run in all_runs.values():
+ parent_id = run.get("parent_run_id")
+ if not parent_id:
+ roots.append(run)
+ elif parent_id in all_runs:
+ children.setdefault(str(parent_id), []).append(run)
+ else:
+ orphans.append(run)
+
+ # Sort children by started_at for deterministic ordering.
+ for child_list in children.values():
+ child_list.sort(key=lambda r: str(r.get("started_at") or ""))
+
+ return {
+ "roots": roots,
+ "children": children,
+ "orphans": orphans,
+ "all_runs": all_runs,
+ }
+
+
+def trace_family_from_forest(forest: dict[str, Any], run_id: str) -> list[dict[str, Any]]:
+ """Collect a run and all its descendants from a forest structure."""
+ family: list[dict[str, Any]] = []
+ all_runs = forest.get("all_runs", {})
+ children_map = forest.get("children", {})
+ seen: set[str] = set()
+
+ def walk(rid: str) -> None:
+ if rid in seen or rid not in all_runs:
+ return
+ seen.add(rid)
+ run = all_runs[rid]
+ family.append(run)
+ for child in children_map.get(rid, []):
+ child_id = child.get("run_id")
+ if isinstance(child_id, str):
+ walk(child_id)
+
+ walk(run_id)
+ return family
+
+
+def trace_family_order(forest: dict[str, Any]) -> list[tuple[str, int]]:
+ """Return run IDs in deterministic parent-before-child display order."""
+ ordered: list[tuple[str, int]] = []
+ seen: set[str] = set()
+ children_map = forest.get("children", {})
+
+ def walk(run: dict[str, Any], depth: int) -> None:
+ run_id = run.get("run_id")
+ if not isinstance(run_id, str) or run_id in seen:
+ return
+ seen.add(run_id)
+ ordered.append((run_id, depth))
+ for child in children_map.get(run_id, []):
+ walk(child, depth + 1)
+
+ for root in forest.get("roots", []):
+ walk(root, 0)
+ for orphan in forest.get("orphans", []):
+ walk(orphan, 0)
+ return ordered
+
+
def summarize_trace_run(run: dict[str, Any]) -> dict[str, Any]:
"""Return normalized fields used by replay, comparison, and metrics UI."""
raw_events = run.get("events")
@@ -204,7 +291,14 @@ def summarize_trace_run(run: dict[str, Any]) -> dict[str, Any]:
if isinstance(raw_child_run_ids, list)
else []
)
- status = "error" if run.get("error") else "complete" if run.get("ended_at") else "unknown"
+ raw_status = run.get("status")
+ status = (
+ str(raw_status)
+ if isinstance(raw_status, str) and raw_status
+ else "error" if run.get("error") else "complete" if run.get("ended_at") else "unknown"
+ )
+ raw_model_calls = run.get("model_calls")
+ rounds = len(raw_model_calls) if isinstance(raw_model_calls, list) else None
return {
"run_id": str(run.get("run_id", "")),
"parent_run_id": str(run.get("parent_run_id") or ""),
@@ -223,6 +317,7 @@ def summarize_trace_run(run: dict[str, Any]) -> dict[str, Any]:
"duration_ms": _number(run.get("duration_ms")),
**usage_summary,
"event_count": len(events),
+ "rounds": rounds,
"tool_calls": sum(event.get("type") == "tool_call" for event in events),
"status": status,
"error": str(run.get("error") or ""),
diff --git a/tests/test_async_agent.py b/tests/test_async_agent.py
index 10db199..7485230 100644
--- a/tests/test_async_agent.py
+++ b/tests/test_async_agent.py
@@ -50,6 +50,41 @@ async def slow_double(value: int) -> int:
assert await agent.arun("go") == "tool finished"
+@pytest.mark.asyncio
+async def test_arun_stream_yields_approval_and_structured_refusal():
+ class ConfirmingLLM(LLM):
+ def _complete(self, messages, tools=None):
+ if messages[-1].role == "tool":
+ return LlmResponse(content="refused")
+ return LlmResponse(
+ content="",
+ tool_calls=[{"id": "danger", "name": "erase", "arguments": {}}],
+ )
+
+ @tool(confirm=True)
+ async def erase() -> str:
+ """Represent a destructive async action."""
+ return "erased"
+
+ agent = Agent(
+ tools=[erase],
+ llm=ConfirmingLLM(model="confirm"),
+ log_level=LogLevel.SILENT,
+ )
+ events = [event async for event in agent.arun_stream("go")]
+
+ assert [event["type"] for event in events] == [
+ "tool_call",
+ "approval_request",
+ "tool_result",
+ "answer",
+ ]
+ assert events[2]["status"] == "refused"
+ assert events[0]["execution_id"] == events[2]["execution_id"]
+ assert agent.last_trace is not None
+ assert agent.last_trace.status == "completed"
+
+
@pytest.mark.asyncio
async def test_arun_stream_yields_transient_text_deltas():
class AsyncStreamingLLM(LLM):
diff --git a/tests/test_documentation.py b/tests/test_documentation.py
index 84fef06..ae4a1b1 100644
--- a/tests/test_documentation.py
+++ b/tests/test_documentation.py
@@ -71,6 +71,28 @@ def test_general_multi_agent_orchestration_is_not_a_pending_goal():
assert "explicit non-goals beyond v1.0" in roadmap
+def test_visual_architecture_lab_documents_runnable_fact_boundary():
+ readme = (ROOT / "README.md").read_text(encoding="utf-8")
+ architectures = (ROOT / "docs" / "architectures.md").read_text(encoding="utf-8")
+ capabilities = (ROOT / "docs" / "capabilities.md").read_text(encoding="utf-8")
+
+ for mode in ("ReAct", "Plan-and-Execute", "Reflection", "Multi-Agent", "Routing"):
+ assert mode in readme
+ assert mode in architectures
+ assert mode in capabilities
+ assert "概念示意 · 非本次运行" in readme
+ assert "TeachingEvent" in readme
+ assert "Agent 运行对比" in readme
+ assert "Coordinator、Researcher 和 Analyst" in readme
+ assert "默认使用" in readme and "真实模型执行" in readme
+ assert "确定性离线演示" in readme
+ assert "真实运行期间页面持续显示阶段进度" in readme
+ assert "Coordinator 委派、专家返回和最终综合" in readme
+ assert "ScriptedLLM" in architectures
+ assert "both specialist tool calls" in architectures
+ assert "General multi-Agent coordinator" in capabilities
+
+
def test_function_like_default_is_documented_as_silent():
readme = (ROOT / "README.md").read_text(encoding="utf-8")
api = (ROOT / "docs" / "api.md").read_text(encoding="utf-8")
diff --git a/tests/test_experiment.py b/tests/test_experiment.py
index 5857ae3..887c60d 100644
--- a/tests/test_experiment.py
+++ b/tests/test_experiment.py
@@ -6,7 +6,16 @@
import pytest
-from agentmold import Agent, EvalCase, LogLevel, aevaluate, evaluate
+from agentmold import (
+ Agent,
+ EvalCase,
+ EvalContext,
+ LogLevel,
+ MetricResult,
+ aevaluate,
+ evaluate,
+)
+from agentmold.llm import LLM
def _build_mock() -> Agent:
@@ -45,7 +54,11 @@ def test_evaluate_scores_expected_answers_and_exports(tmp_path):
json_path = report.to_json(tmp_path / "report.json")
payload = json.loads(json_path.read_text(encoding="utf-8"))
assert payload["summary"]["passed"] == 1
+ assert payload["summary"]["case_count"] == 2
+ assert payload["summary"]["sample_count"] == 2
+ assert payload["summary"]["metrics"]["score"]["pass_rate"] == 0.5
assert len(payload["results"]) == 2
+ assert payload["results"][0]["metrics"]["score"]["score"] == 1.0
jsonl_path = report.to_jsonl(tmp_path / "report.jsonl")
assert len(jsonl_path.read_text(encoding="utf-8").splitlines()) == 2
@@ -60,6 +73,120 @@ def broken_factory():
assert report.results[0].error == "RuntimeError: cannot build"
+def test_evaluate_preserves_failed_agent_trace():
+ class BrokenLLM(LLM):
+ def _complete(self, messages, tools=None):
+ raise RuntimeError("model failed")
+
+ def build() -> Agent:
+ return Agent(llm=BrokenLLM(model="broken"), log_level=LogLevel.SILENT)
+
+ report = evaluate(build, [EvalCase(input="x", expected="y")])
+
+ result = report.results[0]
+ assert result.error == "LLMError: BrokenLLM request failed: model failed"
+ assert result.trace is not None
+ assert result.runtime_status == "failed"
+ assert result.trace.model_calls[0]["status"] == "failed"
+
+
+def test_verifiers_receive_context_and_keep_metrics_separate():
+ seen: list[tuple[int, int, str]] = []
+
+ def goal_completion(context: EvalContext) -> MetricResult:
+ assert isinstance(context.agent, Agent)
+ assert context.trace is context.agent.last_trace
+ seen.append((context.case_index, context.sample_index, context.output))
+ return MetricResult(
+ score=0.8,
+ reason="four of five goals completed",
+ details={"completed": 4, "total": 5},
+ )
+
+ report = evaluate(
+ _build_mock,
+ [EvalCase(name="goals", input="alpha")],
+ verifiers={
+ "goal_completion": goal_completion,
+ "answered": lambda context: bool(context.output),
+ "not_applicable": lambda context: None,
+ },
+ )
+
+ result = report.results[0]
+ assert seen == [(0, 0, "[mock-llm] alpha")]
+ assert result.score is None
+ assert result.metrics["score"].reason == "case has no expected answer"
+ assert result.metrics["goal_completion"].score == 0.8
+ assert result.metrics["answered"].score == 1.0
+ assert result.metrics["not_applicable"].score is None
+ assert report.metric_summaries["goal_completion"]["mean_score"] == 0.8
+ assert report.metric_summaries["not_applicable"]["pass_rate"] is None
+
+
+def test_metric_failures_are_isolated_and_json_is_strict(tmp_path):
+ def broken(context: EvalContext) -> float:
+ raise RuntimeError("bad verifier")
+
+ report = evaluate(
+ _build_mock,
+ [EvalCase(input="alpha", expected="alpha", metadata={"bad": float("nan")})],
+ scorer=lambda output, expected: float("inf"),
+ verifiers={
+ "broken": broken,
+ "healthy": lambda context: True,
+ "non_finite": lambda context: float("nan"),
+ "invalid": lambda context: "wrong", # type: ignore[return-value]
+ },
+ )
+
+ result = report.results[0]
+ assert result.error is None
+ assert result.output == "[mock-llm] alpha"
+ assert result.trace is not None
+ assert result.metrics["score"].error == "ValueError: metric score must be finite"
+ assert result.metrics["broken"].error == "RuntimeError: bad verifier"
+ assert result.metrics["healthy"].score == 1.0
+ assert result.metrics["non_finite"].error == "ValueError: metric score must be finite"
+ assert "TypeError" in (result.metrics["invalid"].error or "")
+ payload = report.to_json(tmp_path / "strict.json").read_text(encoding="utf-8")
+ assert "NaN" not in payload
+ assert "Infinity" not in payload
+ assert json.loads(payload)["results"][0]["metadata"]["bad"] == "nan"
+
+
+def test_repeats_preserve_case_major_order_and_aggregate_pass_rates():
+ report = evaluate(
+ _build_mock,
+ [
+ EvalCase(name="one", input="one", expected="[mock-llm] one"),
+ EvalCase(name="two", input="two", expected="missing"),
+ ],
+ repeats=3,
+ workers=2,
+ )
+
+ assert report.case_count == 2
+ assert report.sample_count == 6
+ assert report.repeats == 3
+ assert [(result.case_index, result.sample_index) for result in report.results] == [
+ (0, 0),
+ (0, 1),
+ (0, 2),
+ (1, 0),
+ (1, 1),
+ (1, 2),
+ ]
+ run_ids = [result.trace.run_id for result in report.results if result.trace]
+ assert len(set(run_ids)) == 6
+ assert report.case_summaries[0]["metrics"]["score"]["pass_rate"] == 1.0
+ assert report.case_summaries[1]["metrics"]["score"]["pass_rate"] == 0.0
+ assert report.metric_summaries["score"]["pass_rate"] == 0.5
+ assert report.to_dict()["summary"]["mean_rounds"] == 1.0
+ assert report.to_dict()["summary"]["rounds_coverage"] == 1.0
+ assert report.to_dict()["summary"]["total_tokens_coverage"] == 0.0
+
+
@pytest.mark.asyncio
async def test_aevaluate_runs_cases_with_bounded_async_api():
report = await aevaluate(
@@ -75,8 +202,37 @@ async def test_aevaluate_runs_cases_with_bounded_async_api():
assert report.failed == 0
-def test_evaluate_validates_worker_count_and_case_types():
+@pytest.mark.asyncio
+async def test_sync_and_async_sampling_have_equivalent_aggregates():
+ cases = [EvalCase(input="one", expected="[mock-llm] one")]
+ verifiers = {"answered": lambda context: bool(context.output)}
+
+ sync_report = evaluate(_build_mock, cases, repeats=2, verifiers=verifiers)
+ async_report = await aevaluate(
+ _build_mock,
+ cases,
+ repeats=2,
+ verifiers=verifiers,
+ )
+
+ assert [
+ (result.case_index, result.sample_index, result.score) for result in sync_report.results
+ ] == [(result.case_index, result.sample_index, result.score) for result in async_report.results]
+ assert sync_report.metric_summaries == async_report.metric_summaries
+
+
+def test_evaluate_validates_configuration_and_case_types():
with pytest.raises(ValueError, match="workers"):
evaluate(_build_mock, ["x"], workers=0)
+ with pytest.raises(ValueError, match="repeats"):
+ evaluate(_build_mock, ["x"], repeats=0)
+ with pytest.raises(ValueError, match="pass_threshold"):
+ evaluate(_build_mock, ["x"], pass_threshold=float("nan"))
+ with pytest.raises(ValueError, match="non-empty"):
+ evaluate(_build_mock, ["x"], verifiers={"": lambda context: True})
+ with pytest.raises(ValueError, match="reserved"):
+ evaluate(_build_mock, ["x"], verifiers={"score": lambda context: True})
+ with pytest.raises(TypeError, match="callable"):
+ evaluate(_build_mock, ["x"], verifiers={"bad": 1}) # type: ignore[dict-item]
with pytest.raises(TypeError, match="Expected str or EvalCase"):
evaluate(_build_mock, [123]) # type: ignore[list-item]
diff --git a/tests/test_experimental.py b/tests/test_experimental.py
index 0f5d9f8..21c64ff 100644
--- a/tests/test_experimental.py
+++ b/tests/test_experimental.py
@@ -47,6 +47,31 @@ def test_agent_as_tool_is_explicit_and_has_a_normal_tool_schema():
assert not hasattr(agentmold, "agent_as_tool")
+def test_parent_trace_exports_complete_family(tmp_path):
+ from agentmold.visual.traces import parse_trace_jsonl
+
+ child = Agent(name="Export Child", llm="mock", log_level=LogLevel.SILENT)
+ parent = Agent(
+ name="Export Parent",
+ tools=[agent_as_tool(child)],
+ llm="mock",
+ log_level=LogLevel.SILENT,
+ )
+ parent.run("tool: inspect evidence")
+
+ assert parent.last_trace is not None
+ assert child.last_trace is not None
+ output = parent.last_trace.export_family(tmp_path / "family.jsonl")
+ runs = parse_trace_jsonl(output.read_text(encoding="utf-8"))
+
+ assert [run["run_id"] for run in runs] == [
+ parent.last_trace.run_id,
+ child.last_trace.run_id,
+ ]
+ assert runs[1]["parent_run_id"] == runs[0]["run_id"]
+ assert runs[0]["child_run_ids"] == [runs[1]["run_id"]]
+
+
def test_agent_as_tool_delegates_sync_and_preserves_child_trace():
child = Agent(name="Specialist", llm="mock", log_level=LogLevel.SILENT)
delegated = agent_as_tool(child, name="consult_specialist")
diff --git a/tests/test_run_stream.py b/tests/test_run_stream.py
index a74e877..16bbe88 100644
--- a/tests/test_run_stream.py
+++ b/tests/test_run_stream.py
@@ -182,6 +182,79 @@ def f() -> str:
assert "LoopDetectedError" in (agent.last_trace.error or "")
+def test_run_stream_records_refused_tool_intent_and_structured_outcome():
+ class ConfirmingLLM(LLM):
+ def _complete(self, messages, tools=None):
+ if messages[-1].role == "tool":
+ return LlmResponse(content="not executed")
+ return LlmResponse(
+ content="",
+ tool_calls=[{"id": "danger", "name": "erase", "arguments": {}}],
+ )
+
+ @tool(confirm=True)
+ def erase() -> str:
+ """Represent a destructive action without performing one."""
+ return "erased"
+
+ agent = Agent(
+ tools=[erase],
+ llm=ConfirmingLLM(model="confirm"),
+ log_level=LogLevel.SILENT,
+ )
+ events = list(agent.run_stream("go"))
+
+ assert [event["type"] for event in events] == [
+ "tool_call",
+ "approval_request",
+ "tool_result",
+ "answer",
+ ]
+ assert events[0]["execution_id"] == events[1]["execution_id"]
+ assert events[0]["execution_id"] == events[2]["execution_id"]
+ assert events[2]["status"] == "refused"
+ assert agent.last_trace is not None
+ assert [event["type"] for event in agent.last_trace.steps] == [
+ "tool_call",
+ "tool_result",
+ "answer",
+ ]
+
+
+def test_loop_trace_keeps_the_triggering_tool_call():
+ class AlwaysTool(LLM):
+ def _complete(self, messages, tools=None):
+ return LlmResponse(
+ content="",
+ tool_calls=[{"id": "loop", "name": "f", "arguments": {}}],
+ )
+
+ @tool
+ def f() -> str:
+ """A no-op tool."""
+ return "ok"
+
+ agent = Agent(
+ tools=[f],
+ llm=AlwaysTool(model="loop"),
+ log_level=LogLevel.SILENT,
+ loop_detection_threshold=2,
+ )
+ with pytest.raises(LoopDetectedError):
+ list(agent.run_stream("go"))
+
+ assert agent.last_trace is not None
+ assert [step["type"] for step in agent.last_trace.steps] == [
+ "tool_call",
+ "tool_result",
+ "tool_call",
+ "loop_detected",
+ ]
+ trigger_call, loop_event = agent.last_trace.steps[-2:]
+ assert trigger_call["execution_id"] == loop_event["execution_id"]
+ assert agent.last_trace.status == "failed"
+
+
def test_run_stream_distinct_arguments_do_not_trip_loop_guard():
"""Calls with different arguments count as progress and never trip."""
diff --git a/tests/test_trace.py b/tests/test_trace.py
index 750afca..c32acb7 100644
--- a/tests/test_trace.py
+++ b/tests/test_trace.py
@@ -158,6 +158,84 @@ def _complete(self, messages, tools=None):
assert config["default_headers"]["Authorization"] == ""
+def test_trace_v2_records_model_rounds_and_structured_tool_outcomes():
+ class FailingToolLLM(LLM):
+ def _complete(self, messages, tools=None):
+ if messages[-1].role == "tool":
+ return LlmResponse(content="recovered")
+ return LlmResponse(
+ content="",
+ tool_calls=[{"id": "bad-call", "name": "explode", "arguments": {"value": 3}}],
+ raw={"usage": {"total_tokens": 4}},
+ )
+
+ @tool
+ def explode(value: int) -> str:
+ """Raise a deterministic tool failure."""
+ raise RuntimeError(f"bad value {value}")
+
+ agent = Agent(
+ tools=[explode],
+ llm=FailingToolLLM(model="trace-v2"),
+ log_level=LogLevel.SILENT,
+ )
+
+ assert agent.run("go") == "recovered"
+ assert agent.last_trace is not None
+ trace = agent.last_trace
+ payload = trace.to_dict()
+ assert payload["trace_version"] == 2
+ assert payload["status"] == "completed"
+ assert [call["round"] for call in payload["model_calls"]] == [1, 2]
+ assert [call["response_kind"] for call in payload["model_calls"]] == [
+ "tool_calls",
+ "answer",
+ ]
+ assert payload["model_calls"][0]["usage"] == {"total_tokens": 4}
+
+ call_event, result_event, answer_event = trace.steps
+ assert call_event["round"] == result_event["round"] == 1
+ assert call_event["execution_id"] == result_event["execution_id"]
+ assert call_event["call_index"] == result_event["call_index"] == 1
+ assert result_event["status"] == "error"
+ assert result_event["error_type"] == "ToolError"
+ assert result_event["duration_ms"] >= 0
+ assert answer_event["round"] == 2
+
+
+def test_trace_takes_a_stable_snapshot_of_tool_arguments():
+ class MutatingLLM(LLM):
+ def _complete(self, messages, tools=None):
+ if messages[-1].role == "tool":
+ return LlmResponse(content="done")
+ return LlmResponse(
+ content="",
+ tool_calls=[
+ {
+ "id": "mutate",
+ "name": "mutate",
+ "arguments": {"payload": {"items": ["original"]}},
+ }
+ ],
+ )
+
+ @tool
+ def mutate(payload: dict[str, list[str]]) -> str:
+ """Mutate a nested argument to test trace isolation."""
+ payload["items"].append("changed")
+ return "ok"
+
+ agent = Agent(
+ tools=[mutate],
+ llm=MutatingLLM(model="snapshot"),
+ log_level=LogLevel.SILENT,
+ )
+ agent.run("go")
+
+ assert agent.last_trace is not None
+ assert agent.last_trace.tool_calls[0]["arguments"] == {"payload": {"items": ["original"]}}
+
+
def test_audit_log_write_failure_does_not_crash_run(tmp_path):
"""A failing audit-log write must degrade, not abort, the agent run.
diff --git a/tests/test_visual_app.py b/tests/test_visual_app.py
new file mode 100644
index 0000000..2d0a9e0
--- /dev/null
+++ b/tests/test_visual_app.py
@@ -0,0 +1,246 @@
+"""Streamlit AppTest coverage for the architecture-first visual lab."""
+
+from __future__ import annotations
+
+import pytest
+
+from agentmold.visual.live_teaching import ProgressEvent
+from agentmold.visual.teaching import run_teaching_experiment
+from agentmold.visual.teaching_models import LiveTeachingModel
+
+streamlit_testing = pytest.importorskip("streamlit.testing.v1")
+AppTest = streamlit_testing.AppTest
+
+
+def _select_offline_mode(app) -> None:
+ execution = next(item for item in app.radio if item.label == "执行方式")
+ execution.set_value("确定性离线演示").run()
+
+
+def test_live_mode_does_not_fall_back_to_scripted_execution(monkeypatch) -> None:
+ monkeypatch.setattr(
+ "agentmold.visual.teaching_view.load_live_teaching_models",
+ lambda: ([], []),
+ )
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+
+ app.run()
+ app.segmented_control[0].select("Multi-Agent").run()
+
+ execution = next(item for item in app.radio if item.label == "执行方式")
+ live_button = next(button for button in app.button if button.label == "运行真实架构")
+ assert execution.value == "真实模型执行"
+ assert live_button.disabled is True
+ assert any(button.label == "去 ReAct 配置模型" for button in app.button)
+ assert "teaching.multi_agent.live.result" not in app.session_state
+
+
+def test_live_mode_passes_saved_model_to_live_runner(monkeypatch) -> None:
+ model = LiveTeachingModel(
+ key="OpenAI 兼容",
+ label="OpenAI 兼容 · openai / test-model",
+ config={"provider": "openai", "model": "test-model", "api_key": "secret"},
+ )
+ captured: dict[str, object] = {}
+
+ def fake_live_runner(mode, user_input, build_llm, *, on_progress=None):
+ captured.update(mode=mode, user_input=user_input, llm=build_llm())
+ assert on_progress is not None
+ on_progress(ProgressEvent("routing", "Router", "正在判断任务类型"))
+ on_progress(
+ ProgressEvent(
+ "completed",
+ "Coder",
+ "Coder 已生成最终回答",
+ "completed",
+ )
+ )
+ experiment = run_teaching_experiment(mode, user_input)
+ experiment.metadata["execution_mode"] = "live"
+ return experiment
+
+ monkeypatch.setattr(
+ "agentmold.visual.teaching_view.load_live_teaching_models",
+ lambda: ([model], []),
+ )
+ monkeypatch.setattr(
+ "agentmold.visual.teaching_view.run_live_teaching_experiment",
+ fake_live_runner,
+ )
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+
+ app.run()
+ app.segmented_control[0].select("Routing").run()
+ next(button for button in app.button if button.label == "运行真实架构").click().run()
+
+ assert not app.exception
+ assert captured == {
+ "mode": "routing",
+ "user_input": "请用 Python 写一个去重函数",
+ "llm": {"provider": "openai", "model": "test-model", "api_key": "secret"},
+ }
+ experiment = app.session_state["teaching.routing.live.result"]
+ assert experiment.metadata["execution_mode"] == "live"
+ assert experiment.metadata["model_profile"] == "OpenAI 兼容"
+ assert "secret" not in experiment.metadata["model_label"]
+ assert [event["stage"] for event in experiment.metadata["progress"]] == [
+ "routing",
+ "completed",
+ ]
+ progress_html = "\n".join(item.value for item in app.markdown)
+ assert "实时运行过程" in progress_html
+ assert "正在判断任务类型" in progress_html
+ assert "Coder 已生成最终回答" in progress_html
+
+
+def test_live_mode_surfaces_progress_when_runner_fails(monkeypatch) -> None:
+ model = LiveTeachingModel(
+ key="OpenAI 兼容",
+ label="OpenAI 兼容 · openai / test-model",
+ config={"provider": "openai", "model": "test-model"},
+ )
+
+ def failing_runner(mode, user_input, build_llm, *, on_progress=None):
+ assert on_progress is not None
+ on_progress(ProgressEvent("planning", "Planner", "正在生成可执行计划"))
+ raise RuntimeError("provider unavailable")
+
+ monkeypatch.setattr(
+ "agentmold.visual.teaching_view.load_live_teaching_models",
+ lambda: ([model], []),
+ )
+ monkeypatch.setattr(
+ "agentmold.visual.teaching_view.run_live_teaching_experiment",
+ failing_runner,
+ )
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+
+ app.run()
+ app.segmented_control[0].select("Plan-and-Execute").run()
+ next(button for button in app.button if button.label == "运行真实架构").click().run()
+
+ assert not app.exception
+ progress_html = "\n".join(item.value for item in app.markdown)
+ assert "执行失败" in progress_html
+ assert "provider unavailable" in progress_html
+ assert "teaching.plan_execute.live.result" not in app.session_state
+
+
+def test_react_sidebar_has_direct_advanced_safety_controls() -> None:
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+
+ app.run()
+
+ assert not app.exception
+ assert all(selectbox.label != "策略预设" for selectbox in app.selectbox)
+ assert any(expander.label == "运行限制与安全(高级)" for expander in app.expander)
+ assert any(checkbox.label == "拒绝需要确认的工具" for checkbox in app.checkbox)
+
+
+@pytest.mark.parametrize(
+ ("label", "mode", "trace_count"),
+ [
+ ("Plan-and-Execute", "plan_execute", 5),
+ ("Reflection", "reflection", 4),
+ ("Multi-Agent", "multi_agent", 3),
+ ("Routing", "routing", 2),
+ ],
+)
+def test_offline_teaching_modes_run_without_a_react_agent(
+ label: str,
+ mode: str,
+ trace_count: int,
+) -> None:
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+
+ app.run()
+ assert not app.exception
+ navigation = app.segmented_control[0]
+ assert navigation.options == [
+ "ReAct",
+ "Plan-and-Execute",
+ "Reflection",
+ "Multi-Agent",
+ "Routing",
+ ]
+
+ navigation.select(label).run()
+ assert not app.exception
+ assert app.session_state["ea_architecture_mode"] == mode
+ assert next(item for item in app.radio if item.label == "执行方式").value == "真实模型执行"
+
+ _select_offline_mode(app)
+ assert [button.label for button in app.button][-2:] == ["运行离线演示", "重置"]
+
+ next(button for button in app.button if button.label == "运行离线演示").click().run()
+ assert not app.exception
+ experiment = app.session_state[f"teaching.{mode}.offline.result"]
+ assert experiment.mode == mode
+ assert len(experiment.traces) == trace_count
+ assert len(app.get("download_button")) == 3
+
+
+def test_switching_architectures_preserves_each_experiment_state() -> None:
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+ custom_input = "Design a three-step offline research workflow"
+
+ app.run()
+ app.segmented_control[0].select("Plan-and-Execute").run()
+ _select_offline_mode(app)
+ app.text_area[0].set_value(custom_input)
+ next(button for button in app.button if button.label == "运行离线演示").click().run()
+ plan_result = app.session_state["teaching.plan_execute.offline.result"]
+
+ app.segmented_control[0].select("Reflection").run()
+ assert app.text_area[0].value != custom_input
+ app.segmented_control[0].select("Plan-and-Execute").run()
+
+ assert app.text_area[0].value == custom_input
+ assert app.session_state["teaching.plan_execute.offline.result"] is plan_result
+ assert len(app.expander) == 5
+
+
+def test_teaching_traces_flow_into_replay_and_evaluation_views() -> None:
+ app = AppTest.from_file("src/agentmold/visual/app.py", default_timeout=20)
+
+ app.run()
+ app.segmented_control[0].select("Multi-Agent").run()
+ _select_offline_mode(app)
+ next(button for button in app.button if button.label == "运行离线演示").click().run()
+ assert len(app.session_state["trace_runs"]) == 3
+
+ next(button for button in app.button if button.label == "运行回放").click().run()
+ assert not app.exception
+ assert app.session_state["ea_visual_view"] == "trace"
+ assert any(item.value == "## 运行回放" for item in app.markdown)
+
+ next(button for button in app.button if button.label == "对比与评测").click().run()
+ assert not app.exception
+ assert app.session_state["ea_visual_view"] == "evaluation"
+ assert any(item.value == "## 对比与评测" for item in app.markdown)
+ assert [tab.label for tab in app.tabs] == ["Agent 运行对比", "批量回归"]
+ assert len(app.multiselect[0].value) == 3
+ assert len(app.dataframe) == 1
+ assert [download.label for download in app.get("download_button")] == [
+ "下载对比 JSON",
+ "下载所选 Trace JSONL",
+ ]
+ assert any("协调 Agent" in expander.label for expander in app.expander)
+ assert sum("子 Agent" in expander.label for expander in app.expander) == 2
+
+ next(button for button in app.button if button.label == "运行批量回归").click().run()
+ assert not app.exception
+ report = app.session_state["ea_eval_report"]
+ assert report["summary"]["sample_count"] == 6
+ assert report["summary"]["metrics"]["score"]["pass_rate"] == 1.0
+
+ next(button for button in app.button if button.label == "架构实验").click().run()
+ assert not app.exception
+ assert app.session_state["ea_visual_view"] == "architecture"
+ assert app.session_state["ea_architecture_mode"] == "multi_agent"
+
+ next(button for button in app.button if button.label == "比较这些 Agent").click().run()
+ assert not app.exception
+ assert app.session_state["ea_visual_view"] == "evaluation"
+ assert len(app.multiselect[0].value) == 3
+ assert app.session_state["teaching.multi_agent.offline.result"].mode == "multi_agent"
diff --git a/tests/test_visual_architecture.py b/tests/test_visual_architecture.py
index 411ea0e..0037606 100644
--- a/tests/test_visual_architecture.py
+++ b/tests/test_visual_architecture.py
@@ -6,28 +6,30 @@
from agentmold.visual.architecture import (
ARCHITECTURE_PRESETS,
+ INTENT_PRESETS,
+ RETRIEVAL_PRESETS,
TOOL_CALLING_PRESETS,
architecture_code,
architecture_description,
architecture_diagram_html,
- tool_calling_description,
- tool_calling_diagram_html,
-)
-from agentmold.visual.architecture import (
- INTENT_PRESETS,
- RETRIEVAL_PRESETS,
intent_code,
intent_description,
intent_diagram_html,
retrieval_code,
retrieval_description,
retrieval_diagram_html,
+ tool_calling_description,
+ tool_calling_diagram_html,
)
@pytest.mark.parametrize("arch_key", list(ARCHITECTURE_PRESETS))
def test_every_preset_has_required_fields(arch_key):
preset = ARCHITECTURE_PRESETS[arch_key]
+ assert preset["architecture_id"]
+ assert preset["sample_input"]
+ assert preset["runner_key"]
+ assert preset["run_status"] in {"shipped", "experimental"}
assert preset["title"]
assert preset["summary"]
assert isinstance(preset["nodes"], list) and len(preset["nodes"]) >= 3
@@ -71,6 +73,27 @@ def test_code_snippets_are_importable_python():
ast.parse(code) # raises SyntaxError if invalid
+def test_multi_agent_preset_is_explicitly_experimental():
+ preset = ARCHITECTURE_PRESETS["Multi-Agent(多智能体协作)"]
+ code = architecture_code("Multi-Agent(多智能体协作)")
+ summary = architecture_description("Multi-Agent(多智能体协作)")
+
+ assert preset["run_status"] == "experimental"
+ assert "run_multi_agent_experiment" in code
+ assert "API 可能变化" in code
+ assert "没有 Coordinator 类" in summary
+
+
+def test_architecture_presets_do_not_invent_orchestrator_classes():
+ combined = "\n".join(
+ str(preset["summary"]) + "\n" + str(preset["code"])
+ for preset in ARCHITECTURE_PRESETS.values()
+ )
+ assert "Coordinator(" not in combined
+ assert "Router(" not in combined
+ assert "class Coordinator" not in combined
+
+
# ---------------------------------------------------------------------------
# Tool calling mode presets
# ---------------------------------------------------------------------------
diff --git a/tests/test_visual_graph.py b/tests/test_visual_graph.py
index e9ca0a5..1c03c27 100644
--- a/tests/test_visual_graph.py
+++ b/tests/test_visual_graph.py
@@ -2,12 +2,15 @@
from types import SimpleNamespace
+from agentmold import Agent, LogLevel
+from agentmold.experimental import agent_as_tool
from agentmold.visual.agent_config import (
CONNECTION_DEFAULTS as _CONNECTION_DEFAULTS,
)
from agentmold.visual.agent_config import (
agent_signature as _agent_signature,
)
+from agentmold.visual.agent_config import bind_visual_tools, visual_approval_gate
from agentmold.visual.agent_config import (
build_agent as _build_agent,
)
@@ -20,7 +23,6 @@
from agentmold.visual.agent_config import (
load_visual_tools as _load_visual_tools,
)
-from agentmold.visual.agent_config import bind_visual_tools, resolve_mode, visual_approval_gate
from agentmold.visual.app import (
_description_widget_key,
_inject_theme,
@@ -36,12 +38,14 @@
from agentmold.visual.renderers import (
initial_run_meta as _initial_run_meta,
)
+from agentmold.visual.renderers import remember_trace as _remember_trace
from agentmold.visual.renderers import (
run_metrics_html as _run_metrics_html,
)
from agentmold.visual.renderers import (
timeline_html as _timeline_html,
)
+from agentmold.visual.renderers import trace_breadcrumb_html as _trace_breadcrumb_html
def test_empty_steps_produces_no_nodes():
@@ -154,7 +158,6 @@ def remote_lookup(query: str) -> str:
assert bound[0].confirm is True
assert remote_lookup.confirm is False
-
before = _agent_signature("A", "prompt", "mock", ["calculate"], 10)
after = _agent_signature(
"A",
@@ -166,7 +169,6 @@ def remote_lookup(query: str) -> str:
)
assert before != after
-
before = _agent_signature("A", "old", "mock", ["calculate"], 10)
after = _agent_signature("A", "new", "mock", ["calculate"], 10)
assert before != after
@@ -178,16 +180,10 @@ def test_agent_signature_changes_with_uploaded_tool_content():
assert before != after
-def test_visual_config_keeps_legacy_log_level_keyword_compatible():
- resolved = resolve_mode("标准模式", 8, True, True, log_level="DEBUG")
+def test_visual_config_keeps_log_level_out_of_agent_signature():
before = _agent_signature("A", "prompt", "mock", [], 10, log_level="INFO")
after = _agent_signature("A", "prompt", "mock", [], 10, log_level="DEBUG")
- assert resolved == {
- "loop_detection_threshold": 3,
- "require_approval": False,
- "audit_log": False,
- }
assert before == after
@@ -203,7 +199,6 @@ def test_reset_visual_conversation_clears_memory_but_preserves_agent_tools():
"last_steps": [{"type": "answer", "content": "old answer"}],
"last_user_input": "old question",
"run_meta": {"state": "complete"},
- "ea_agent_mode": "标准模式",
"ea_rag_text": "keep document",
}
st = SimpleNamespace(session_state=state)
@@ -215,7 +210,7 @@ def test_reset_visual_conversation_clears_memory_but_preserves_agent_tools():
("system", agent._build_system_prompt())
]
assert [tool.name for tool in agent.tools] == ["calculate"]
- assert state == {"ea_agent_mode": "标准模式", "ea_rag_text": "keep document"}
+ assert state == {"ea_rag_text": "keep document"}
def test_tool_origin_groups_unknown_sources_as_other():
@@ -240,13 +235,13 @@ def dangerous_tool(value: str) -> str:
return value
tools = {"safe_tool": safe_tool, "dangerous_tool": dangerous_tool}
- assert _tool_group_summary(
- "内置工具", list(tools), {"safe_tool"}, tools
- ) == "内置工具 · 1/2 已选 · ⚠ 1"
+ assert (
+ _tool_group_summary("内置工具", list(tools), {"safe_tool"}, tools)
+ == "内置工具 · 1/2 已选 · ⚠ 1"
+ )
assert _description_widget_key("retrieve").startswith("ea_tool_description_")
assert _description_widget_key("retrieve") == _description_widget_key("retrieve")
-
assert _one_line_description("Read files.\n\nOnly inside workspace.") == (
"Read files. Only inside workspace."
)
@@ -295,6 +290,37 @@ def test_visual_tool_loader_rejects_name_conflicts(tmp_path):
assert "工具名冲突" in errors[0]
+def test_remember_trace_persists_parent_and_child(monkeypatch, tmp_path):
+ child = Agent(name="Child", llm="mock", log_level=LogLevel.SILENT)
+ parent = Agent(
+ name="Parent",
+ tools=[agent_as_tool(child)],
+ llm="mock",
+ log_level=LogLevel.SILENT,
+ )
+ parent.run("tool: inspect evidence")
+ assert parent.last_trace is not None
+ assert child.last_trace is not None
+
+ written: list[str] = []
+
+ def record(run):
+ written.append(str(run["run_id"]))
+ return tmp_path / "visual_runs.jsonl"
+
+ class SessionState(dict):
+ __getattr__ = dict.__getitem__
+ __setattr__ = dict.__setitem__
+
+ monkeypatch.setattr("agentmold.visual.renderers.append_trace_run", record)
+ st = SimpleNamespace(session_state=SessionState())
+ _remember_trace(st, parent.last_trace)
+
+ assert written == [parent.last_trace.run_id, child.last_trace.run_id]
+ assert [run["run_id"] for run in st.session_state.trace_runs] == written
+ assert st.session_state.ea_logged_trace_ids == sorted(written)
+
+
def test_timeline_renders_events_and_escapes_content():
timeline = _timeline_html(
[
@@ -310,6 +336,19 @@ def test_timeline_renders_events_and_escapes_content():
assert "" not in timeline
+def test_trace_breadcrumb_escapes_family_labels():
+ rendered = _trace_breadcrumb_html(
+ {"run_id": "current", "agent_name": ""},
+ {"run_id": "parent", "agent_name": "Parent & Root"},
+ [{"run_id": "child", "agent_name": "Child > Worker"}],
+ )
+
+ assert "Parent & Root" in rendered
+ assert "<Current>" in rendered
+ assert "Child > Worker" in rendered
+ assert "" not in rendered
+
+
def test_timeline_empty_state_is_stable():
assert "暂无执行事件" in _timeline_html([])
diff --git a/tests/test_visual_live_teaching.py b/tests/test_visual_live_teaching.py
new file mode 100644
index 0000000..b611b2d
--- /dev/null
+++ b/tests/test_visual_live_teaching.py
@@ -0,0 +1,288 @@
+"""Contracts for live-model architecture teaching experiments."""
+
+from __future__ import annotations
+
+from collections import deque
+from collections.abc import Iterable
+
+import pytest
+
+from agentmold.llm import LlmResponse
+from agentmold.visual.live_teaching import (
+ ProgressEvent,
+ run_live_multi_agent_experiment,
+ run_live_plan_execute_experiment,
+ run_live_reflection_experiment,
+ run_live_routing_experiment,
+ run_live_teaching_experiment,
+)
+from agentmold.visual.teaching import ScriptedLLM
+
+
+class LLMFactory:
+ """Return explicit per-Agent LLM instances in construction order."""
+
+ def __init__(self, scripts: Iterable[Iterable[LlmResponse]]) -> None:
+ self.scripts = deque(scripts)
+
+ def __call__(self) -> ScriptedLLM:
+ try:
+ responses = self.scripts.popleft()
+ except IndexError as exc:
+ raise AssertionError("Unexpected Agent construction") from exc
+ return ScriptedLLM(responses, model="live-test")
+
+
+def test_live_plan_output_drives_worker_runs_and_synthesis() -> None:
+ factory = LLMFactory(
+ [
+ [LlmResponse(content="1. Inspect the corpus\n2. Measure retrieval quality")],
+ [LlmResponse(content="Corpus contains 12 documents")],
+ [LlmResponse(content="Recall@5 is 0.80")],
+ [LlmResponse(content="Use the 12-document corpus; baseline Recall@5 is 0.80")],
+ ]
+ )
+
+ progress: list[ProgressEvent] = []
+ experiment = run_live_plan_execute_experiment(
+ "Evaluate retrieval",
+ factory,
+ on_progress=progress.append,
+ )
+
+ assert [event.stage for event in progress] == [
+ "planning",
+ "plan_created",
+ "step_started",
+ "step_completed",
+ "step_started",
+ "step_completed",
+ "synthesis",
+ "completed",
+ ]
+ assert experiment.metadata["plan"] == [
+ "Inspect the corpus",
+ "Measure retrieval quality",
+ ]
+ assert [trace.agent_name for trace in experiment.traces] == [
+ "Planner",
+ "Worker 1",
+ "Worker 2",
+ "Synthesizer",
+ ]
+ assert [trace.user_input for trace in experiment.traces[1:3]] == experiment.metadata["plan"]
+ assert experiment.output == "Use the 12-document corpus; baseline Recall@5 is 0.80"
+ assert not factory.scripts
+
+
+def test_live_plan_rejects_unusable_model_plan() -> None:
+ factory = LLMFactory([[LlmResponse(content="I might think about it later")]])
+
+ with pytest.raises(RuntimeError, match="Planner must return 2-5 steps"):
+ run_live_plan_execute_experiment("Evaluate retrieval", factory)
+
+
+def test_live_reflection_feedback_and_done_drive_bounded_loop() -> None:
+ factory = LLMFactory(
+ [
+ [
+ LlmResponse(content="Vectors find similar text."),
+ LlmResponse(
+ content="Embeddings map text to vectors; cosine similarity ranks passages."
+ ),
+ ],
+ [
+ LlmResponse(content="Explain embeddings and the similarity measure."),
+ LlmResponse(content="DONE"),
+ ],
+ ]
+ )
+
+ progress: list[ProgressEvent] = []
+ experiment = run_live_reflection_experiment(
+ "Explain vector retrieval",
+ factory,
+ on_progress=progress.append,
+ )
+
+ assert [event.stage for event in progress] == [
+ "generation",
+ "draft_created",
+ "critique",
+ "feedback_received",
+ "revision",
+ "revision_created",
+ "critique",
+ "reflection_done",
+ ]
+ assert experiment.metadata == {
+ "execution_mode": "live",
+ "feedback_rounds": 1,
+ "critic_status": "DONE",
+ "max_revisions": 2,
+ }
+ assert [trace.agent_name for trace in experiment.traces] == [
+ "Generator",
+ "Critic",
+ "Generator",
+ "Critic",
+ ]
+ assert [event.type for event in experiment.events] == [
+ "generation_started",
+ "draft_created",
+ "feedback_received",
+ "revision_created",
+ "reflection_done",
+ ]
+
+
+def test_live_reflection_stops_at_revision_limit() -> None:
+ factory = LLMFactory(
+ [
+ [LlmResponse(content="Draft"), LlmResponse(content="Revision")],
+ [LlmResponse(content="Improve it")],
+ ]
+ )
+
+ experiment = run_live_reflection_experiment("Write clearly", factory, max_revisions=1)
+
+ assert experiment.output == "Revision"
+ assert experiment.metadata["critic_status"] == "revision_limit"
+ assert experiment.events[-1].type == "reflection_limit_reached"
+
+
+@pytest.mark.parametrize(
+ ("router_output", "expected_expert"),
+ [("Coder", "Coder"), ("The best route is Writer.", "Writer"), ("MATH", "Math")],
+)
+def test_live_router_output_selects_only_one_expert(
+ router_output: str,
+ expected_expert: str,
+) -> None:
+ factory = LLMFactory(
+ [
+ [LlmResponse(content=router_output)],
+ [LlmResponse(content=f"Handled by {expected_expert}")],
+ ]
+ )
+
+ progress: list[ProgressEvent] = []
+ experiment = run_live_routing_experiment(
+ "Handle this task",
+ factory,
+ on_progress=progress.append,
+ )
+
+ assert [event.stage for event in progress] == [
+ "routing",
+ "route_selected",
+ "expert_started",
+ "completed",
+ ]
+ assert experiment.metadata["route_selected"] == expected_expert
+ assert experiment.output == f"Handled by {expected_expert}"
+ assert not factory.scripts
+
+
+def test_live_router_rejects_ambiguous_selection() -> None:
+ factory = LLMFactory([[LlmResponse(content="Coder or Writer")]])
+
+ with pytest.raises(RuntimeError, match="exactly one"):
+ run_live_routing_experiment("Handle this task", factory)
+
+
+def test_live_multi_agent_requires_real_tool_delegations_for_child_traces() -> None:
+ factory = LLMFactory(
+ [
+ [LlmResponse(content="Research found exact-match evidence")],
+ [LlmResponse(content="Analysis found semantic-recall trade-offs")],
+ [
+ LlmResponse(
+ content="",
+ tool_calls=[
+ {
+ "id": "live-research",
+ "name": "consult_researcher",
+ "arguments": {"request": "Find exact retrieval evidence"},
+ },
+ {
+ "id": "live-analysis",
+ "name": "consult_analyst",
+ "arguments": {"request": "Analyze semantic trade-offs"},
+ },
+ ],
+ ),
+ LlmResponse(content="Combine keyword precision with vector recall."),
+ ],
+ ]
+ )
+
+ progress: list[ProgressEvent] = []
+ experiment = run_live_multi_agent_experiment(
+ "Compare retrieval methods",
+ factory,
+ on_progress=progress.append,
+ )
+ parent, researcher, analyst = experiment.traces
+
+ assert [event.stage for event in progress] == [
+ "coordination",
+ "delegation_started",
+ "delegation_started",
+ "delegation_completed",
+ "delegation_completed",
+ "completed",
+ ]
+ assert experiment.metadata == {
+ "execution_mode": "live",
+ "delegated_tools": ["consult_researcher", "consult_analyst"],
+ "delegation_count": 2,
+ "child_run_count": 2,
+ "used_both_specialists": True,
+ }
+ assert [trace.agent_name for trace in experiment.traces] == [
+ "Coordinator",
+ "Researcher",
+ "Analyst",
+ ]
+ assert parent.child_run_ids == [researcher.run_id, analyst.run_id]
+ assert researcher.parent_run_id == parent.run_id
+ assert analyst.parent_run_id == parent.run_id
+ assert researcher.parent_tool_call_id == "live-research"
+ assert analyst.parent_tool_call_id == "live-analysis"
+ assert len({call["parallel_group"] for call in parent.tool_calls}) == 1
+ assert not factory.scripts
+
+
+def test_live_multi_agent_observes_missing_delegation_instead_of_faking_children() -> None:
+ factory = LLMFactory(
+ [
+ [LlmResponse(content="unused research")],
+ [LlmResponse(content="unused analysis")],
+ [LlmResponse(content="I answered without delegation")],
+ ]
+ )
+
+ experiment = run_live_multi_agent_experiment("Compare retrieval methods", factory)
+
+ assert [trace.agent_name for trace in experiment.traces] == ["Coordinator"]
+ assert experiment.metadata["delegation_count"] == 0
+ assert experiment.metadata["child_run_count"] == 0
+ assert experiment.metadata["used_both_specialists"] is False
+
+
+def test_live_dispatch_and_export_source_are_explicit() -> None:
+ factory = LLMFactory(
+ [
+ [LlmResponse(content="Writer")],
+ [LlmResponse(content="A polished paragraph")],
+ ]
+ )
+
+ experiment = run_live_teaching_experiment("routing", "Draft a paragraph", factory)
+
+ assert experiment.mode == "routing"
+ assert "EASYAGENT_LLM_CONFIG" in experiment.source_code
+ compile(experiment.source_code, "", "exec")
+ with pytest.raises(ValueError, match="Live execution is unavailable"):
+ run_live_teaching_experiment("react", "Hello", factory)
diff --git a/tests/test_visual_navigation.py b/tests/test_visual_navigation.py
new file mode 100644
index 0000000..0ad6cd4
--- /dev/null
+++ b/tests/test_visual_navigation.py
@@ -0,0 +1,110 @@
+"""Tests for architecture-first visual navigation."""
+
+from __future__ import annotations
+
+from agentmold.visual.app import _ARCHITECTURE_NAV, _render_top_navigation
+
+
+class _SessionState(dict):
+ __getattr__ = dict.__getitem__
+ __setattr__ = dict.__setitem__
+
+
+class _Column:
+ def __init__(self, clicked: bool = False) -> None:
+ self.clicked = clicked
+
+ def button(self, *args, **kwargs):
+ return self.clicked
+
+ def caption(self, *args, **kwargs):
+ return None
+
+
+class _NavigationStub:
+ def __init__(
+ self,
+ *,
+ selected: str,
+ architecture: bool = False,
+ replay: bool = False,
+ evaluation: bool = False,
+ ):
+ self.session_state = _SessionState()
+ self.selected = selected
+ self.columns_value = [
+ _Column(architecture),
+ _Column(replay),
+ _Column(evaluation),
+ _Column(),
+ ]
+ self.rerun_called = False
+
+ def radio(self, *args, **kwargs):
+ return self.selected
+
+ def columns(self, *args, **kwargs):
+ return self.columns_value
+
+ def rerun(self):
+ self.rerun_called = True
+
+
+class _SegmentedNavigationStub(_NavigationStub):
+ def segmented_control(self, *args, **kwargs):
+ return None
+
+
+def test_architecture_navigation_has_stable_order():
+ assert list(_ARCHITECTURE_NAV) == [
+ "react",
+ "plan_execute",
+ "reflection",
+ "multi_agent",
+ "routing",
+ ]
+
+
+def test_empty_segmented_selection_keeps_current_architecture():
+ st = _SegmentedNavigationStub(selected="unused")
+ st.session_state.ea_architecture_mode = "multi_agent"
+
+ view, architecture = _render_top_navigation(st)
+
+ assert view == "architecture"
+ assert architecture == "multi_agent"
+ assert st.session_state.ea_architecture_mode == "multi_agent"
+
+
+def test_navigation_falls_back_to_horizontal_radio():
+ st = _NavigationStub(selected="Multi-Agent")
+
+ view, architecture = _render_top_navigation(st)
+
+ assert view == "architecture"
+ assert architecture == "multi_agent"
+ assert st.session_state.ea_architecture_mode == "multi_agent"
+ assert st.session_state.ea_visual_view == "architecture"
+
+
+def test_research_tool_navigation_is_independent_of_architecture():
+ st = _NavigationStub(selected="Reflection", replay=True)
+ st.session_state.ea_architecture_mode = "reflection"
+
+ _render_top_navigation(st)
+
+ assert st.session_state.ea_visual_view == "trace"
+ assert st.session_state.ea_architecture_mode == "reflection"
+ assert st.rerun_called is True
+
+
+def test_research_view_can_return_to_current_architecture():
+ st = _NavigationStub(selected="Reflection", architecture=True)
+ st.session_state.ea_architecture_mode = "reflection"
+ st.session_state.ea_visual_view = "trace"
+
+ _render_top_navigation(st)
+
+ assert st.session_state.ea_visual_view == "architecture"
+ assert st.session_state.ea_architecture_mode == "reflection"
+ assert st.rerun_called is True
diff --git a/tests/test_visual_settings.py b/tests/test_visual_settings.py
index 540c12a..2bfbc10 100644
--- a/tests/test_visual_settings.py
+++ b/tests/test_visual_settings.py
@@ -118,17 +118,18 @@ def test_visual_agent_config_drops_invalid_override_container(tmp_path):
assert "tool_description_overrides" not in load_visual_agent_config(path)
-
def test_visual_agent_config_filters_invalid_values(tmp_path):
path = tmp_path / "agent.json"
path.write_text(
json.dumps(
{
"agent": {
- "name": 123,
+ "name": " ",
+ "instructions": "",
"max_iterations": 99,
"selected_tools": "calculate",
"custom_tool_files": ["../outside.py", "valid.py", 3],
+ "agent_mode": "安全模式",
}
}
),
diff --git a/tests/test_visual_teaching.py b/tests/test_visual_teaching.py
new file mode 100644
index 0000000..e8bfa1c
--- /dev/null
+++ b/tests/test_visual_teaching.py
@@ -0,0 +1,262 @@
+"""Contract tests for the deterministic visual teaching experiments."""
+
+from __future__ import annotations
+
+import json
+from typing import Any
+
+import pytest
+
+from agentmold.agent import AgentTrace
+from agentmold.exceptions import ConfigurationError, LLMError
+from agentmold.llm import LlmProvider, LlmResponse, create_llm
+from agentmold.visual.teaching import (
+ ARCHITECTURE_MODES,
+ ScriptedLLM,
+ TeachingEvent,
+ TeachingExperiment,
+ run_multi_agent_experiment,
+ run_plan_execute_experiment,
+ run_reflection_experiment,
+ run_routing_experiment,
+ run_teaching_experiment,
+ source_code,
+ traces_to_jsonl,
+)
+from agentmold.visual.traces import parse_trace_jsonl
+
+
+@pytest.mark.parametrize(
+ ("mode", "trace_count", "expected_output"),
+ [
+ ("react", 1, "ReAct result"),
+ ("plan_execute", 5, "Plan-and-Execute result"),
+ ("reflection", 4, "Revised answer"),
+ ("multi_agent", 3, "Multi-Agent result"),
+ ("routing", 2, "Coder result"),
+ ],
+)
+def test_all_teaching_modes_run_real_agents_offline(
+ mode: str,
+ trace_count: int,
+ expected_output: str,
+) -> None:
+ experiment = run_teaching_experiment(mode)
+
+ assert experiment.mode == mode
+ assert experiment.input == ARCHITECTURE_MODES[mode]["sample_input"]
+ assert expected_output in experiment.output
+ assert experiment.events
+ assert len(experiment.traces) == trace_count
+ assert all(isinstance(trace, AgentTrace) for trace in experiment.traces)
+ assert all(trace.status == "completed" for trace in experiment.traces)
+ assert all(trace.model == "teaching-scripted" for trace in experiment.traces)
+ assert len({trace.run_id for trace in experiment.traces}) == trace_count
+
+
+def test_architecture_modes_have_stable_display_and_preset_data() -> None:
+ assert list(ARCHITECTURE_MODES) == [
+ "react",
+ "plan_execute",
+ "reflection",
+ "multi_agent",
+ "routing",
+ ]
+ assert all(
+ set(mode) == {"label", "sample_input", "preset_key"} for mode in ARCHITECTURE_MODES.values()
+ )
+ assert [mode["preset_key"] for mode in ARCHITECTURE_MODES.values()] == [
+ "ReAct(推理-行动)",
+ "Plan-and-Execute(计划-执行)",
+ "Reflection(反思)",
+ "Multi-Agent(多智能体协作)",
+ "Routing(路由分发)",
+ ]
+
+
+def test_scripted_llm_is_explicit_finite_and_not_a_registered_provider() -> None:
+ llm = ScriptedLLM([LlmResponse(content="only response")])
+
+ assert llm.complete([]).content == "only response"
+ assert llm.remaining == 0
+ with pytest.raises(LLMError, match="queue exhausted"):
+ llm.complete([])
+ with pytest.raises(ConfigurationError, match="Unknown LLM provider"):
+ create_llm({"provider": "teaching-scripted", "model": "offline"})
+ assert "teaching-scripted" not in LlmProvider._registry
+
+
+def test_react_records_one_real_retrieve_round() -> None:
+ experiment = run_teaching_experiment("react", "Explain grounded answers")
+ trace = experiment.traces[0]
+
+ assert [step["type"] for step in trace.steps] == [
+ "tool_call",
+ "tool_result",
+ "answer",
+ ]
+ assert trace.tool_calls[0]["name"] == "retrieve"
+ assert trace.tool_calls[0]["arguments"] == {"query": "Explain grounded answers"}
+ assert [event.type for event in experiment.events] == [
+ "agent_started",
+ "agent_completed",
+ ]
+
+
+def test_plan_execute_preserves_every_planned_step_with_a_fresh_worker() -> None:
+ experiment = run_plan_execute_experiment("Design an offline assistant")
+ plan = experiment.metadata["plan"]
+ step_results = experiment.metadata["step_results"]
+
+ assert isinstance(plan, list) and len(plan) == 3
+ assert isinstance(step_results, list) and len(step_results) == 3
+ assert [trace.agent_name for trace in experiment.traces] == [
+ "Planner",
+ "Worker 1",
+ "Worker 2",
+ "Worker 3",
+ "Synthesizer",
+ ]
+ assert [trace.user_input for trace in experiment.traces[1:4]] == plan
+ assert all(str(result) in experiment.output for result in step_results)
+ assert [
+ event.data["step_index"] for event in experiment.events if event.type == "step_completed"
+ ] == [
+ 1,
+ 2,
+ 3,
+ ]
+
+
+def test_reflection_stops_after_one_feedback_round_and_done() -> None:
+ experiment = run_reflection_experiment("Explain vector retrieval")
+
+ assert [trace.agent_name for trace in experiment.traces] == [
+ "Generator",
+ "Critic",
+ "Generator",
+ "Critic",
+ ]
+ assert [event.type for event in experiment.events].count("feedback_received") == 1
+ assert experiment.events[-1].type == "reflection_done"
+ assert experiment.events[-1].content == "DONE"
+ assert experiment.metadata == {"feedback_rounds": 1, "critic_status": "DONE"}
+ final_step = experiment.traces[-1].steps[-1]
+ assert final_step["type"] == "answer"
+ assert final_step["content"] == "DONE"
+ assert "Revised answer" in experiment.output
+
+
+@pytest.mark.parametrize(
+ ("prompt", "expected_expert"),
+ [
+ ("Write a Python function", "Coder"),
+ ("Draft a product paragraph", "Writer"),
+ ("Calculate 12 + 30", "Math"),
+ ],
+)
+def test_routing_runs_router_and_only_the_selected_expert(
+ prompt: str,
+ expected_expert: str,
+) -> None:
+ experiment = run_routing_experiment(prompt)
+
+ assert [trace.agent_name for trace in experiment.traces] == ["Router", expected_expert]
+ assert experiment.metadata["route_selected"] == expected_expert
+ route_events = [event for event in experiment.events if event.type == "route_selected"]
+ assert len(route_events) == 1
+ assert route_events[0].content == expected_expert
+ assert route_events[0].data["expert"] == expected_expert
+ assert expected_expert in experiment.output
+
+
+@pytest.mark.asyncio
+async def test_multi_agent_has_two_correlated_parallel_child_traces() -> None:
+ experiment = await run_multi_agent_experiment_inside_event_loop()
+ parent, researcher, analyst = experiment.traces
+ calls = parent.tool_calls
+
+ assert [trace.agent_name for trace in experiment.traces] == [
+ "Coordinator",
+ "Researcher",
+ "Analyst",
+ ]
+ assert [call["id"] for call in calls] == [
+ "research-delegation",
+ "analysis-delegation",
+ ]
+ assert len({call["parallel_group"] for call in calls}) == 1
+ assert all(call["parallel_group"] == f"{parent.run_id}:1" for call in calls)
+ assert parent.child_run_ids == [researcher.run_id, analyst.run_id]
+ assert researcher.parent_run_id == parent.run_id
+ assert analyst.parent_run_id == parent.run_id
+ assert researcher.parent_tool_call_id == "research-delegation"
+ assert analyst.parent_tool_call_id == "analysis-delegation"
+ assert all(trace.parent_run_id is not None for trace in (researcher, analyst))
+
+
+async def run_multi_agent_experiment_inside_event_loop() -> TeachingExperiment:
+ """Exercise the synchronous public entry point while this test loop is active."""
+
+ return run_multi_agent_experiment("Compare exact and semantic retrieval")
+
+
+def test_teaching_data_and_trace_jsonl_are_strict_and_round_trip() -> None:
+ experiment = run_multi_agent_experiment("Compare retrieval methods")
+
+ payload = experiment.to_dict()
+ assert json.loads(experiment.to_json()) == payload
+ text = experiment.traces_to_jsonl()
+ assert text == traces_to_jsonl(experiment.traces)
+ assert all(isinstance(json.loads(line), dict) for line in text.splitlines())
+ replayed = parse_trace_jsonl(text)
+ assert [run["run_id"] for run in replayed] == [trace.run_id for trace in experiment.traces]
+ assert replayed[1]["parent_run_id"] == replayed[0]["run_id"]
+ assert replayed[2]["parent_run_id"] == replayed[0]["run_id"]
+
+
+@pytest.mark.parametrize(
+ ("bad_data", "error"),
+ [({"object": object()}, TypeError), ({"number": float("nan")}, ValueError)],
+)
+def test_teaching_event_rejects_non_json_values(
+ bad_data: dict[str, Any],
+ error: type[Exception],
+) -> None:
+ event = TeachingEvent("bad", "test", data=bad_data)
+
+ with pytest.raises(error):
+ event.to_dict()
+ with pytest.raises(error):
+ event.to_json()
+
+
+def test_experiment_rejects_non_json_metadata() -> None:
+ experiment = run_teaching_experiment("react")
+ experiment.metadata["unsupported"] = object()
+
+ with pytest.raises(TypeError, match="Unsupported JSON value"):
+ experiment.to_dict()
+
+
+def test_exported_sources_compile_and_run_offline(
+ capsys: pytest.CaptureFixture[str],
+) -> None:
+ for mode in ARCHITECTURE_MODES:
+ recipe = source_code(mode)
+ namespace: dict[str, Any] = {}
+ exec(compile(recipe, f"<{mode}-teaching-recipe>", "exec"), namespace)
+ exported = namespace["experiment"]
+ assert isinstance(exported, TeachingExperiment)
+ assert exported.mode == mode
+
+ output = capsys.readouterr().out
+ assert "ReAct result" in output
+ assert "Multi-Agent result" in output
+
+
+def test_unknown_mode_fails_with_available_modes() -> None:
+ with pytest.raises(ValueError, match="Available modes"):
+ run_teaching_experiment("unknown")
+ with pytest.raises(ValueError, match="Available modes"):
+ source_code("unknown")
diff --git a/tests/test_visual_teaching_models.py b/tests/test_visual_teaching_models.py
new file mode 100644
index 0000000..c4f2c93
--- /dev/null
+++ b/tests/test_visual_teaching_models.py
@@ -0,0 +1,124 @@
+"""Tests for resolving live teaching model configuration."""
+
+from __future__ import annotations
+
+from agentmold.visual.teaching_models import (
+ resolve_live_teaching_model,
+ resolve_live_teaching_models,
+)
+
+
+def test_mock_profile_is_not_a_live_teaching_model() -> None:
+ model, error = resolve_live_teaching_model(
+ "Mock(离线)",
+ "OpenAI 兼容",
+ "Mock(离线)",
+ {"model": "mock"},
+ )
+
+ assert model is None
+ assert error is not None and "不能驱动真实架构决策" in error
+
+
+def test_saved_openai_profile_resolves_without_exposing_api_key() -> None:
+ model, error = resolve_live_teaching_model(
+ "OpenAI 兼容",
+ "OpenAI 兼容",
+ "OpenAI 兼容",
+ {
+ "model": "teaching-model",
+ "api_key": "secret-key",
+ "base_url": "https://llm.example/v1",
+ "temperature": 0.1,
+ "timeout": 45,
+ "max_tokens": 2048,
+ },
+ )
+
+ assert error is None
+ assert model is not None
+ assert model.key == "OpenAI 兼容"
+ assert model.label == "OpenAI 兼容 · openai / teaching-model"
+ assert "secret-key" not in model.label
+ assert model.config == {
+ "provider": "openai",
+ "model": "teaching-model",
+ "api_key": "secret-key",
+ "base_url": "https://llm.example/v1",
+ "temperature": 0.1,
+ "timeout": 45.0,
+ "max_retries": 3,
+ "retry_delay": 2.0,
+ }
+
+
+def test_saved_ollama_profile_is_a_live_local_model() -> None:
+ model, error = resolve_live_teaching_model(
+ "Ollama(本地)",
+ "OpenAI 兼容",
+ "Ollama(本地)",
+ {
+ "model": "qwen-local",
+ "base_url": "http://localhost:11434",
+ "temperature": 0.0,
+ },
+ )
+
+ assert error is None
+ assert model is not None
+ assert model.label == "Ollama(本地) · ollama / qwen-local"
+ assert model.config == {
+ "provider": "ollama",
+ "model": "qwen-local",
+ "host": "http://localhost:11434",
+ "temperature": 0.0,
+ }
+
+
+def test_all_non_mock_profiles_are_available_and_current_profile_is_first() -> None:
+ models, errors = resolve_live_teaching_models(
+ {"connection_type": "Ollama(本地)"},
+ {
+ "Mock(离线)": {"model": "mock"},
+ "OpenAI 兼容": {"model": "remote-model"},
+ "Ollama(本地)": {"model": "local-model"},
+ },
+ )
+
+ assert errors == []
+ assert [model.key for model in models] == ["Ollama(本地)", "OpenAI 兼容"]
+
+
+def test_custom_provider_profile_uses_its_saved_interface() -> None:
+ models, errors = resolve_live_teaching_models(
+ {
+ "connection_type": "自定义提供商",
+ "custom_interface": "Anthropic 兼容",
+ },
+ {
+ "自定义提供商:Anthropic 兼容": {
+ "model": "custom-model",
+ "base_url": "https://custom.example",
+ }
+ },
+ )
+
+ assert errors == []
+ assert models[0].key == "自定义提供商:Anthropic 兼容"
+ assert models[0].config["provider"] == "anthropic"
+
+
+def test_missing_or_invalid_saved_profile_is_actionable() -> None:
+ missing_models, missing_errors = resolve_live_teaching_models(
+ {"connection_type": "Anthropic 兼容"},
+ {},
+ )
+ invalid_models, invalid_errors = resolve_live_teaching_models(
+ {"connection_type": "OpenAI 兼容"},
+ {"OpenAI 兼容": {"model": "gpt", "temperature": "bad"}},
+ )
+
+ assert missing_models == []
+ assert missing_errors == []
+ assert invalid_models == []
+ assert invalid_errors and "数值参数无效" in invalid_errors[0]
diff --git a/tests/test_visual_traces.py b/tests/test_visual_traces.py
index 573eebb..49562ff 100644
--- a/tests/test_visual_traces.py
+++ b/tests/test_visual_traces.py
@@ -6,6 +6,7 @@
from agentmold.visual.traces import (
append_trace_run,
+ build_trace_forest,
diagnose_trace_run,
find_trace_run,
load_trace_runs,
@@ -13,6 +14,8 @@
parse_trace_jsonl,
summarize_trace_run,
summarize_usage,
+ trace_family_from_forest,
+ trace_family_order,
trace_label,
traces_to_jsonl,
)
@@ -68,6 +71,29 @@ def test_summary_normalizes_metrics_and_label():
assert "research-model" in trace_label(run)
+def test_summary_uses_trace_v2_status_and_model_rounds():
+ summary = summarize_trace_run(
+ {
+ "trace_version": 2,
+ "run_id": "trace-v2",
+ "status": "interrupted",
+ "ended_at": "now",
+ "model_calls": [
+ {"round": 1, "status": "completed"},
+ {"round": 2, "status": "interrupted"},
+ ],
+ "events": [],
+ }
+ )
+
+ assert summary["status"] == "interrupted"
+ assert summary["rounds"] == 2
+
+ legacy = summarize_trace_run({"run_id": "legacy", "ended_at": "now", "events": []})
+ assert legacy["status"] == "complete"
+ assert legacy["rounds"] is None
+
+
def test_summary_includes_tool_schema_descriptions_and_fingerprint():
summary = summarize_trace_run(
{
@@ -84,12 +110,9 @@ def test_summary_includes_tool_schema_descriptions_and_fingerprint():
}
)
- assert summary["tool_descriptions"] == {
- "retrieve": "Search private documents first."
- }
+ assert summary["tool_descriptions"] == {"retrieve": "Search private documents first."}
assert len(summary["tool_schema_fingerprint"]) == 12
-
summary = summarize_trace_run(
{
"run_id": "cached",
@@ -126,6 +149,61 @@ def test_usage_summary_handles_nested_cached_token_fields():
assert summary["cache_hit_rate"] == pytest.approx(0.2)
+def test_build_trace_forest_groups_children_and_orphans():
+ runs = [
+ {"run_id": "root", "started_at": "1", "events": []},
+ {
+ "run_id": "child-b",
+ "parent_run_id": "root",
+ "parent_tool_call_id": "call-b",
+ "started_at": "3",
+ "events": [],
+ },
+ {
+ "run_id": "child-a",
+ "parent_run_id": "root",
+ "parent_tool_call_id": "call-a",
+ "started_at": "2",
+ "events": [],
+ },
+ {
+ "run_id": "grandchild",
+ "parent_run_id": "child-a",
+ "parent_tool_call_id": "call-c",
+ "started_at": "4",
+ "events": [],
+ },
+ {
+ "run_id": "orphan",
+ "parent_run_id": "missing",
+ "started_at": "5",
+ "events": [],
+ },
+ ]
+
+ forest = build_trace_forest(runs)
+ assert [run["run_id"] for run in forest["roots"]] == ["root"]
+ assert [run["run_id"] for run in forest["children"]["root"]] == [
+ "child-a",
+ "child-b",
+ ]
+ assert [run["run_id"] for run in forest["orphans"]] == ["orphan"]
+ assert [run["run_id"] for run in trace_family_from_forest(forest, "root")] == [
+ "root",
+ "child-a",
+ "grandchild",
+ "child-b",
+ ]
+ assert trace_family_order(forest) == [
+ ("root", 0),
+ ("child-a", 1),
+ ("grandchild", 2),
+ ("child-b", 1),
+ ("orphan", 0),
+ ]
+ assert trace_family_from_forest(forest, "missing") == []
+
+
def test_trace_log_round_trip_and_prefix_lookup(tmp_path):
path = tmp_path / "visual_runs.jsonl"
run = {